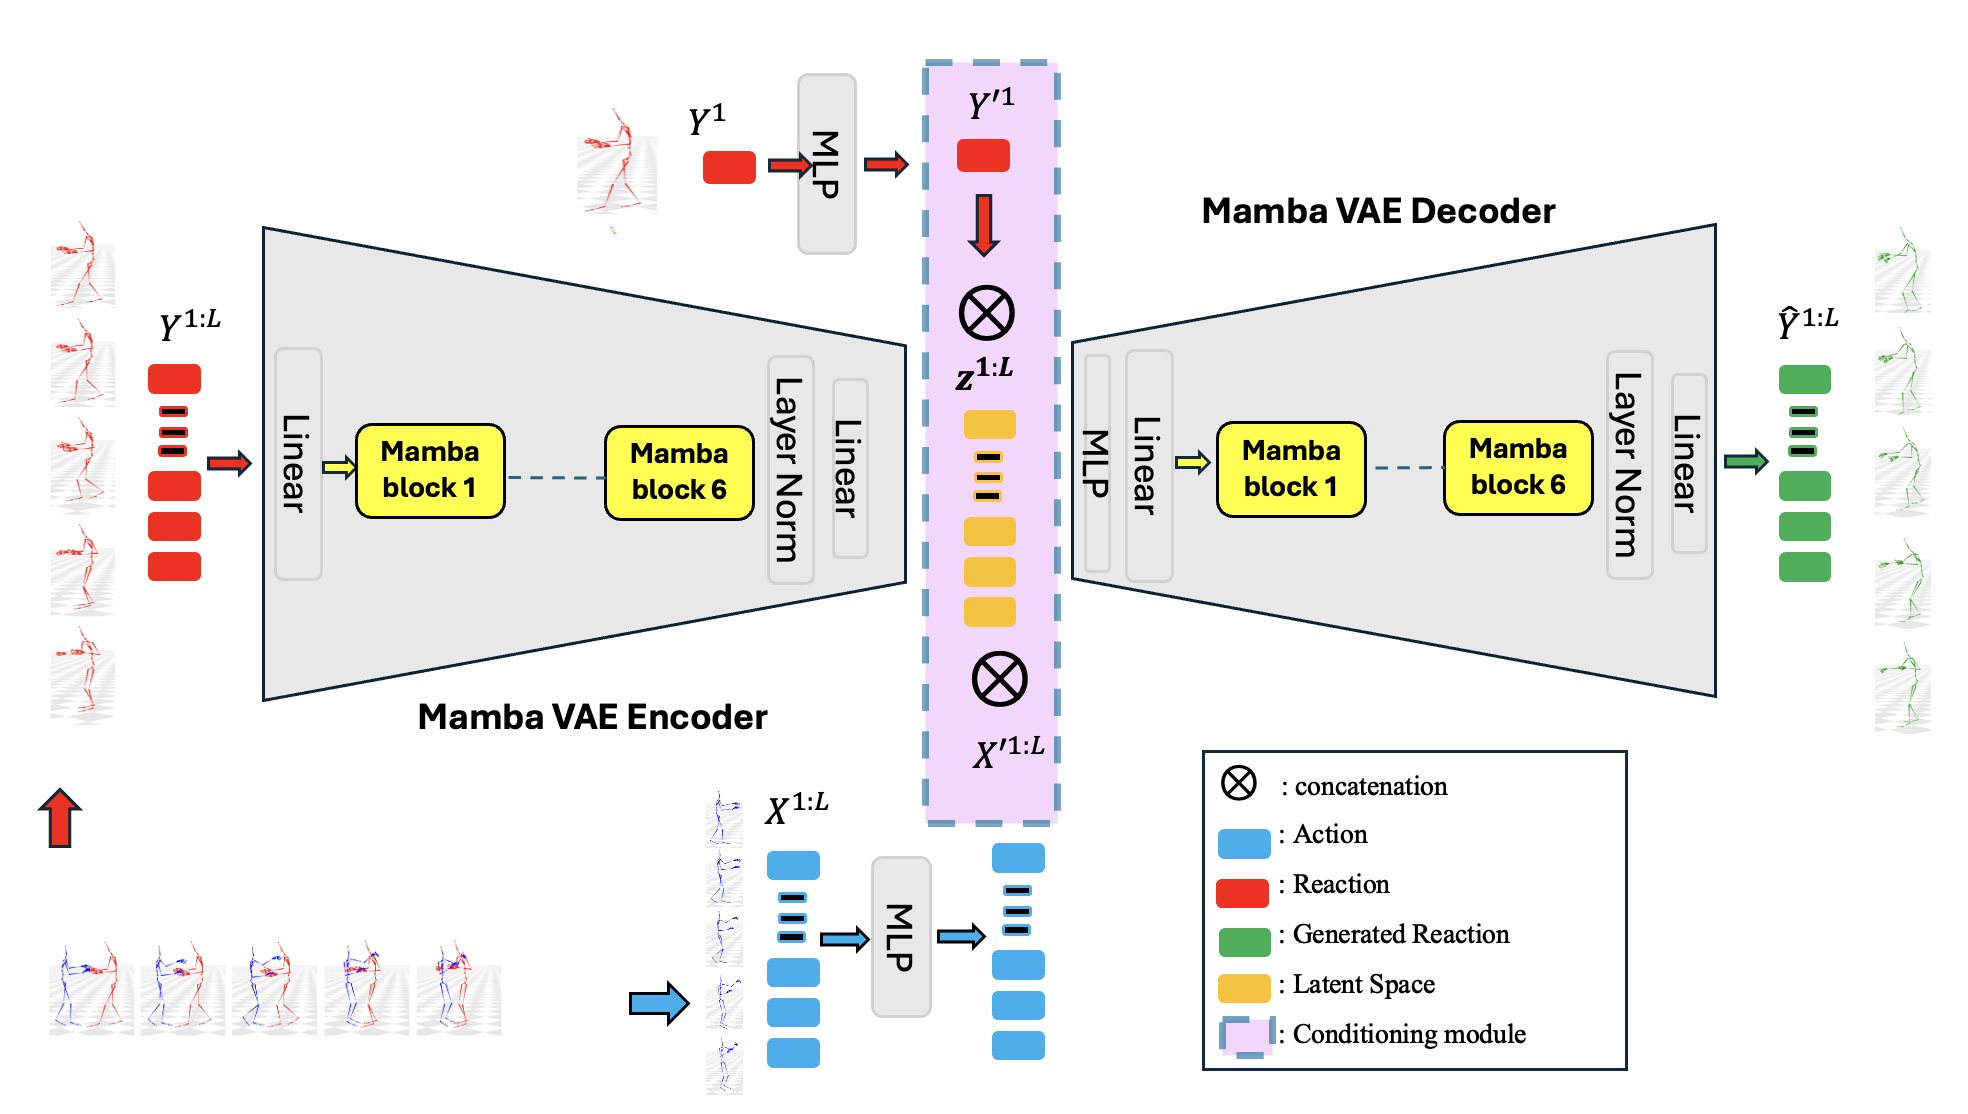
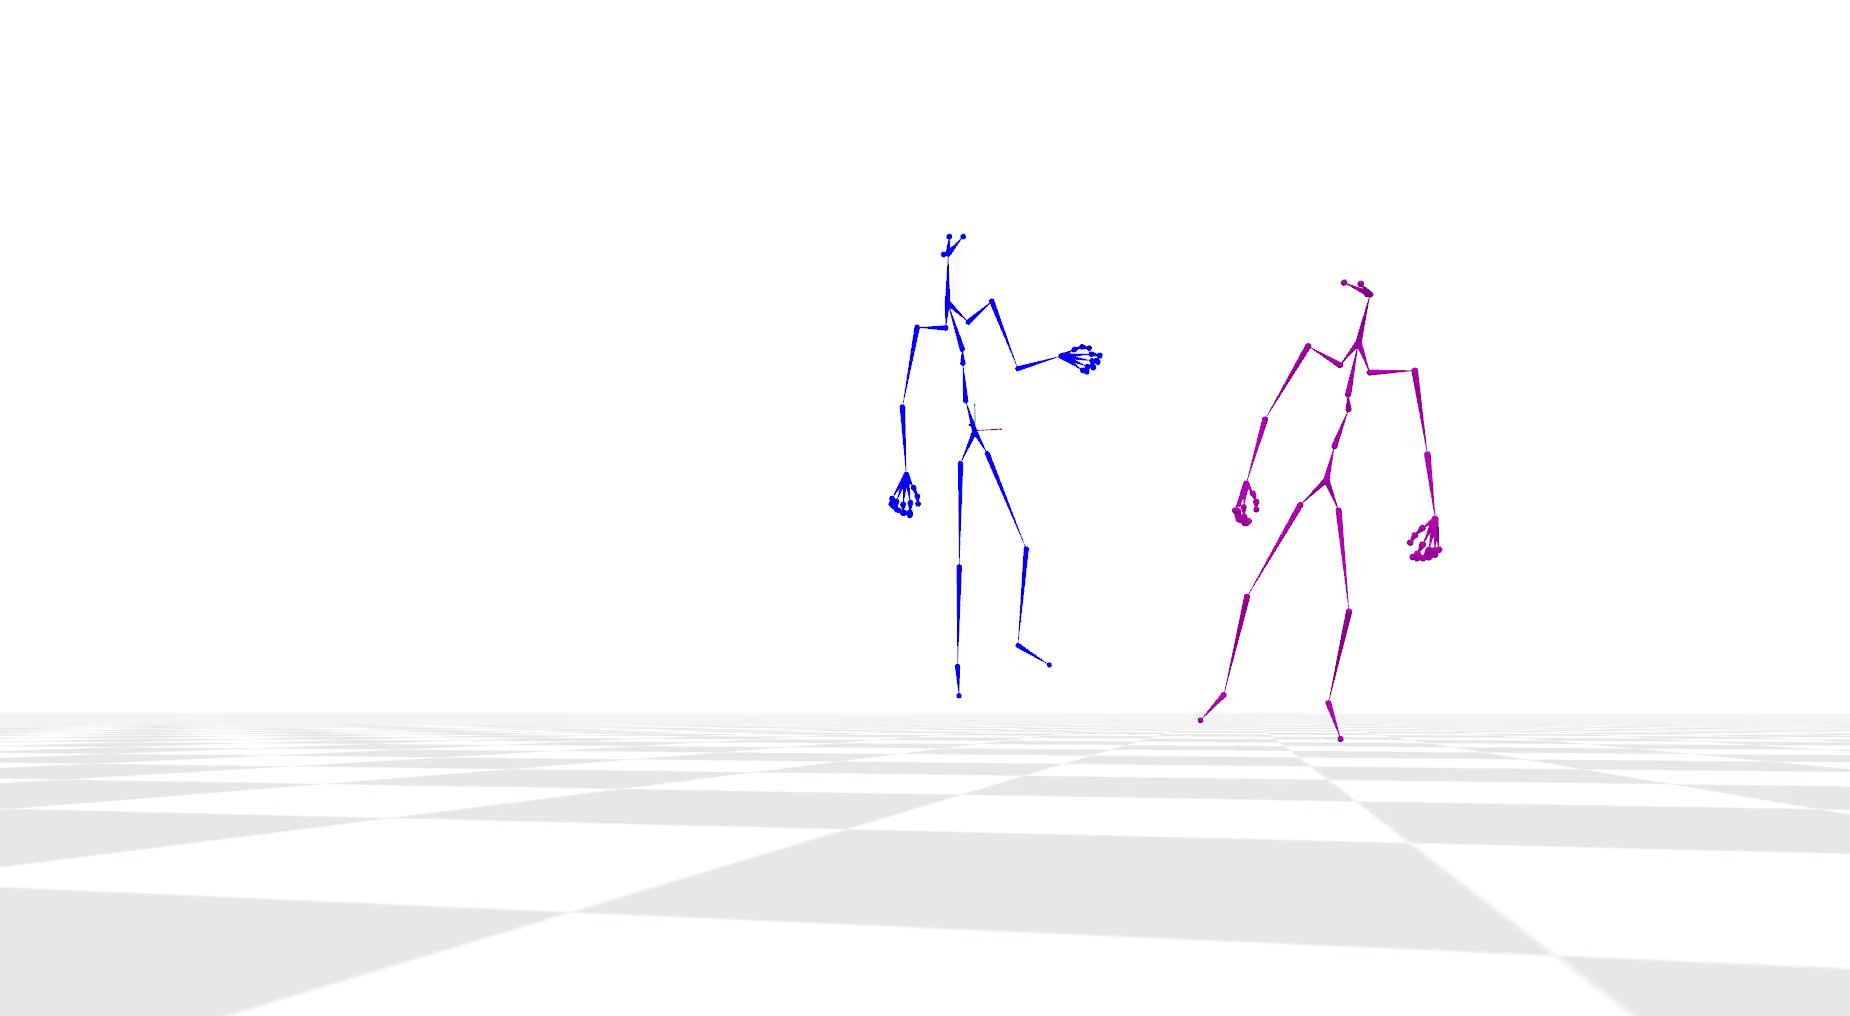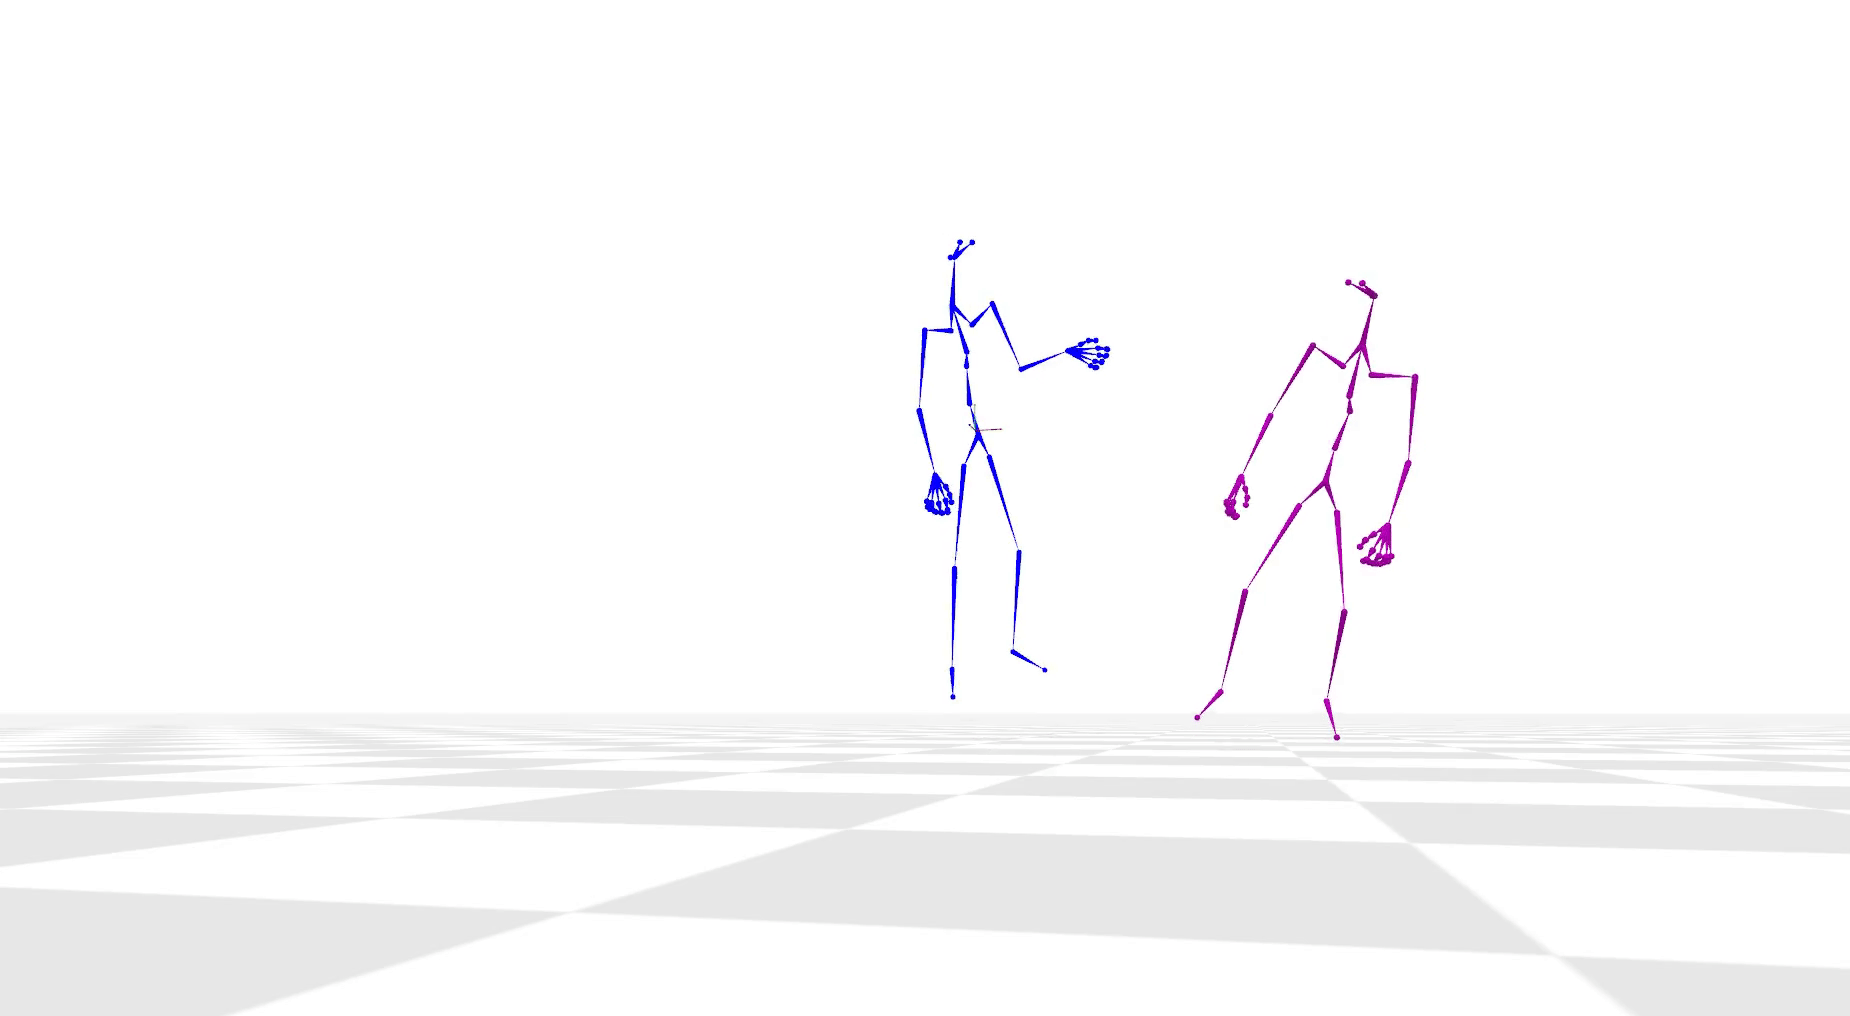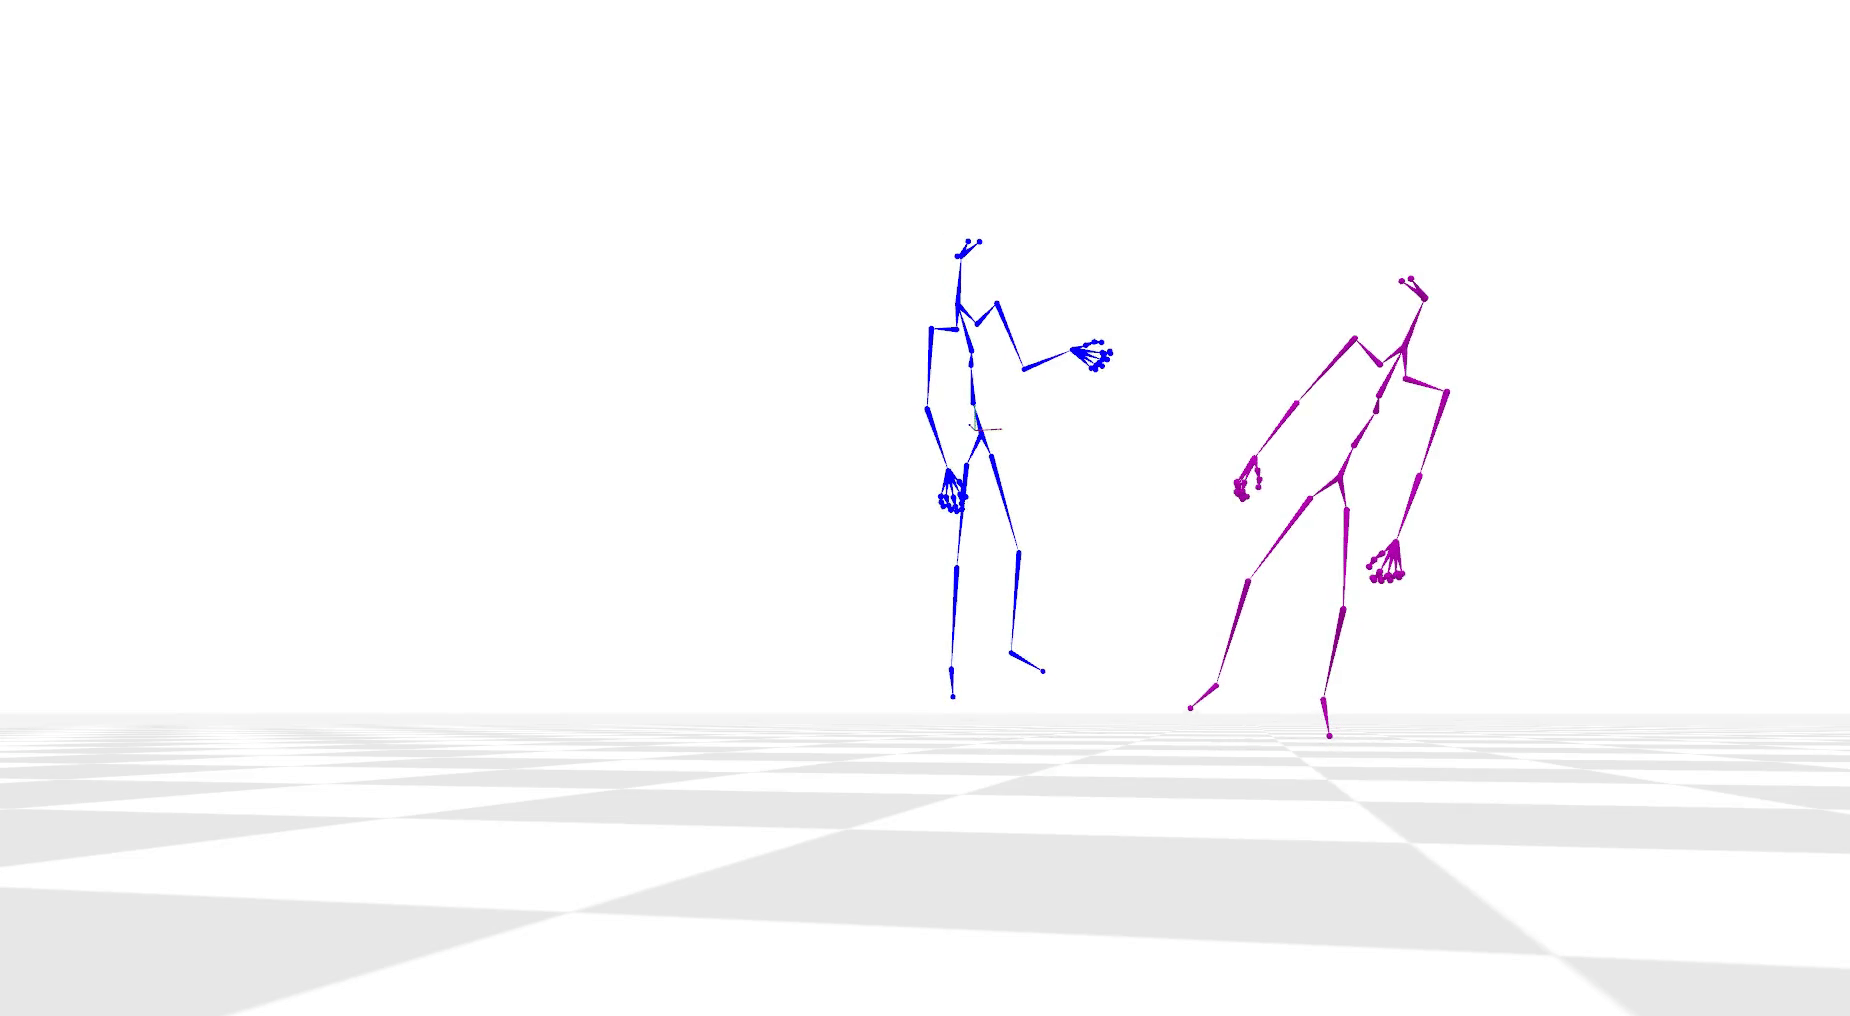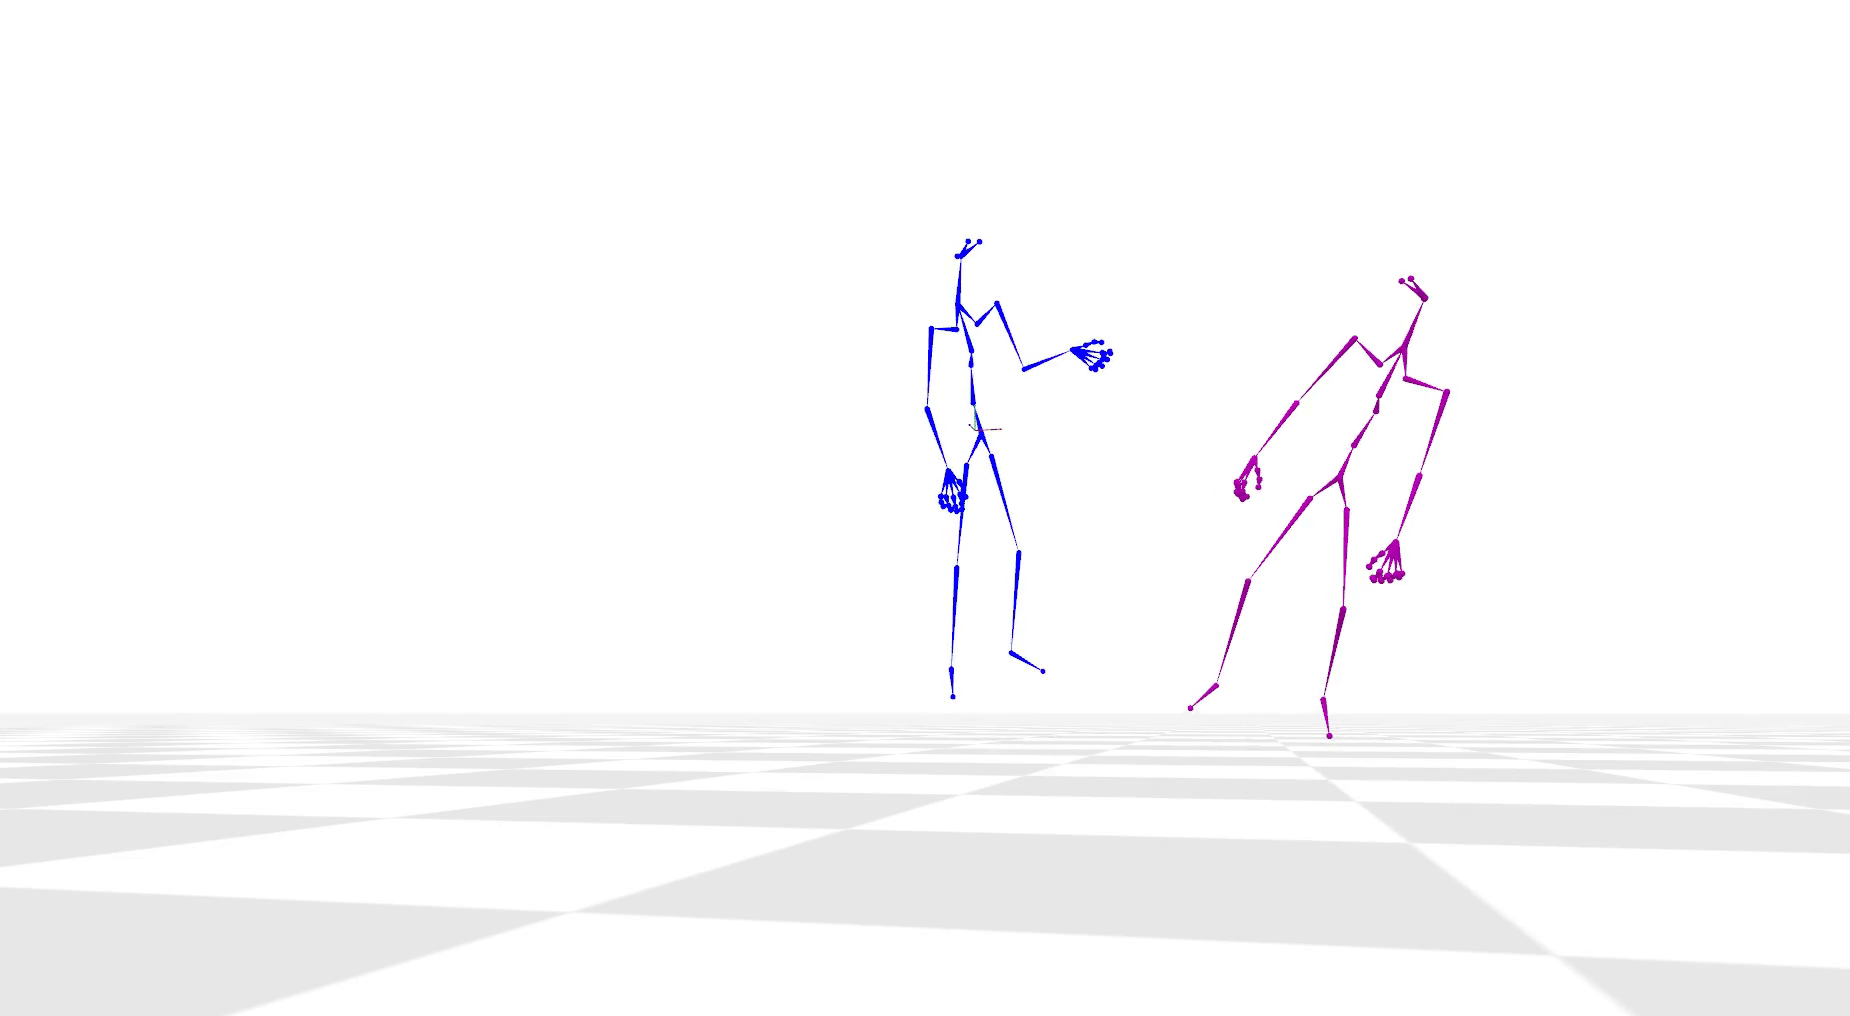
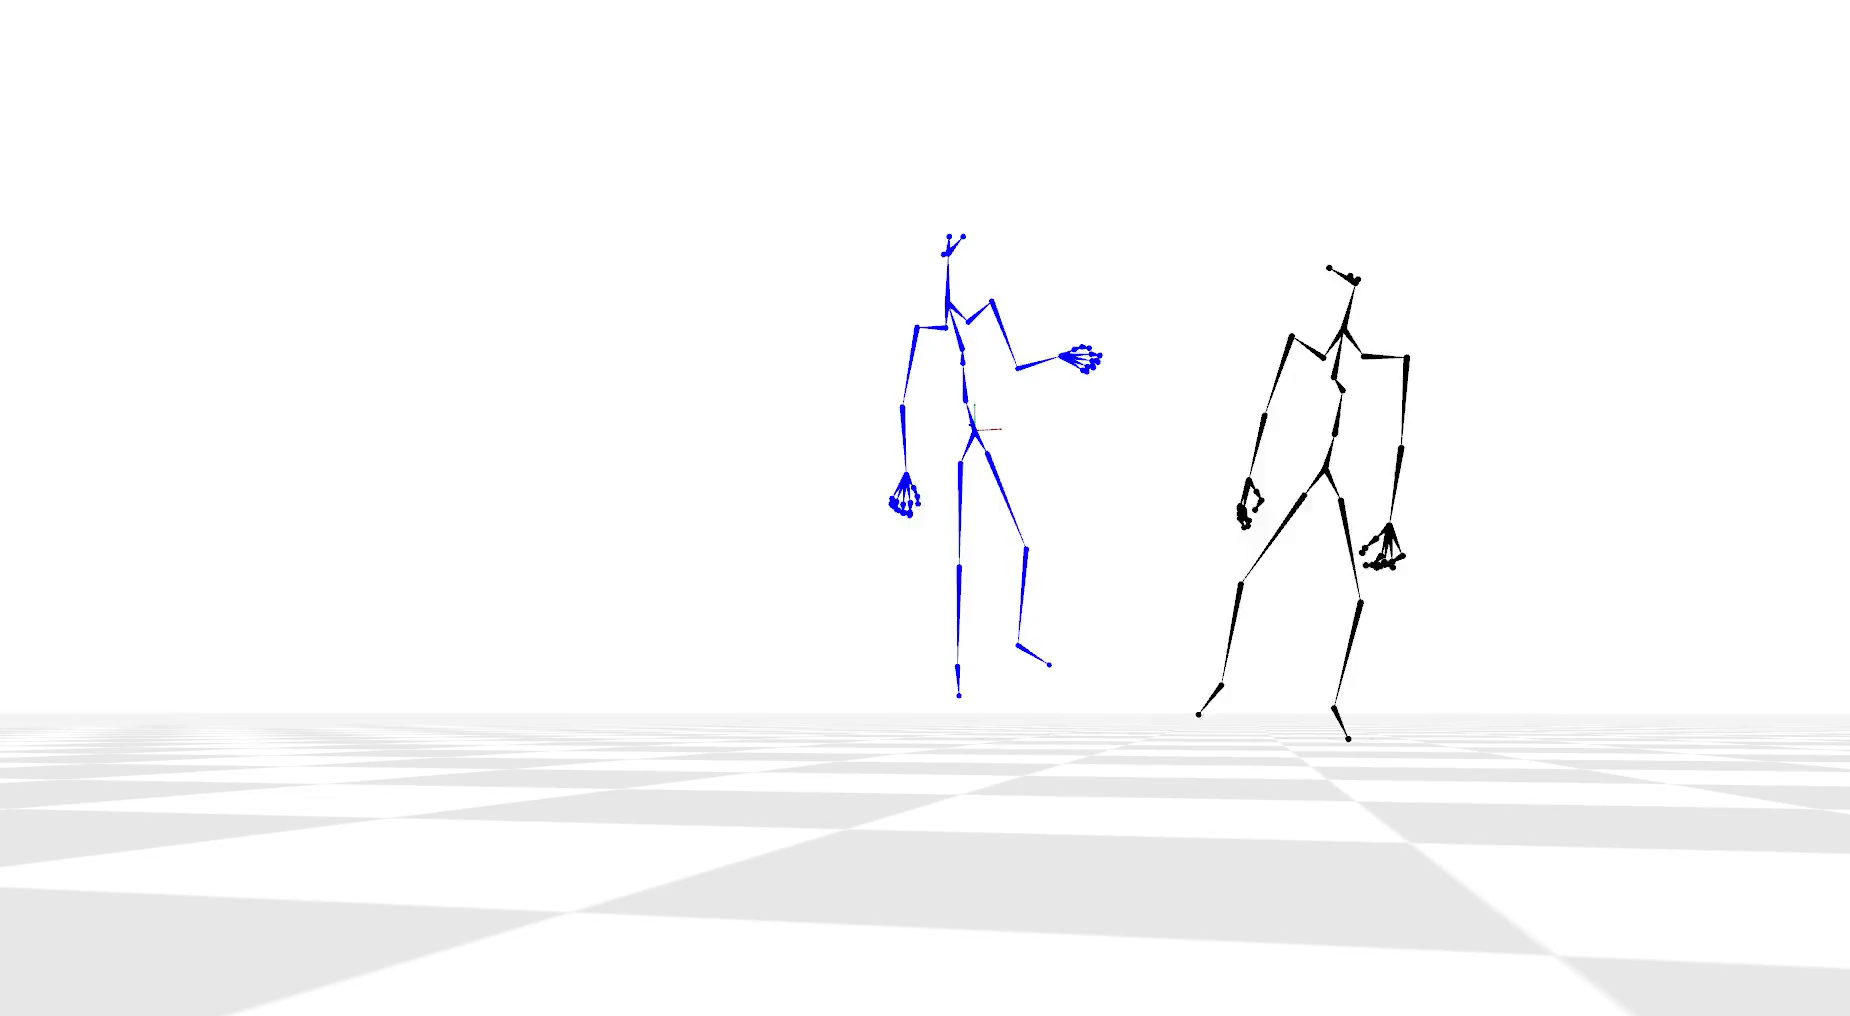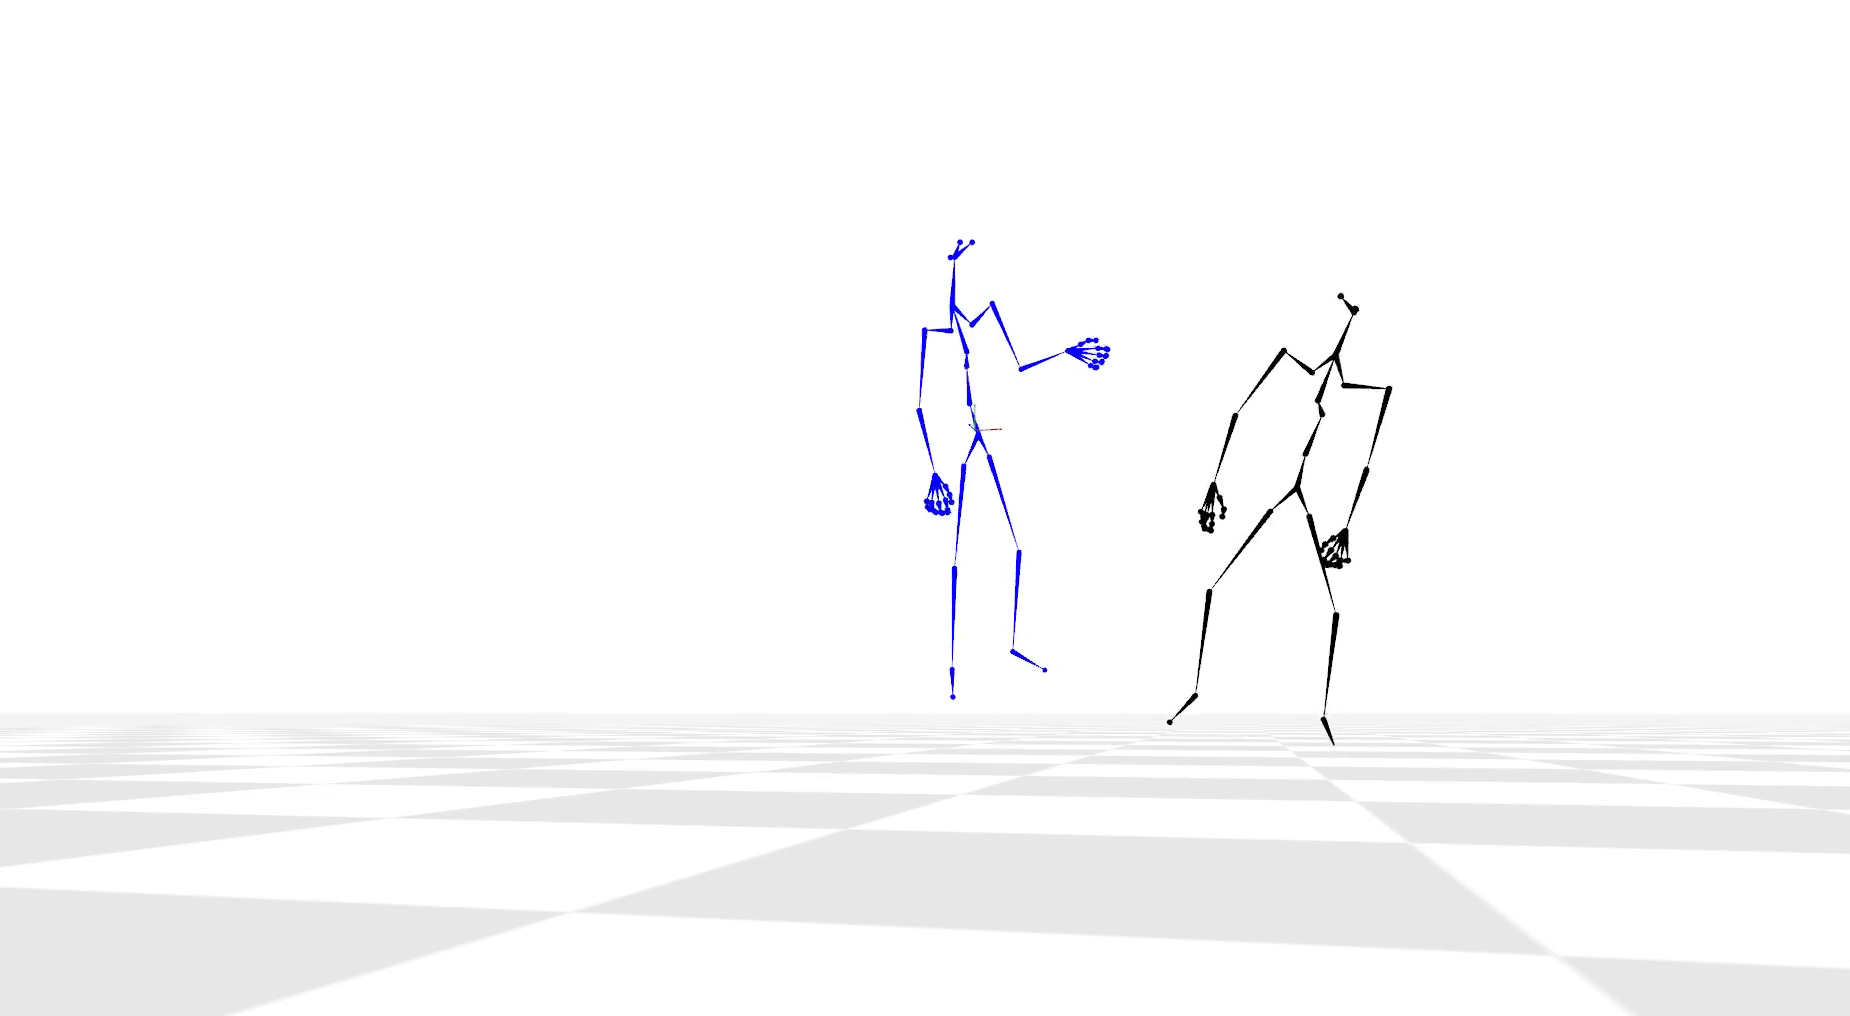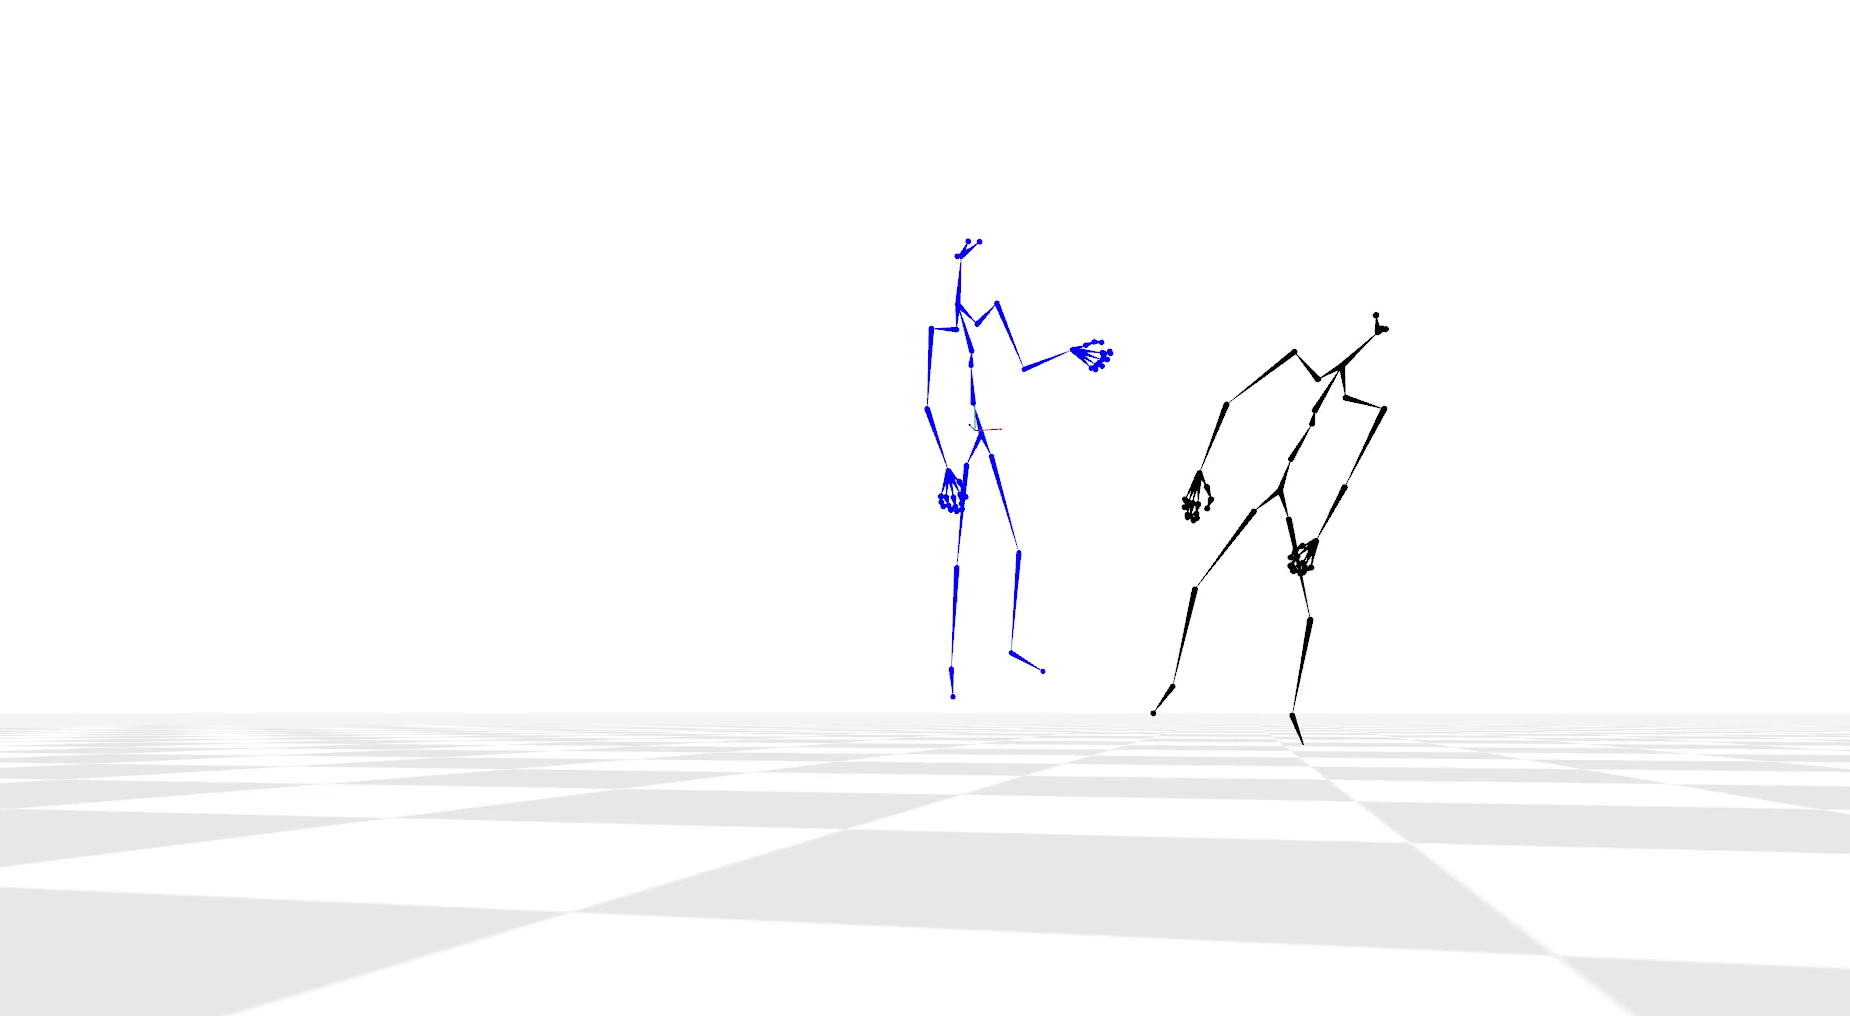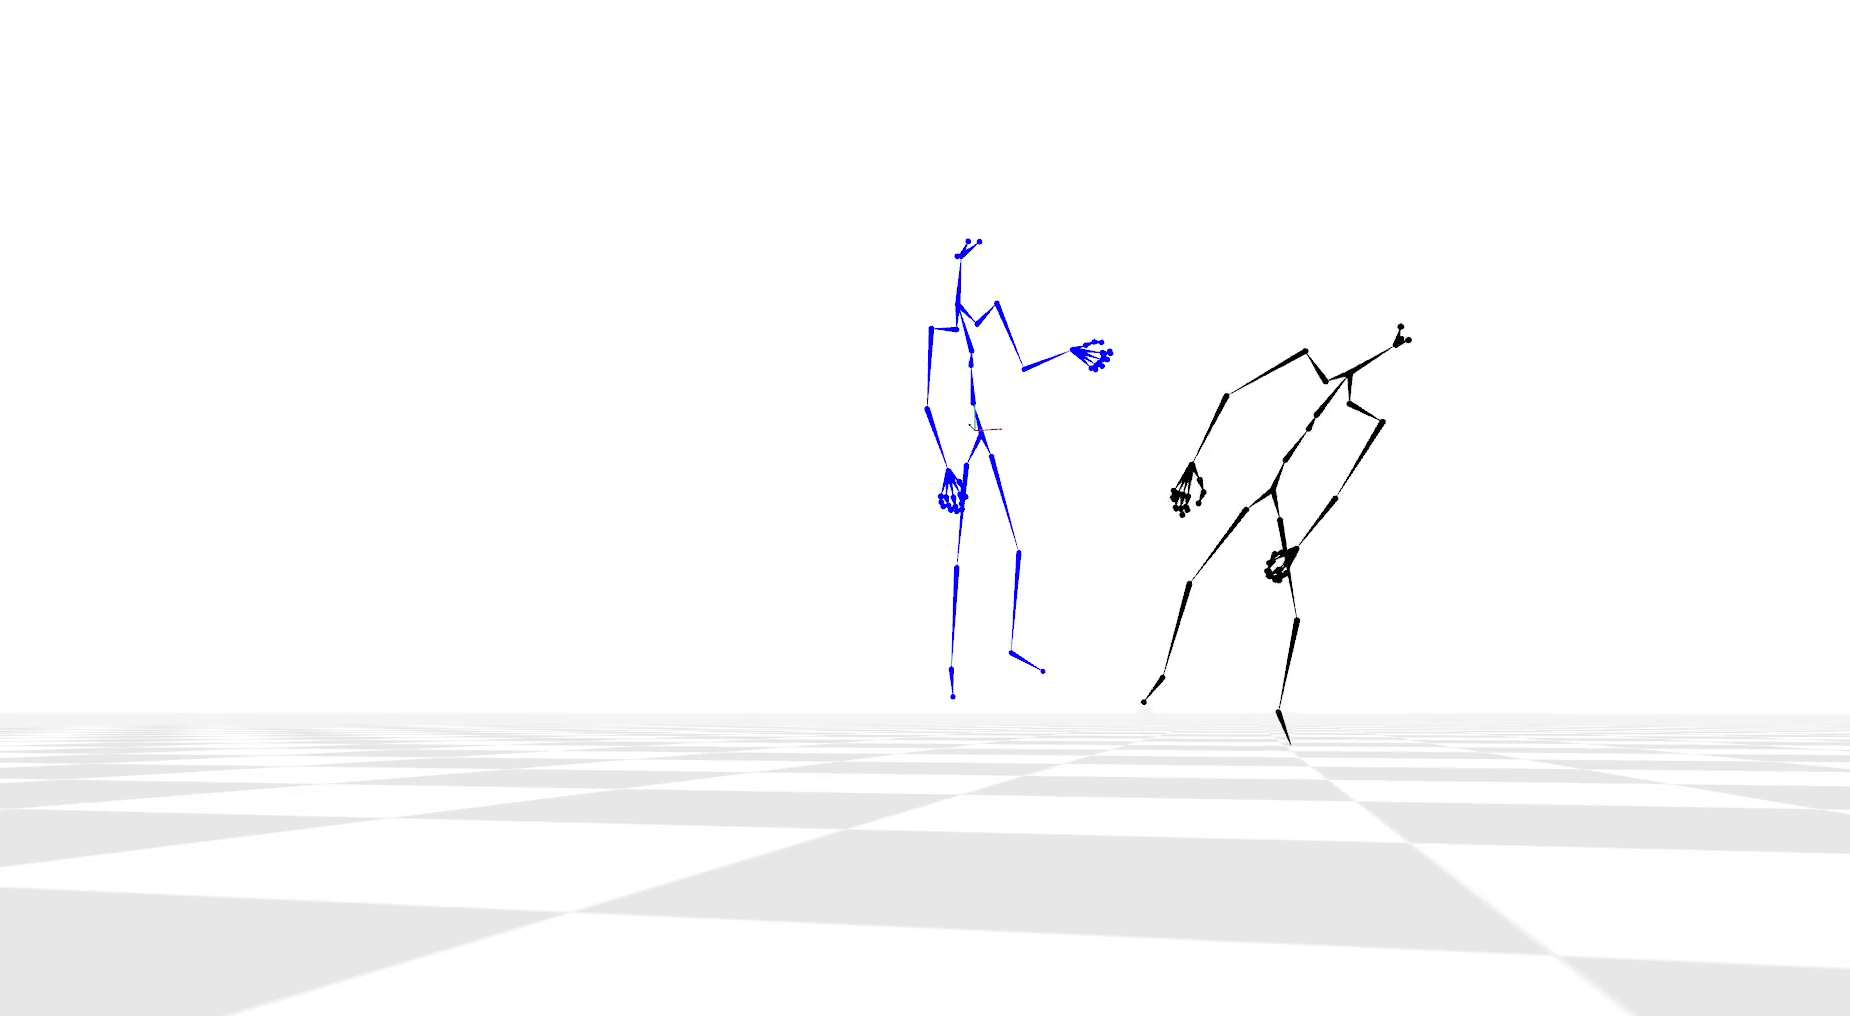
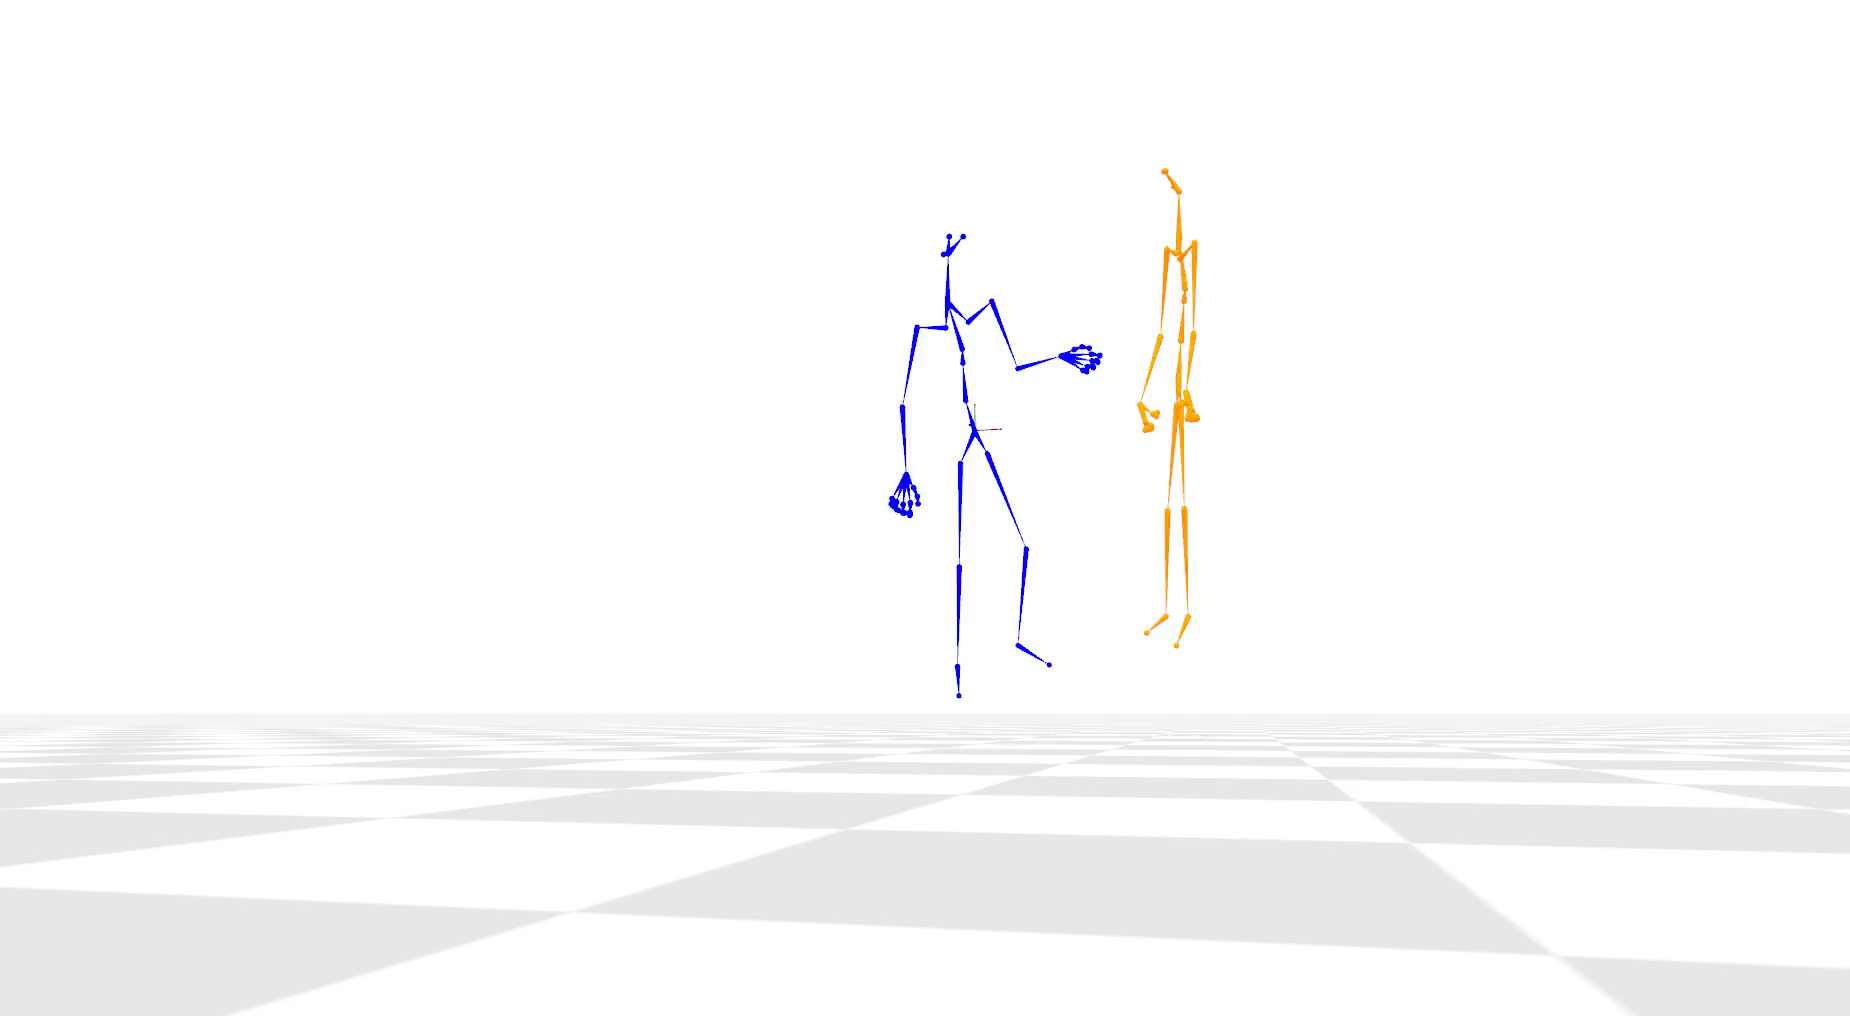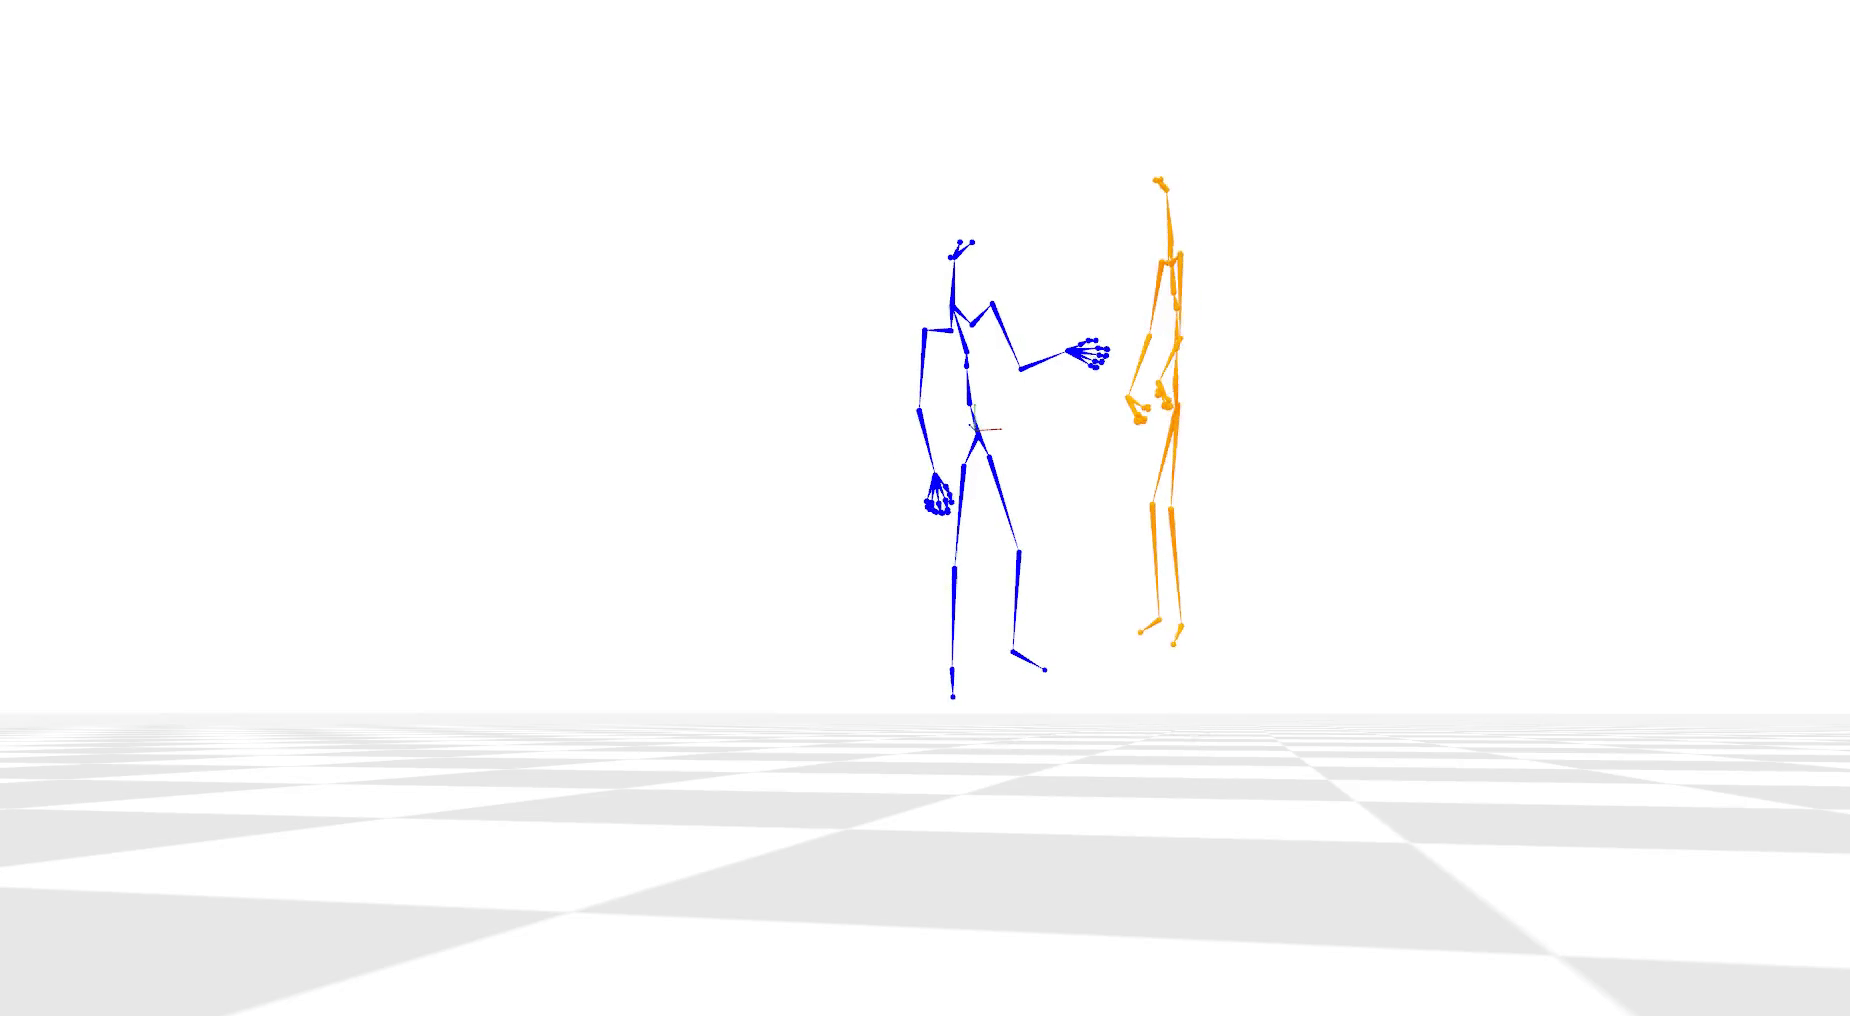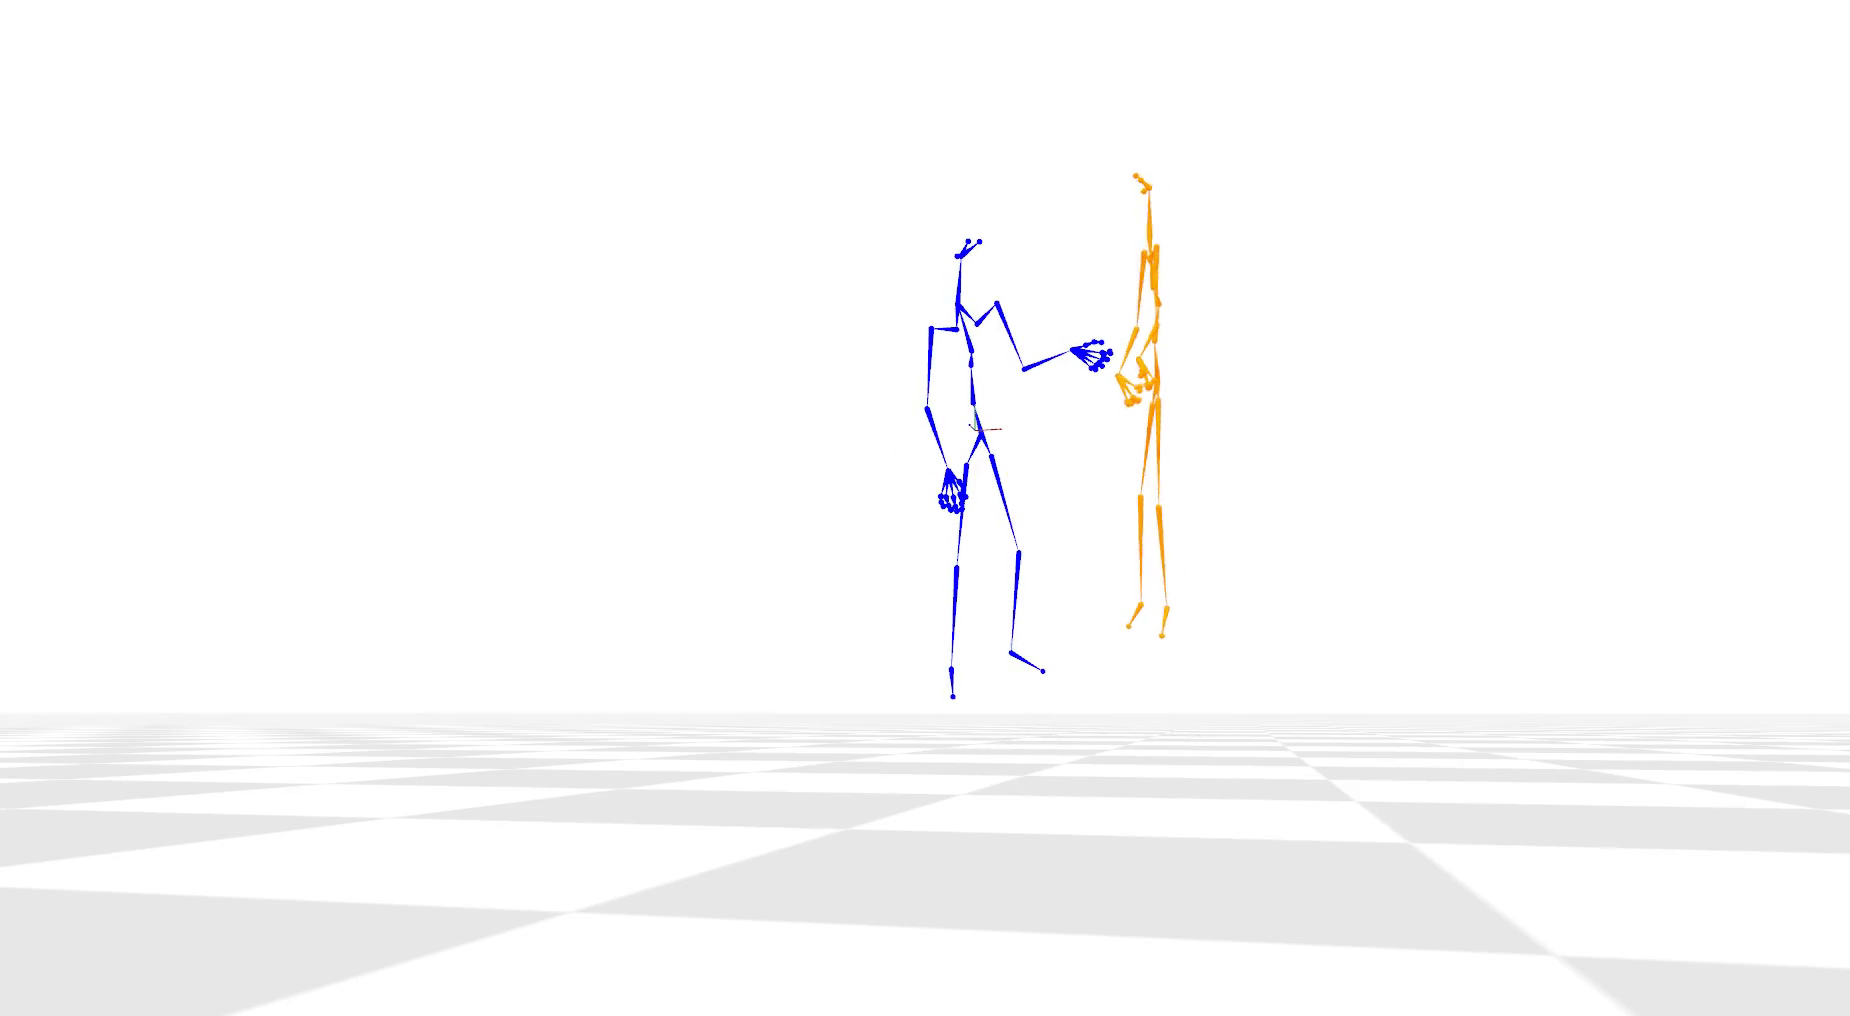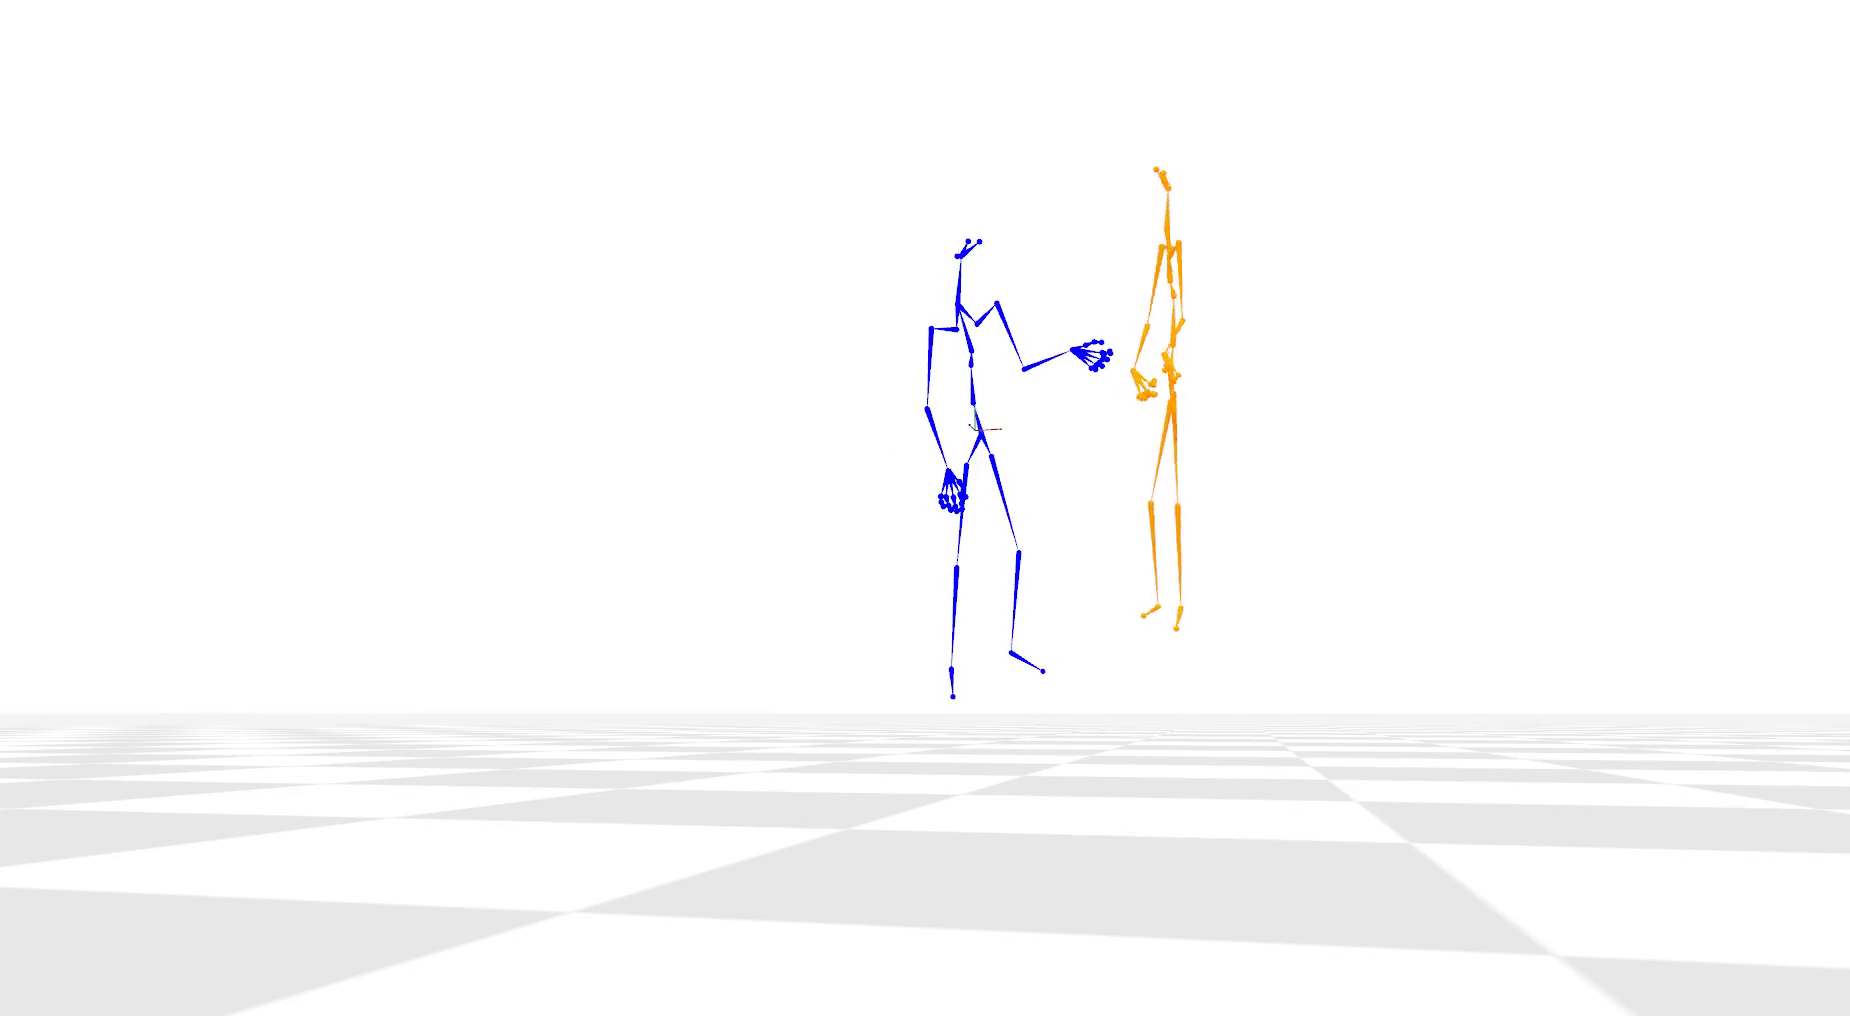
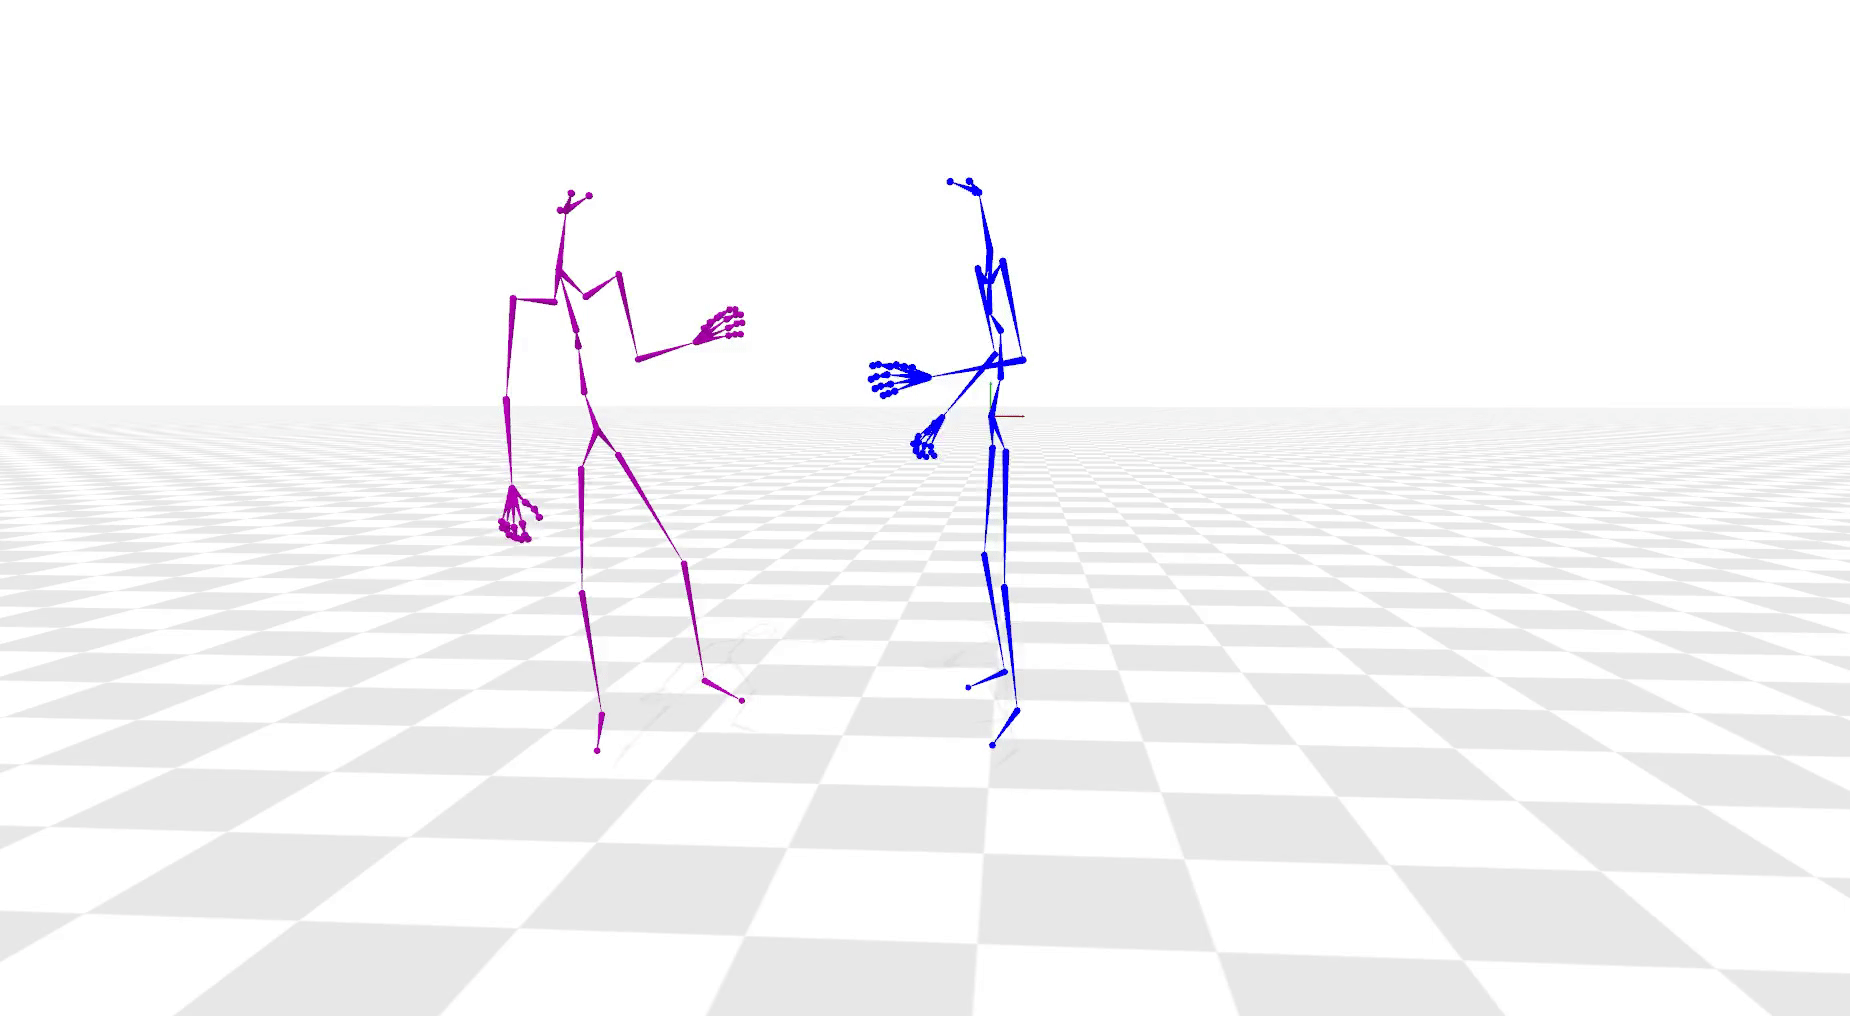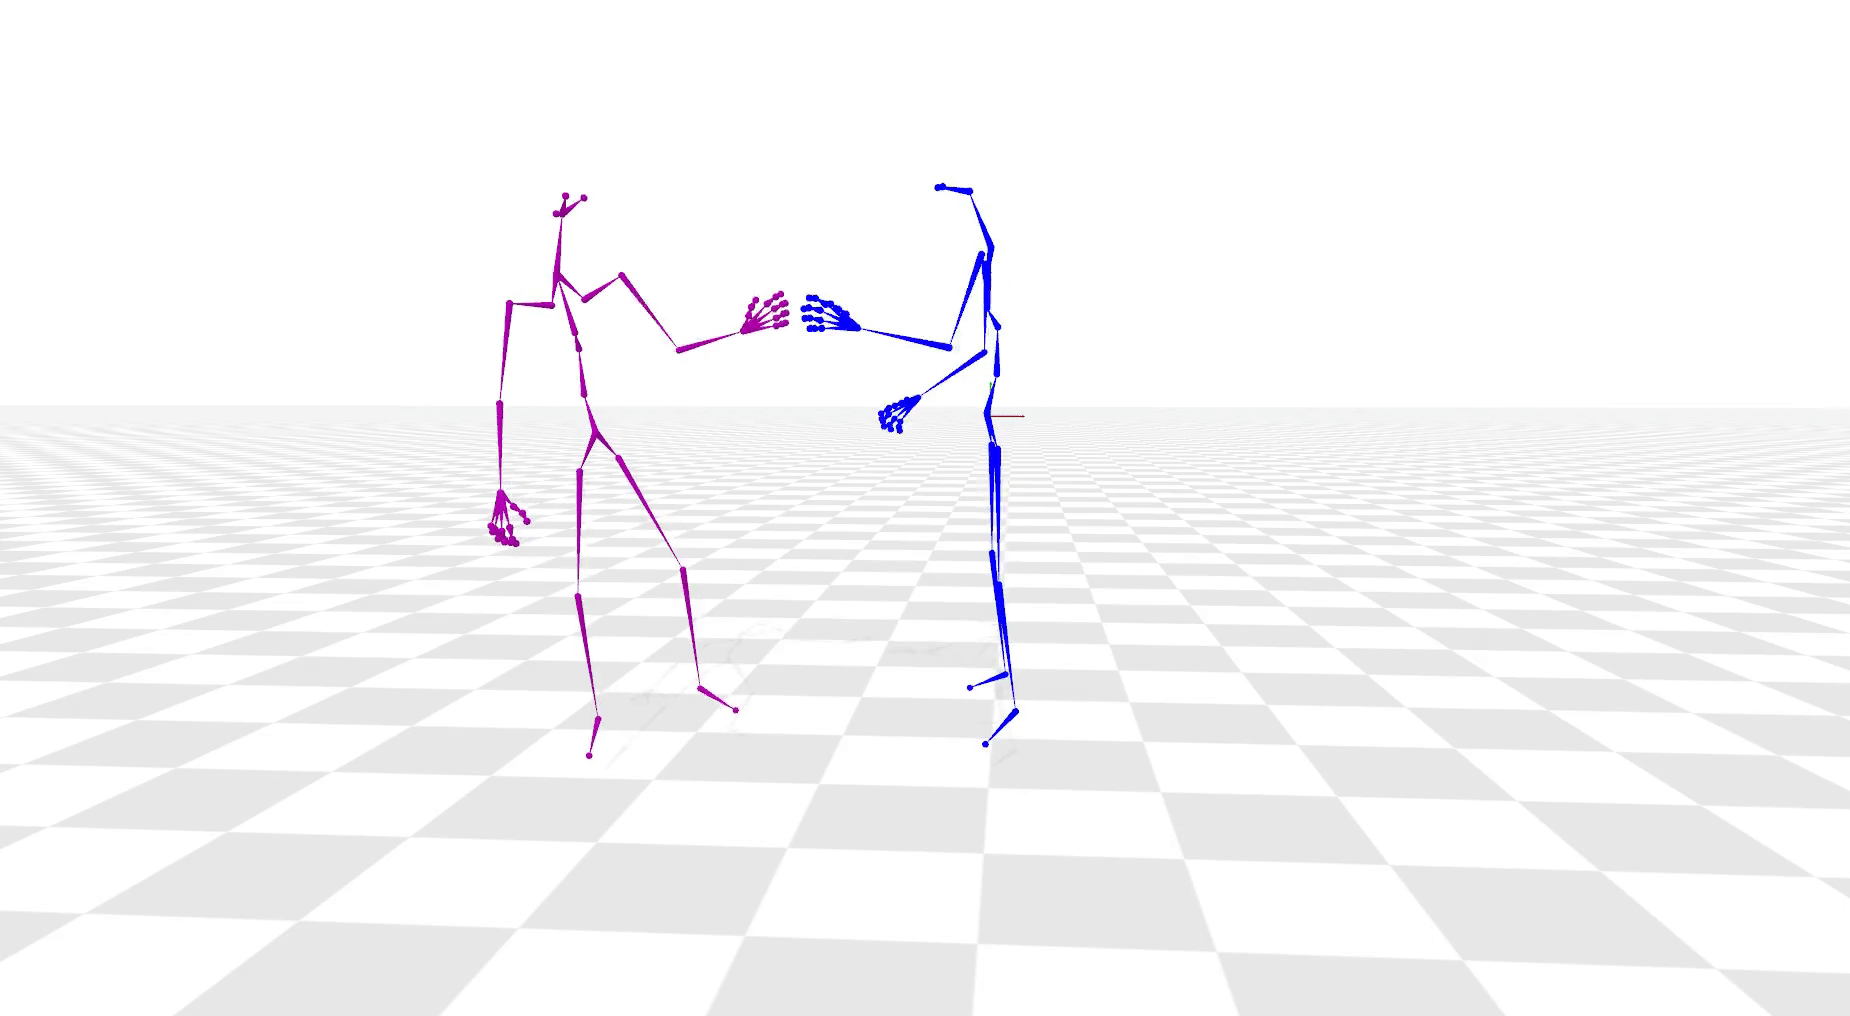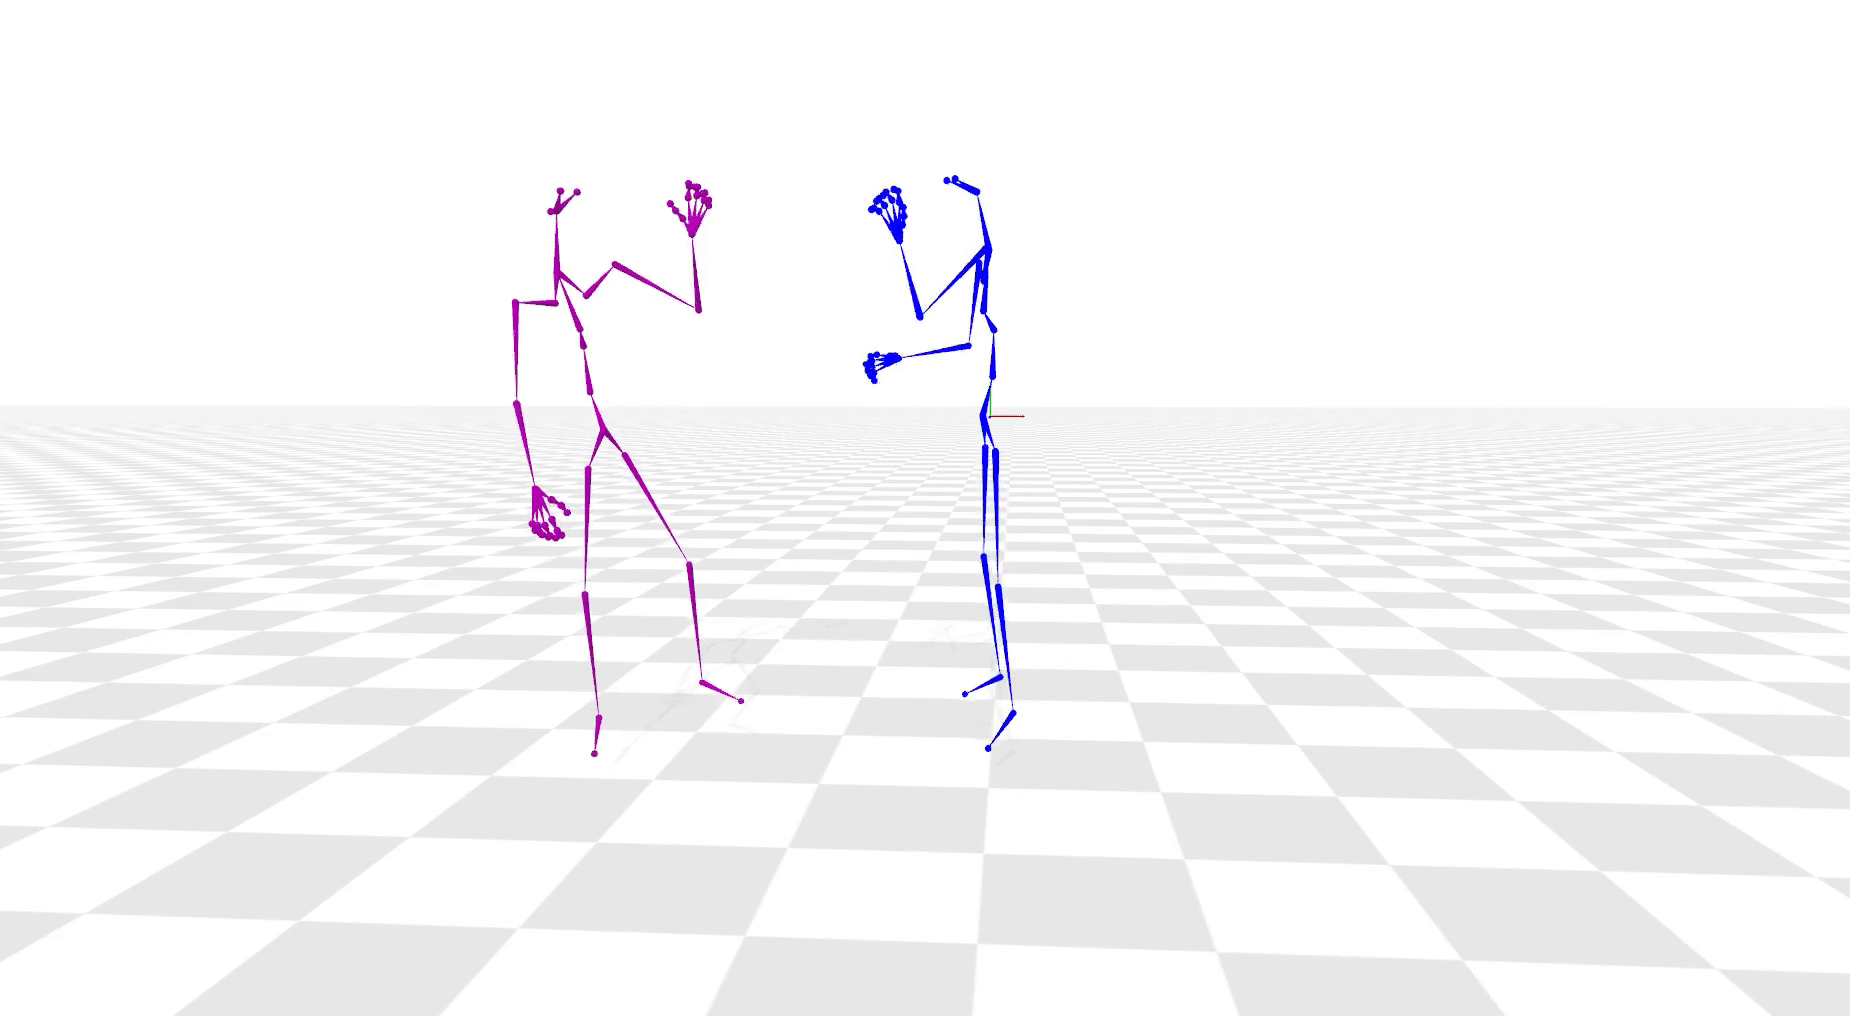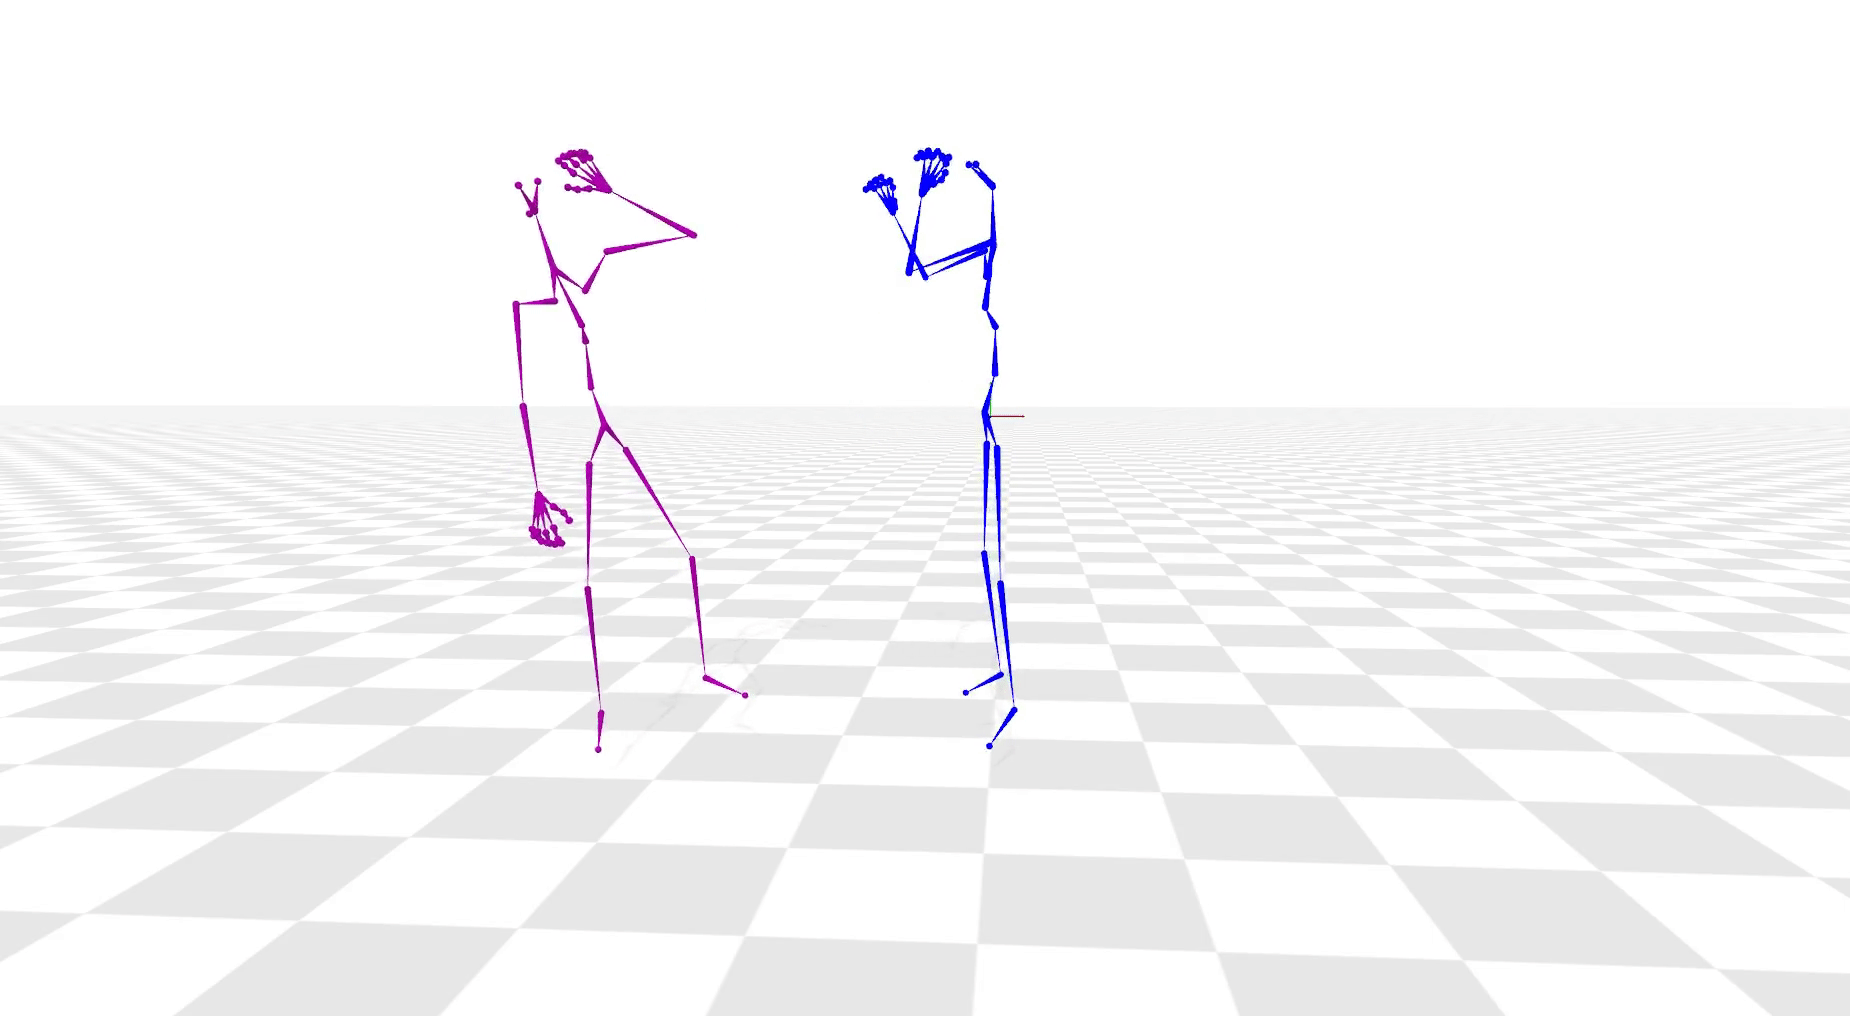
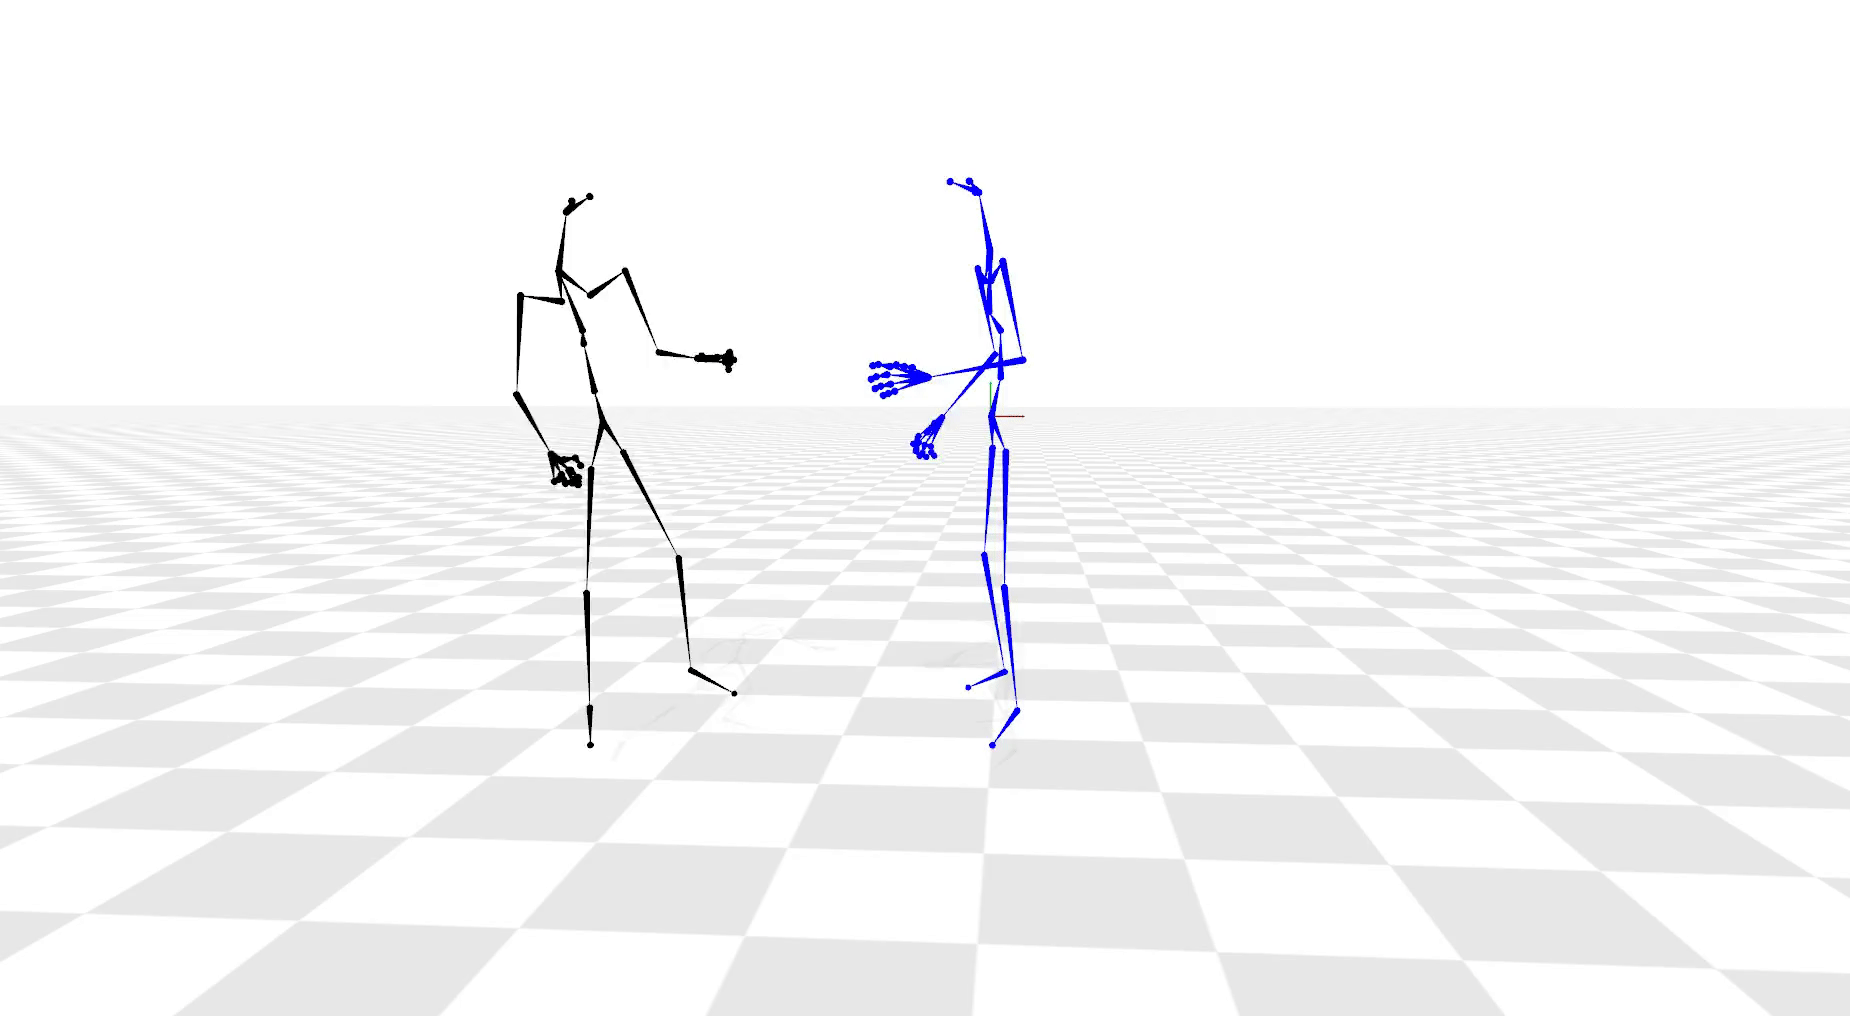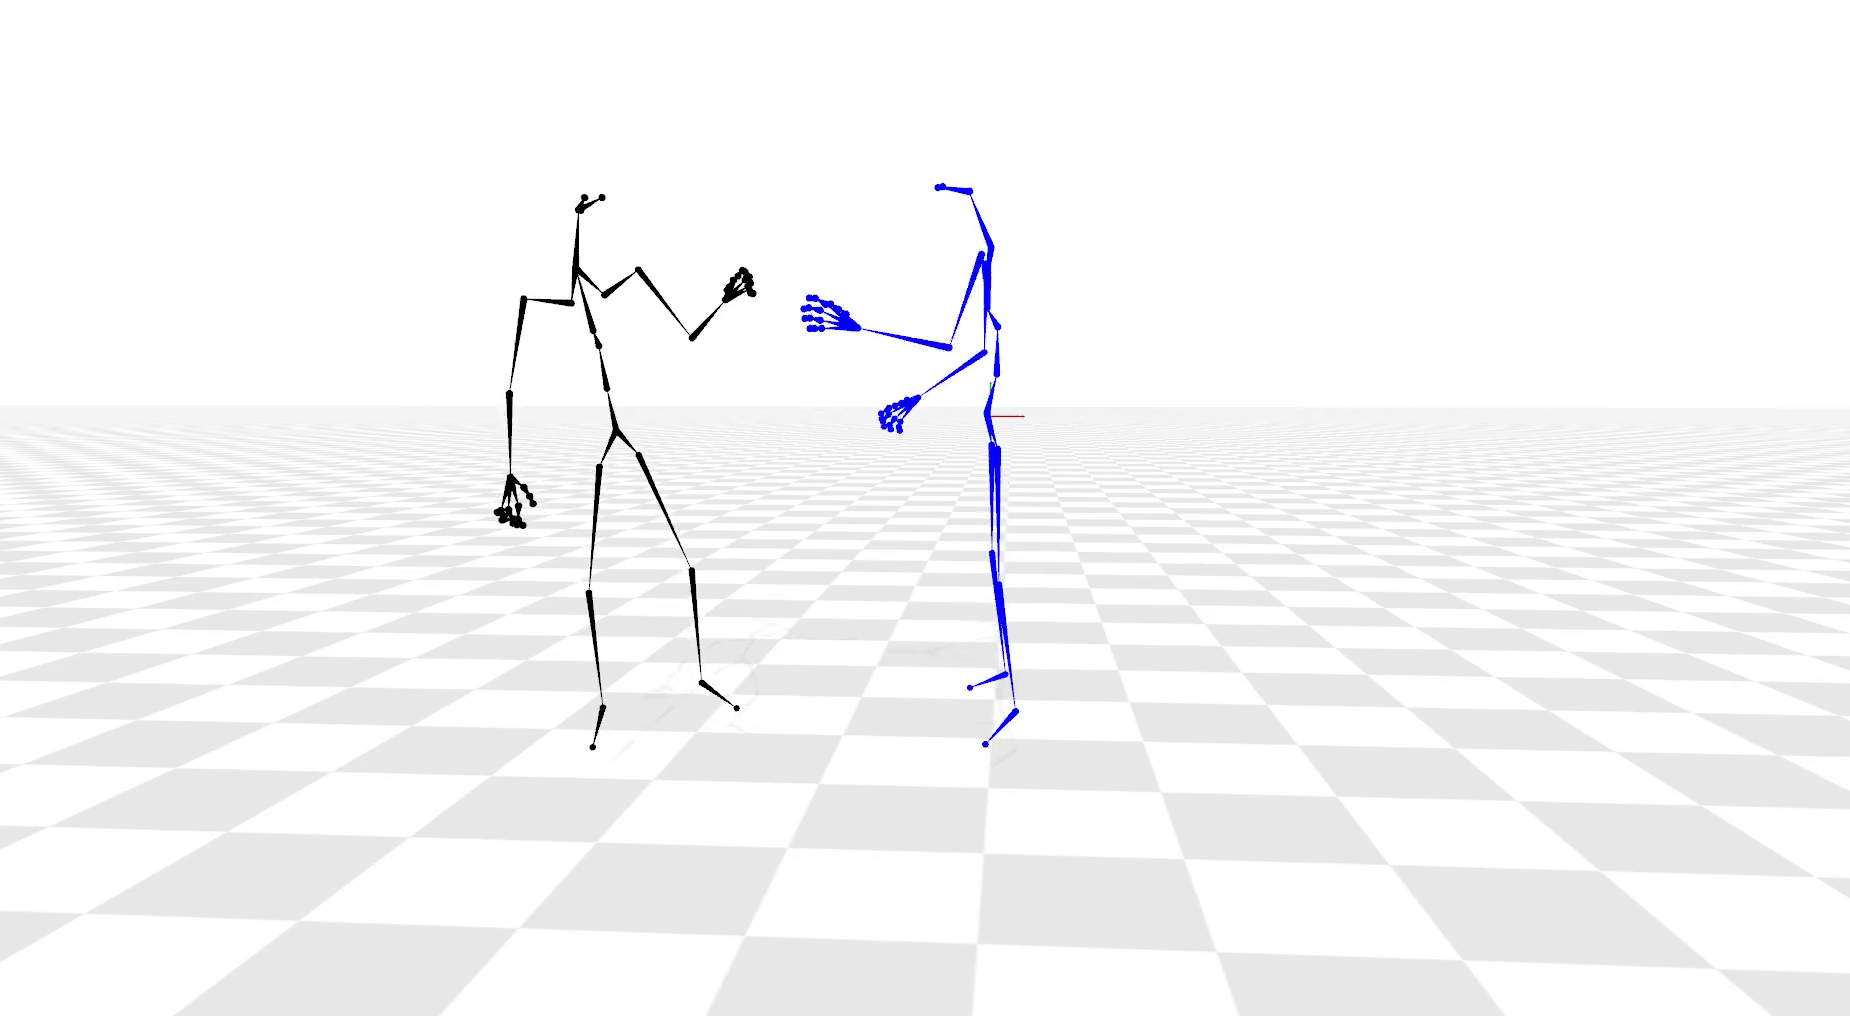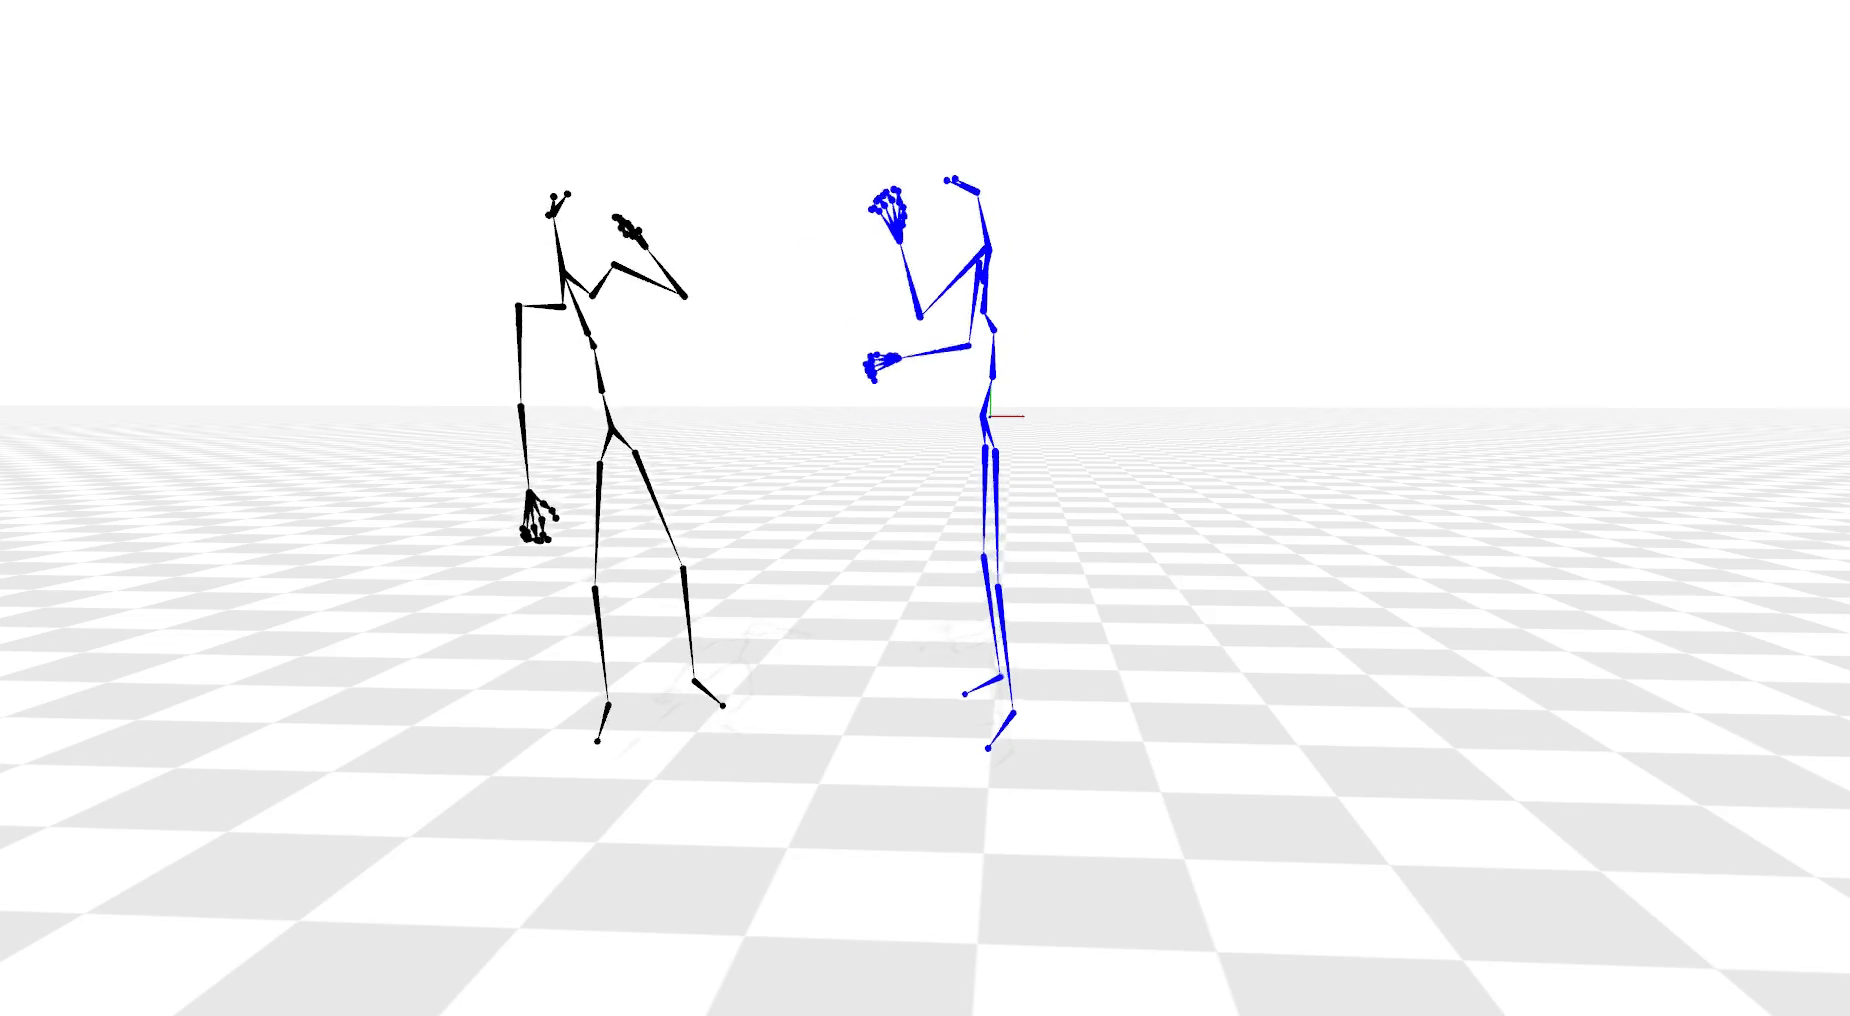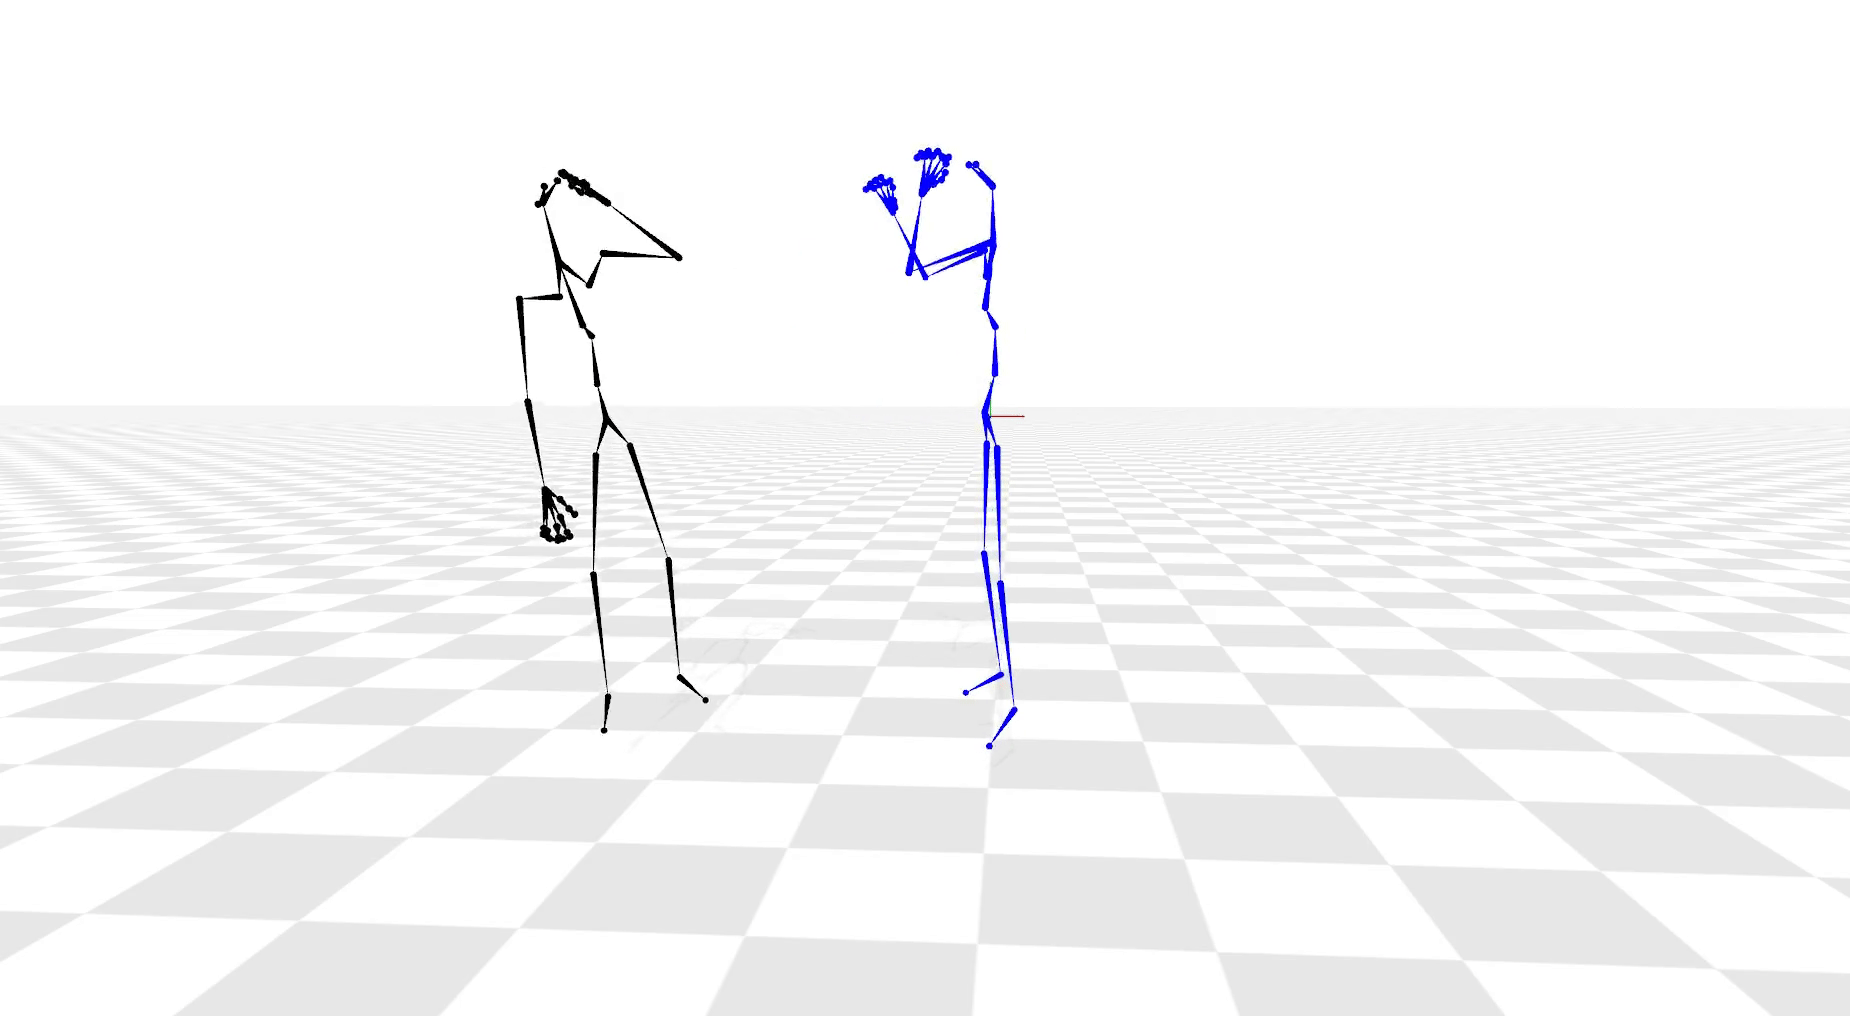
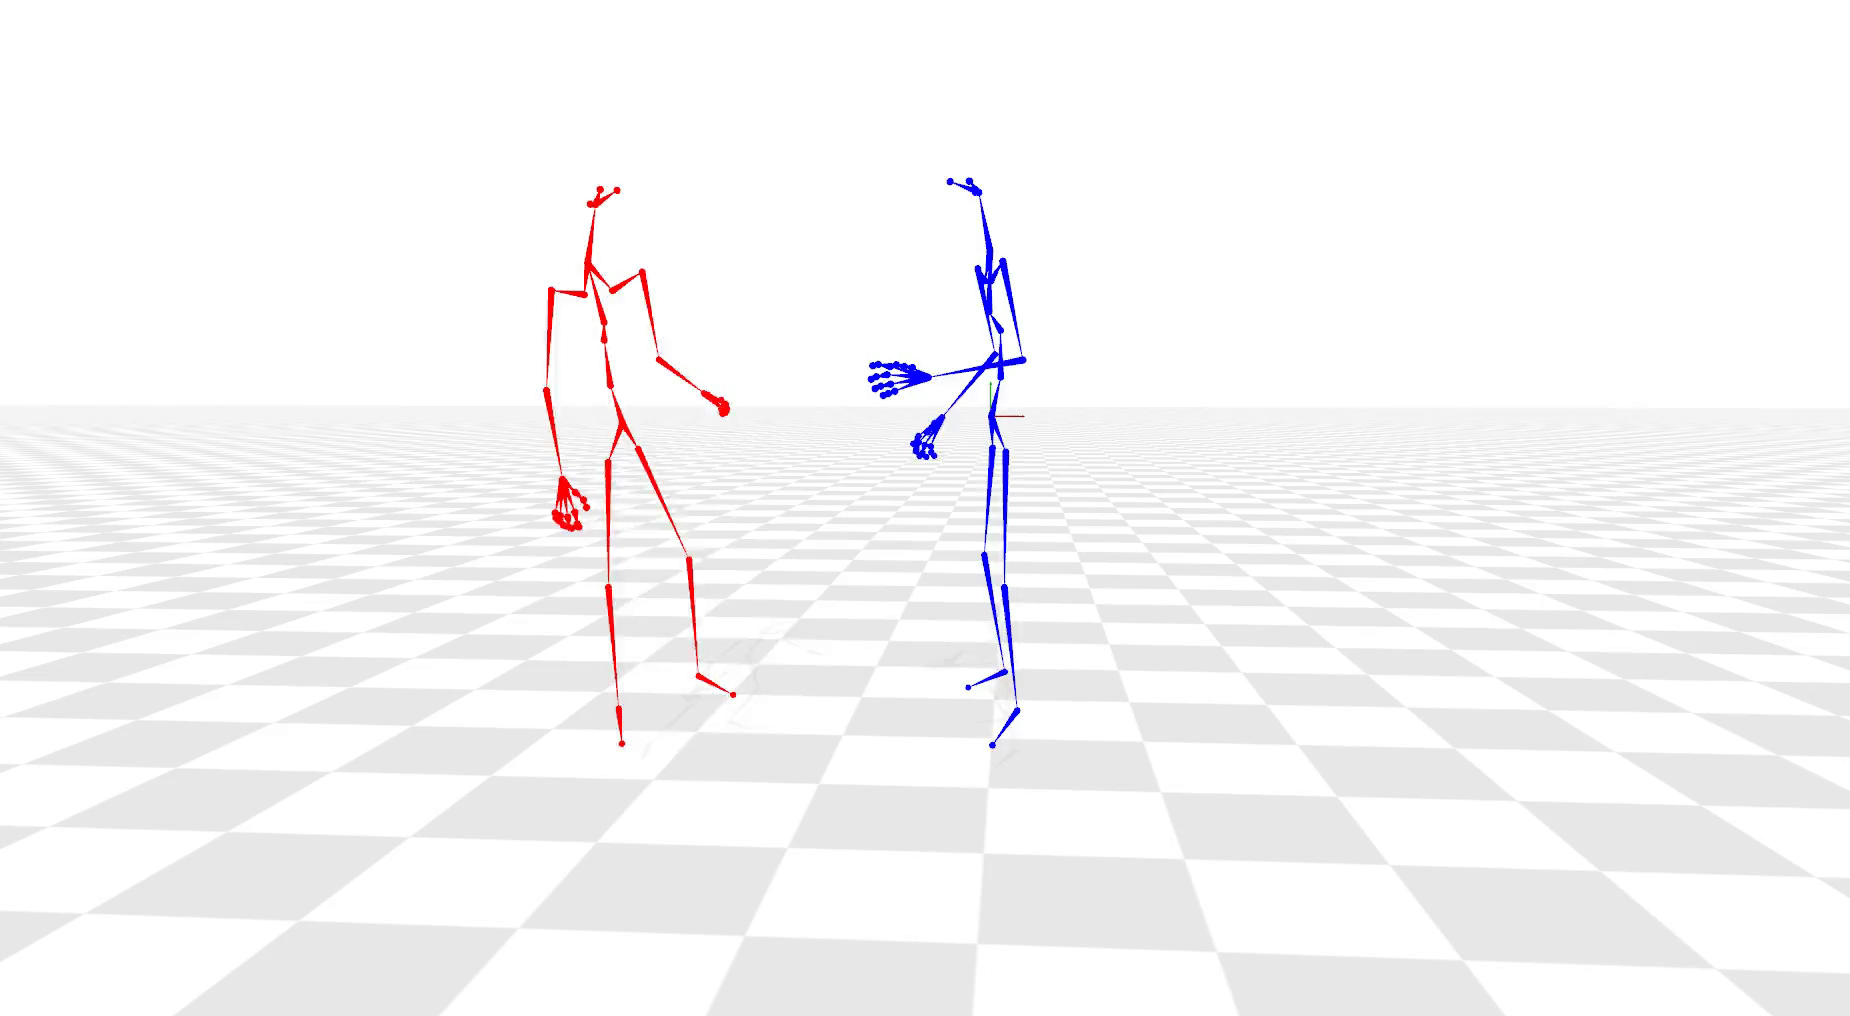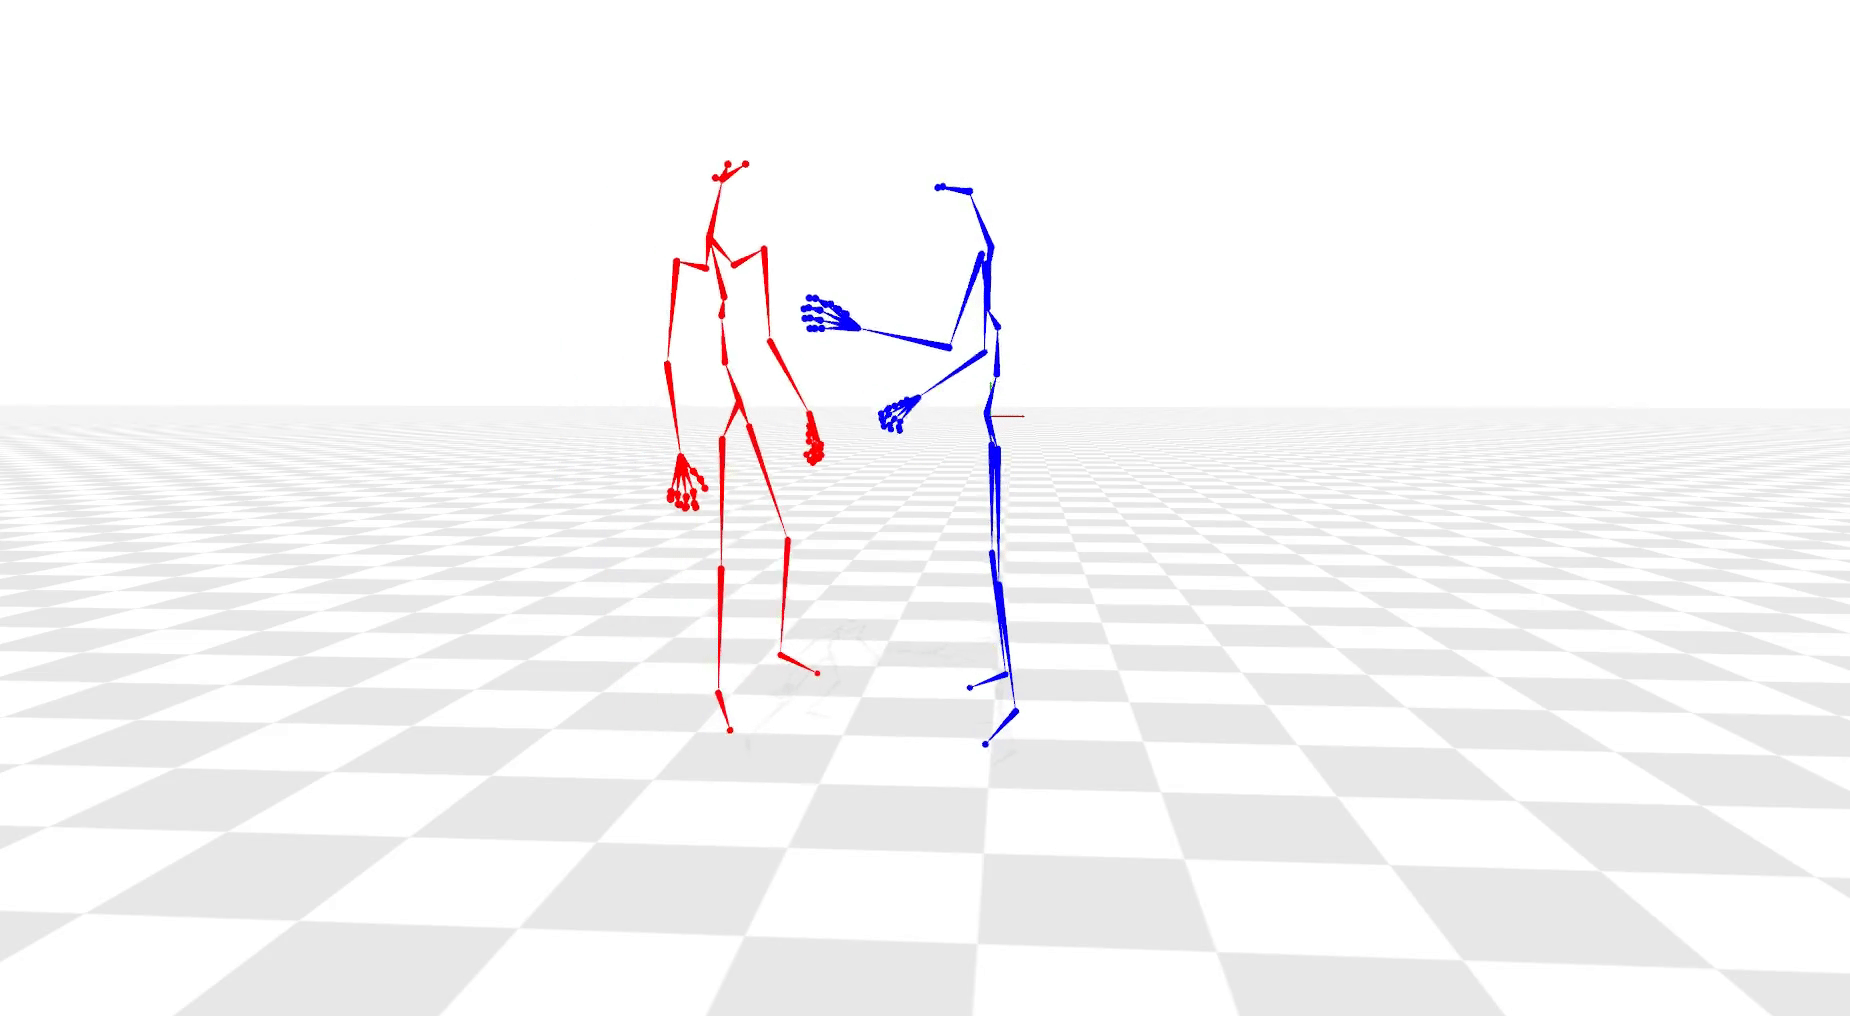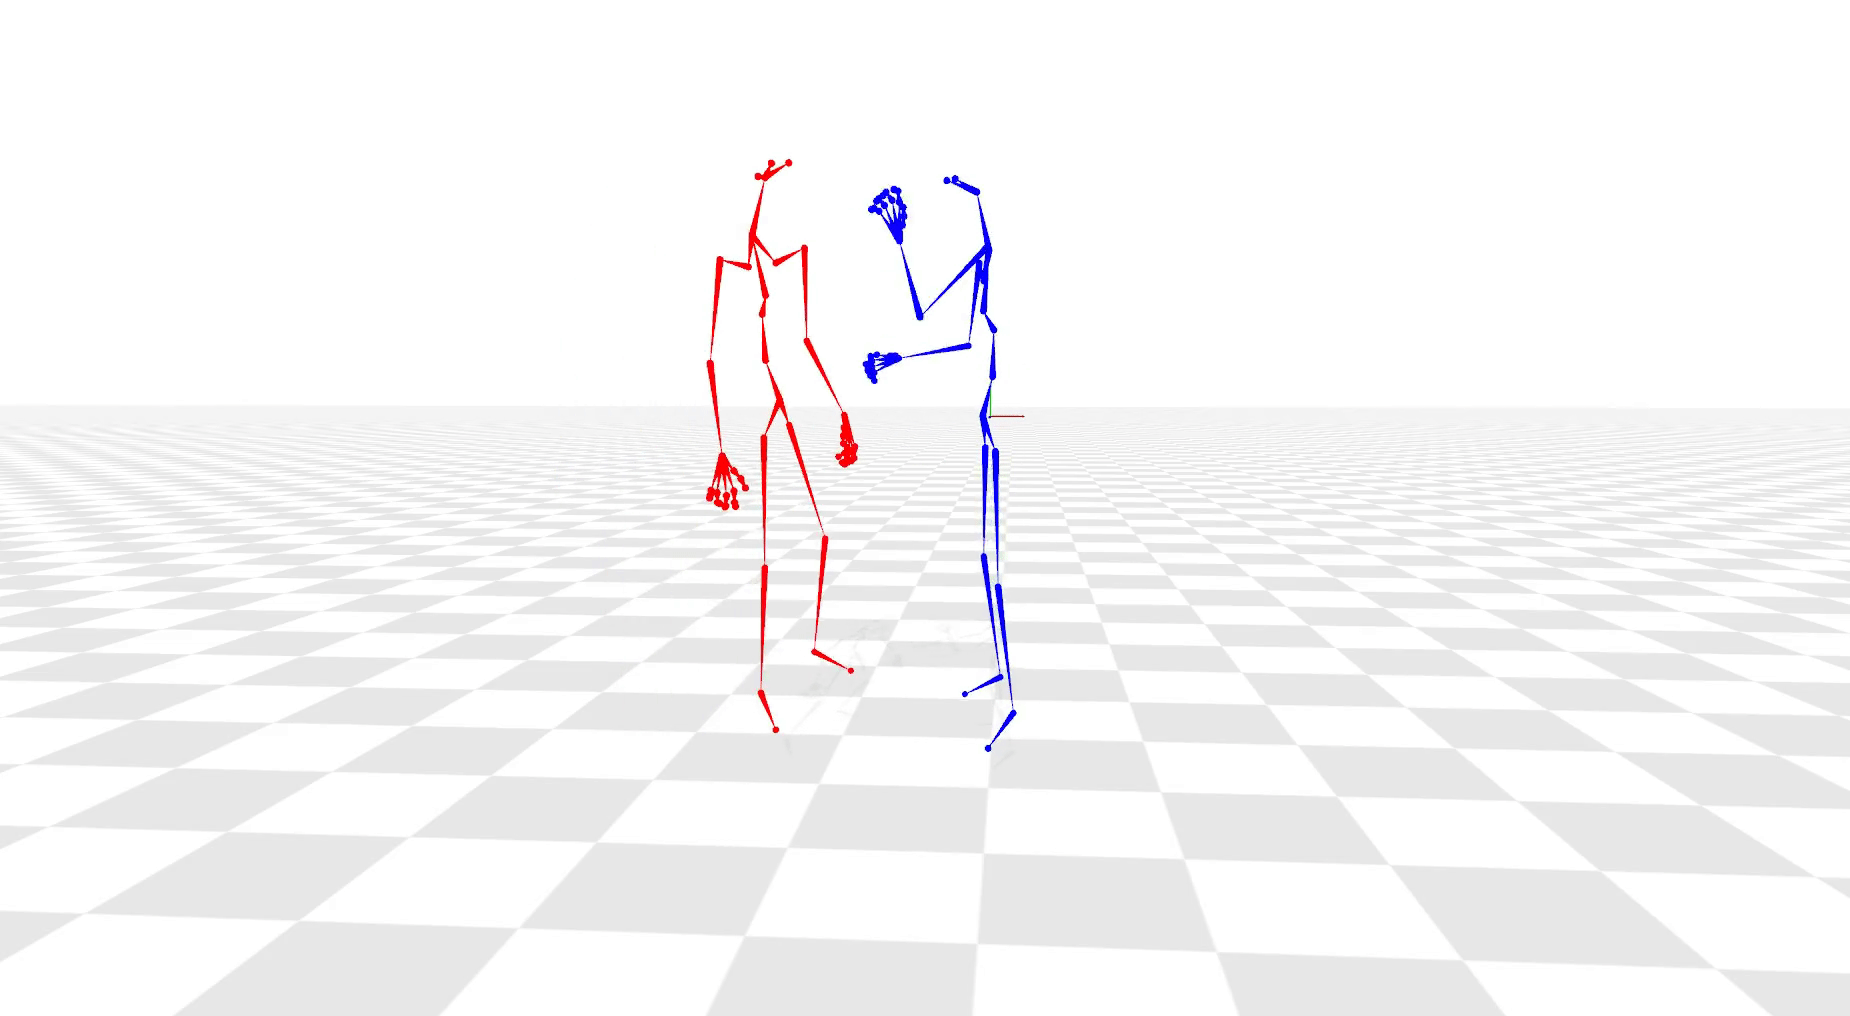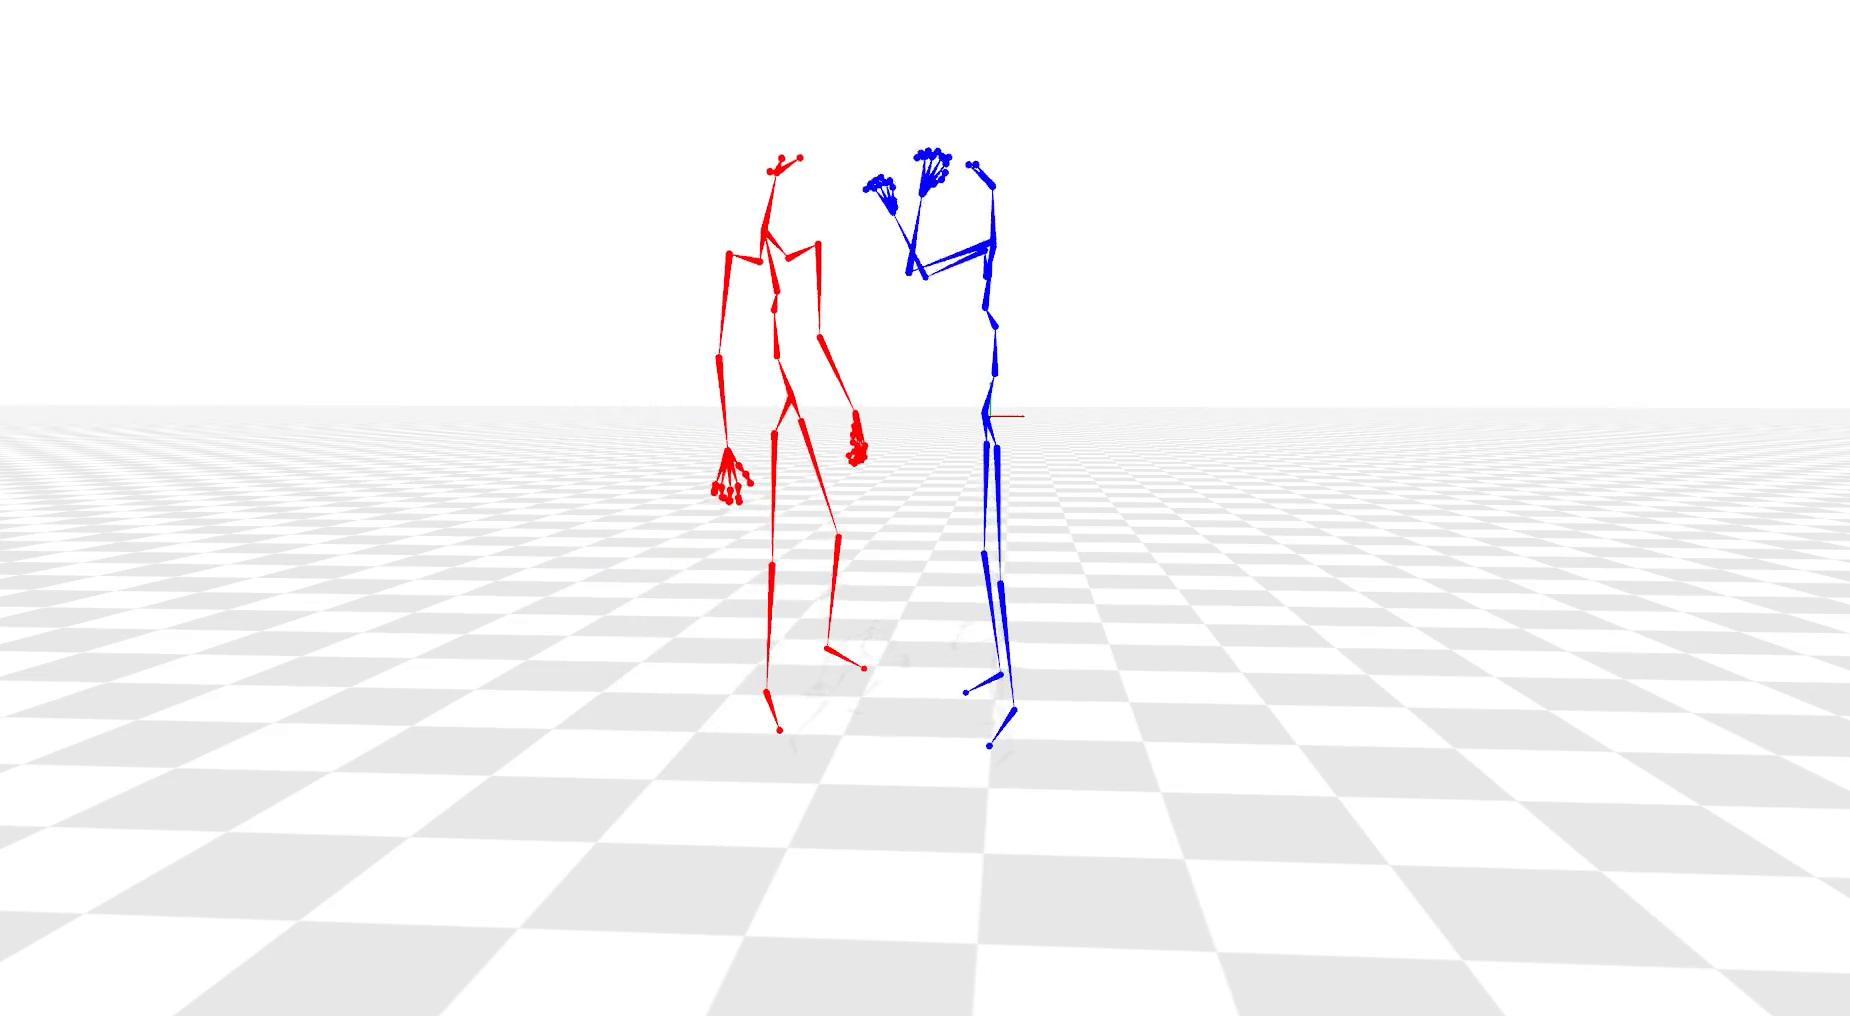
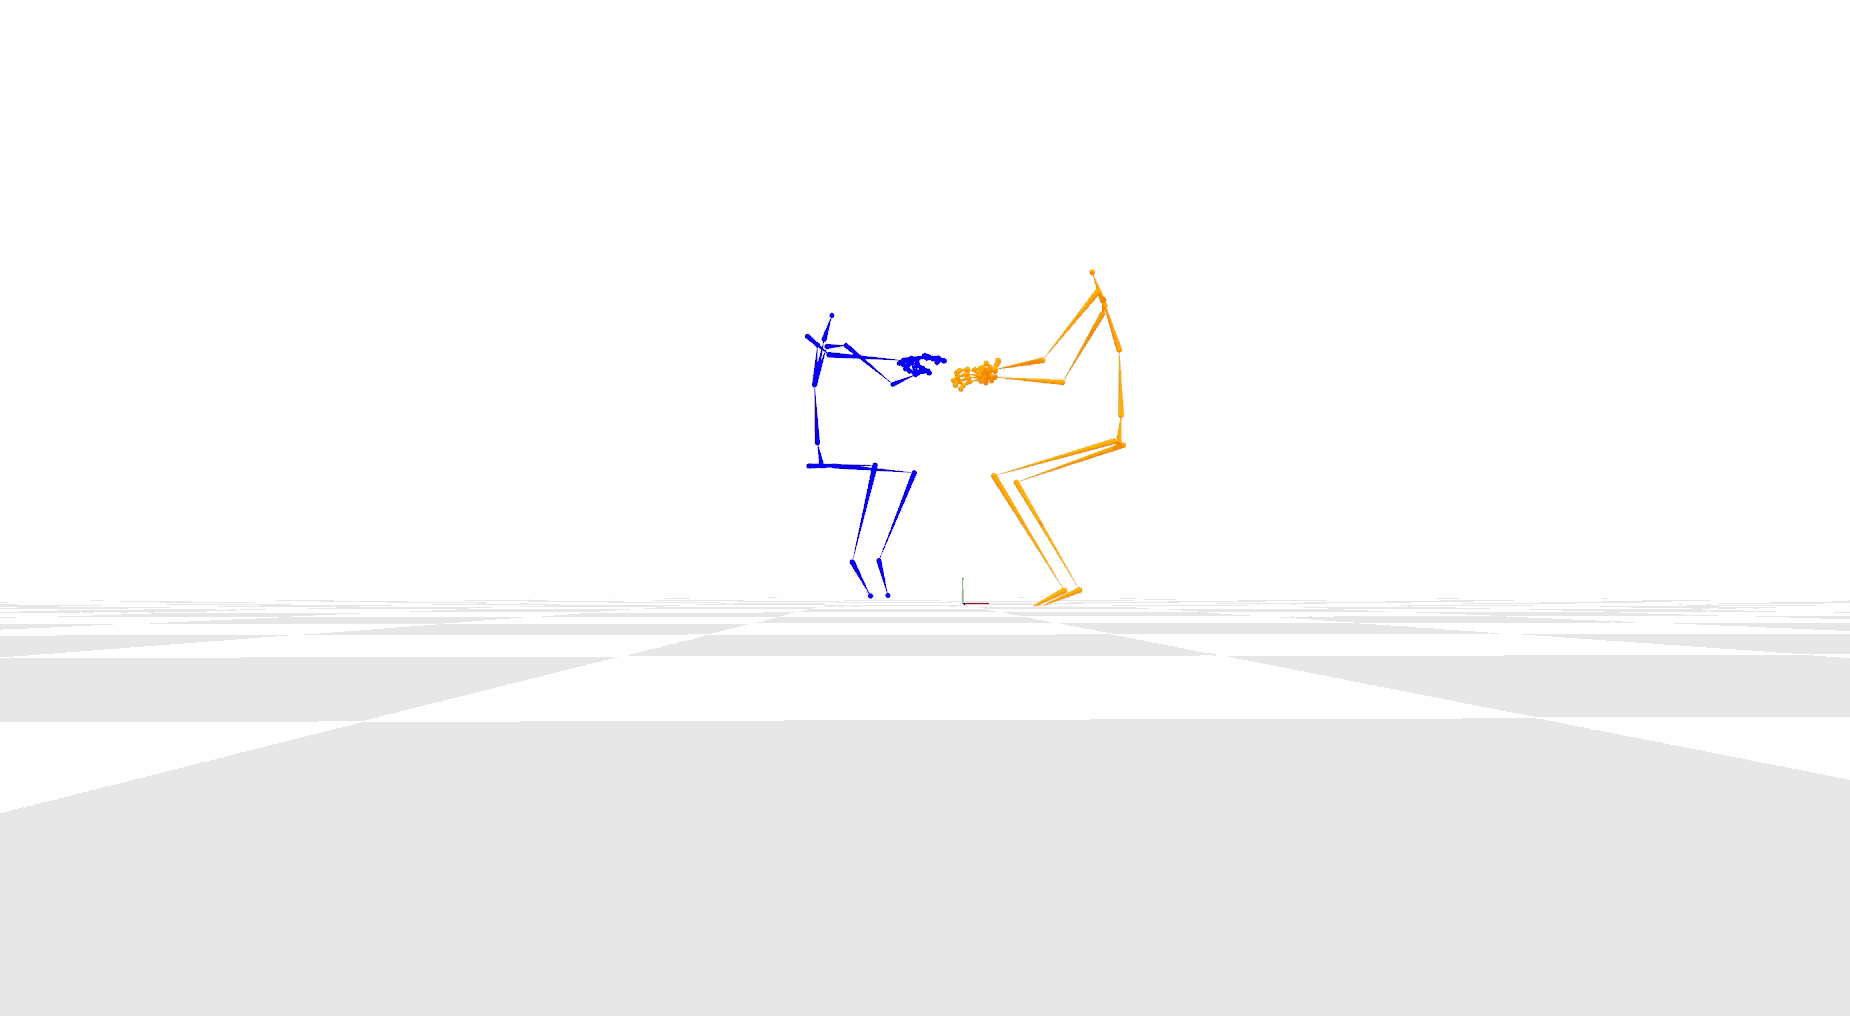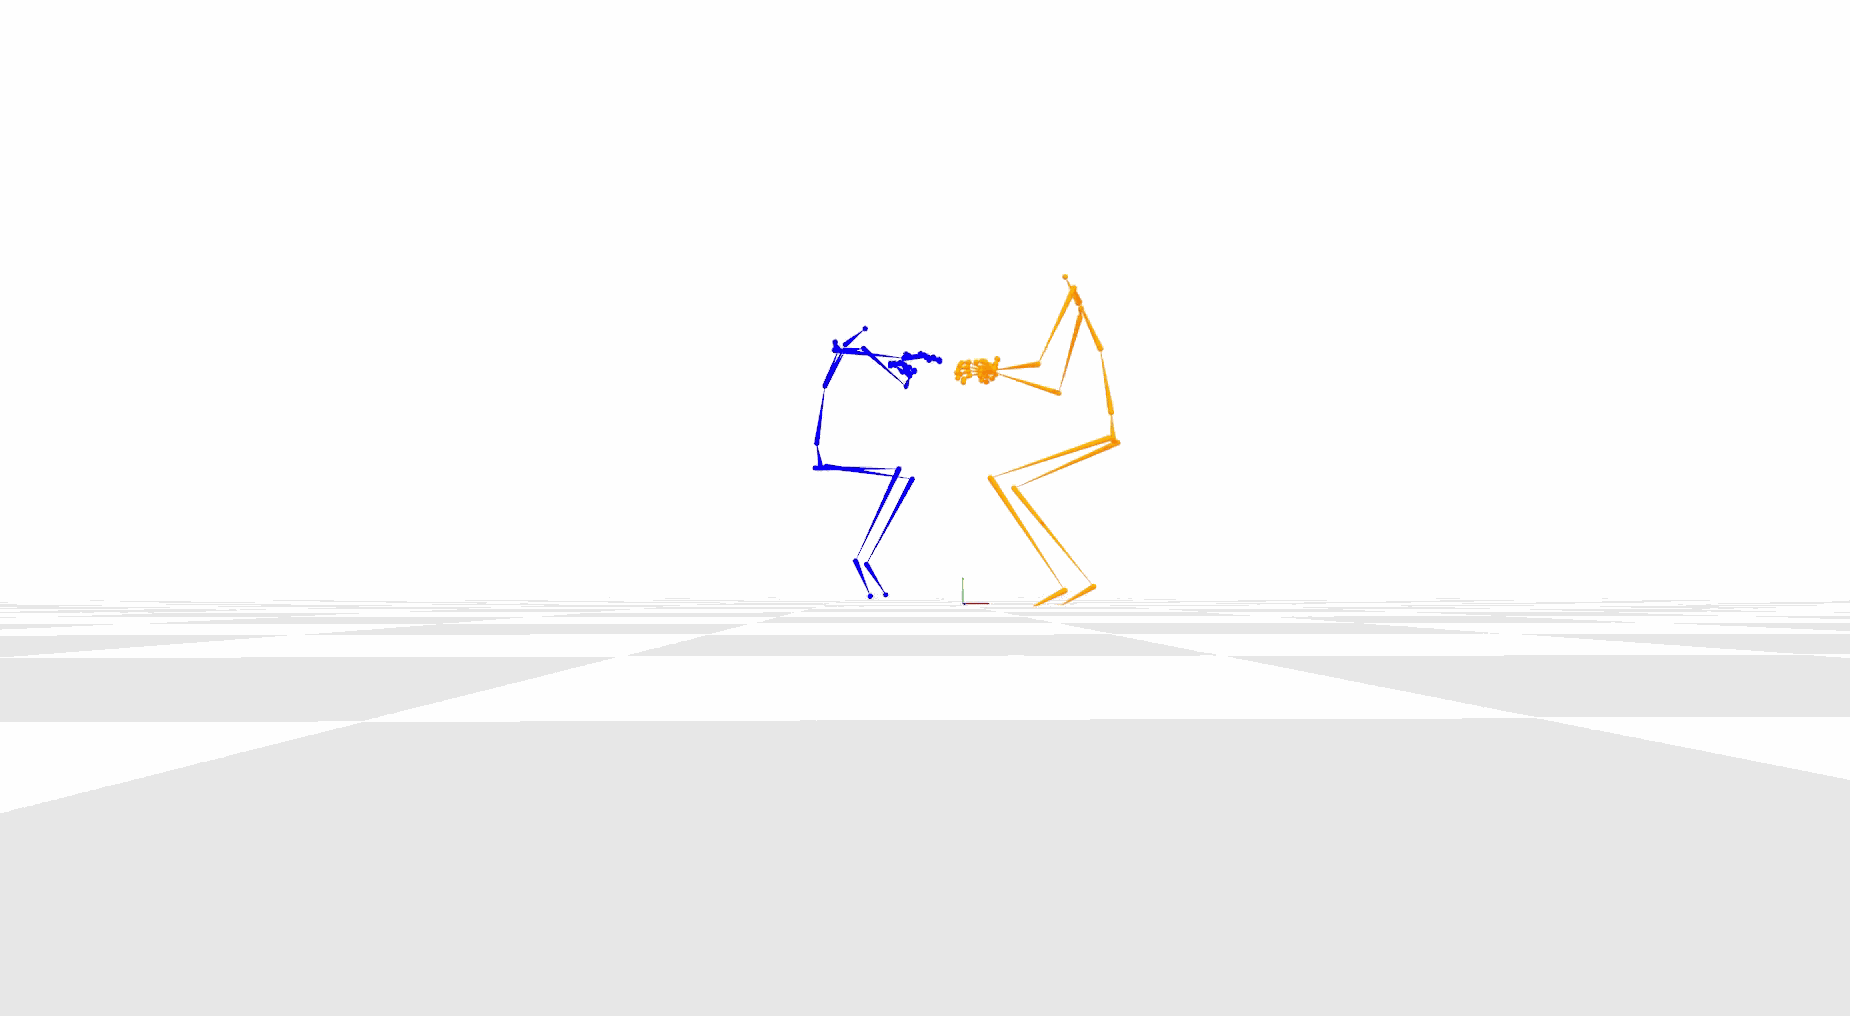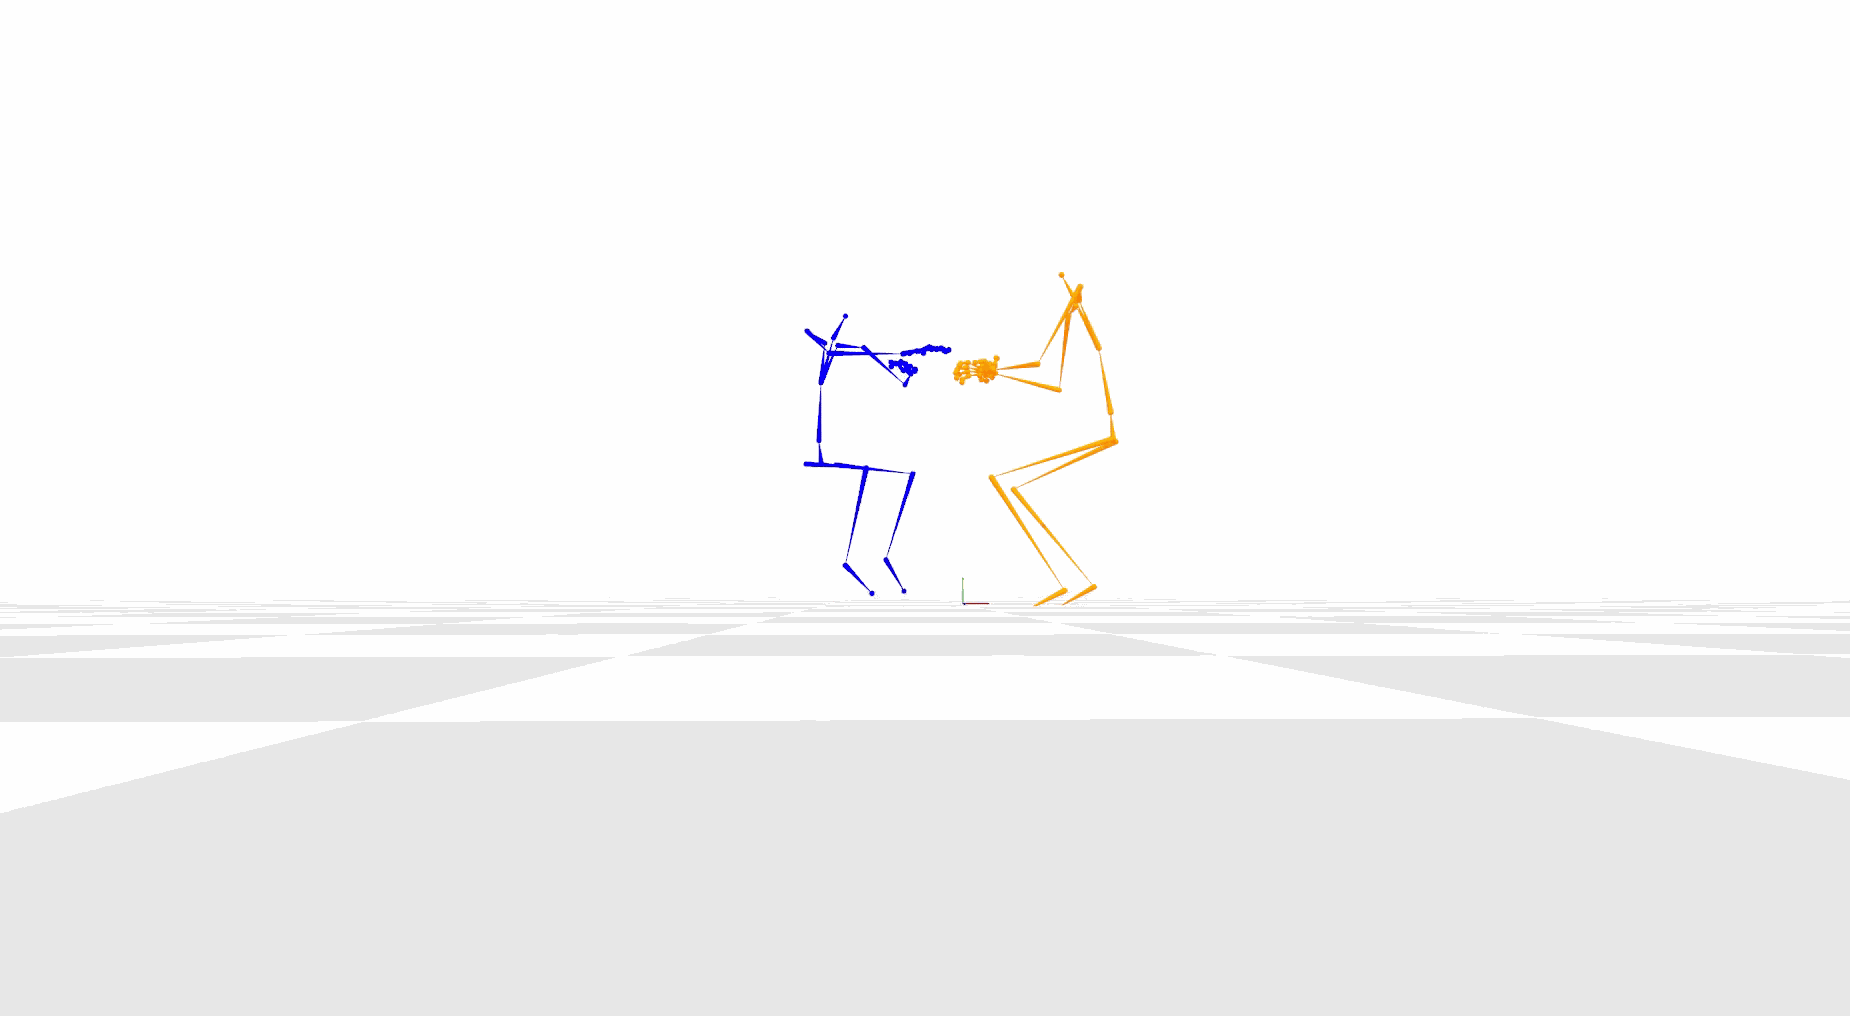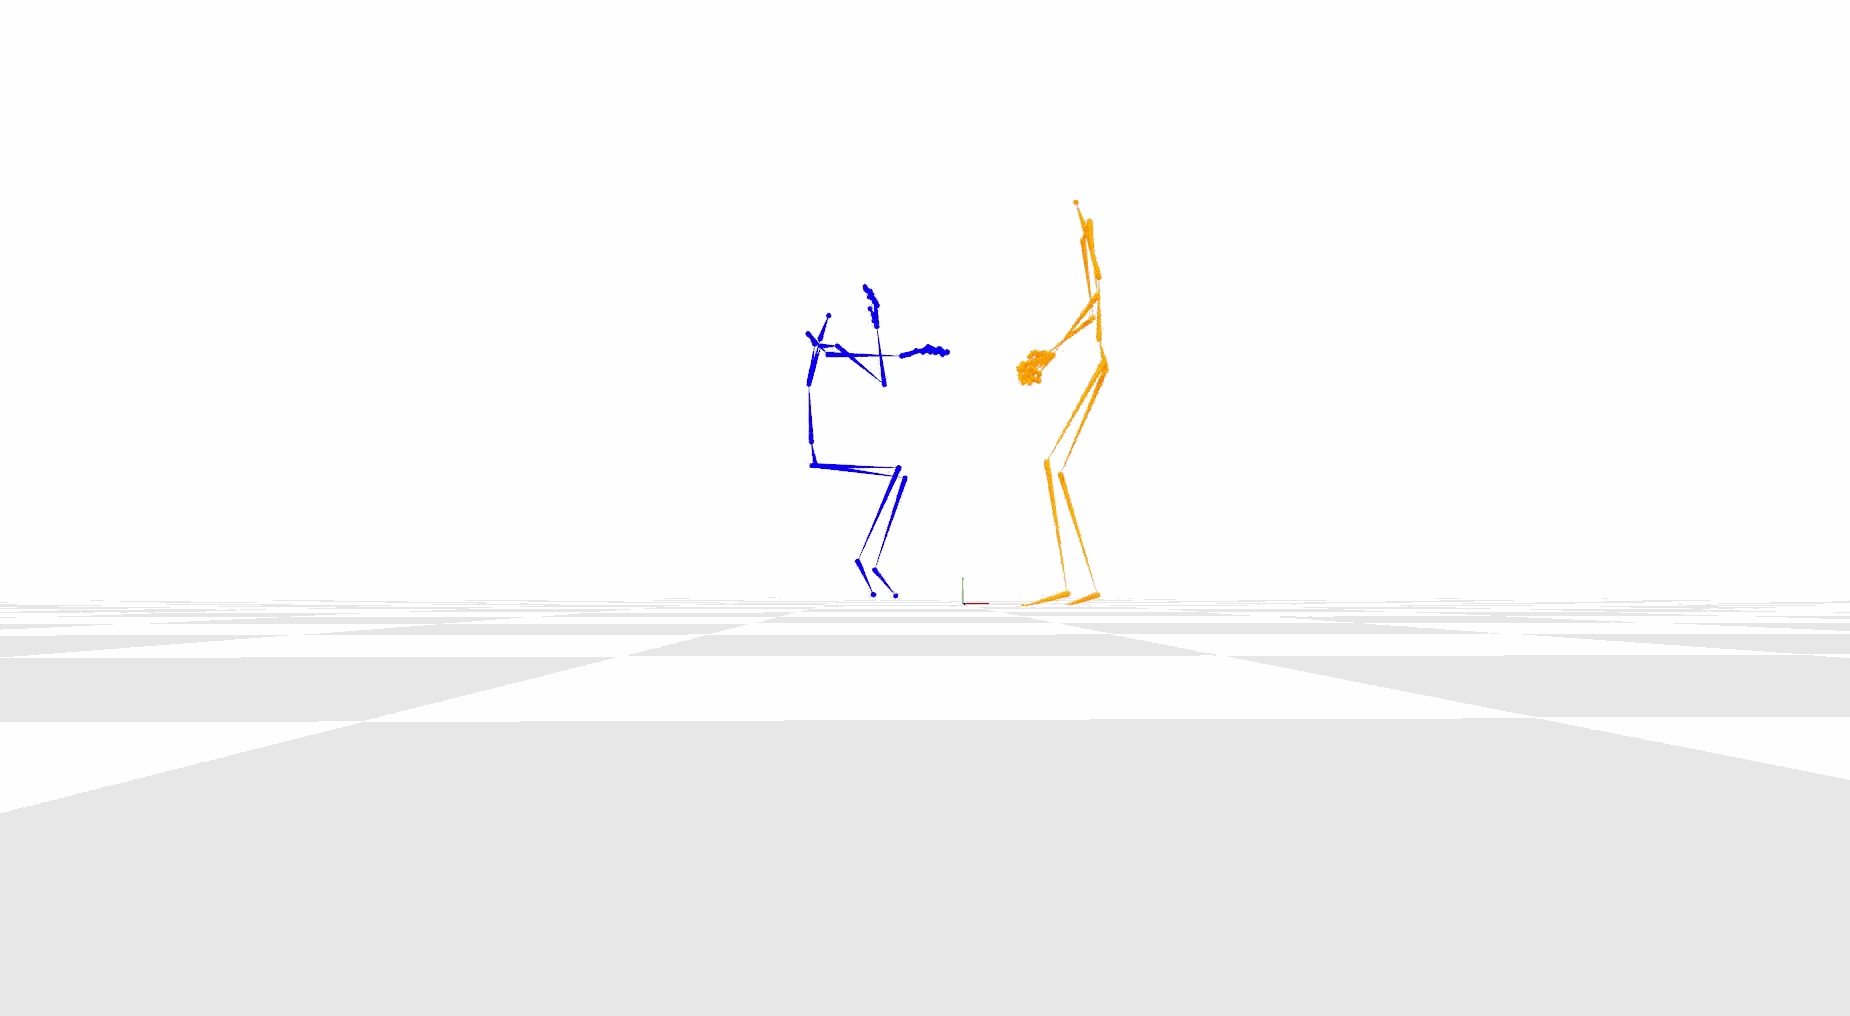
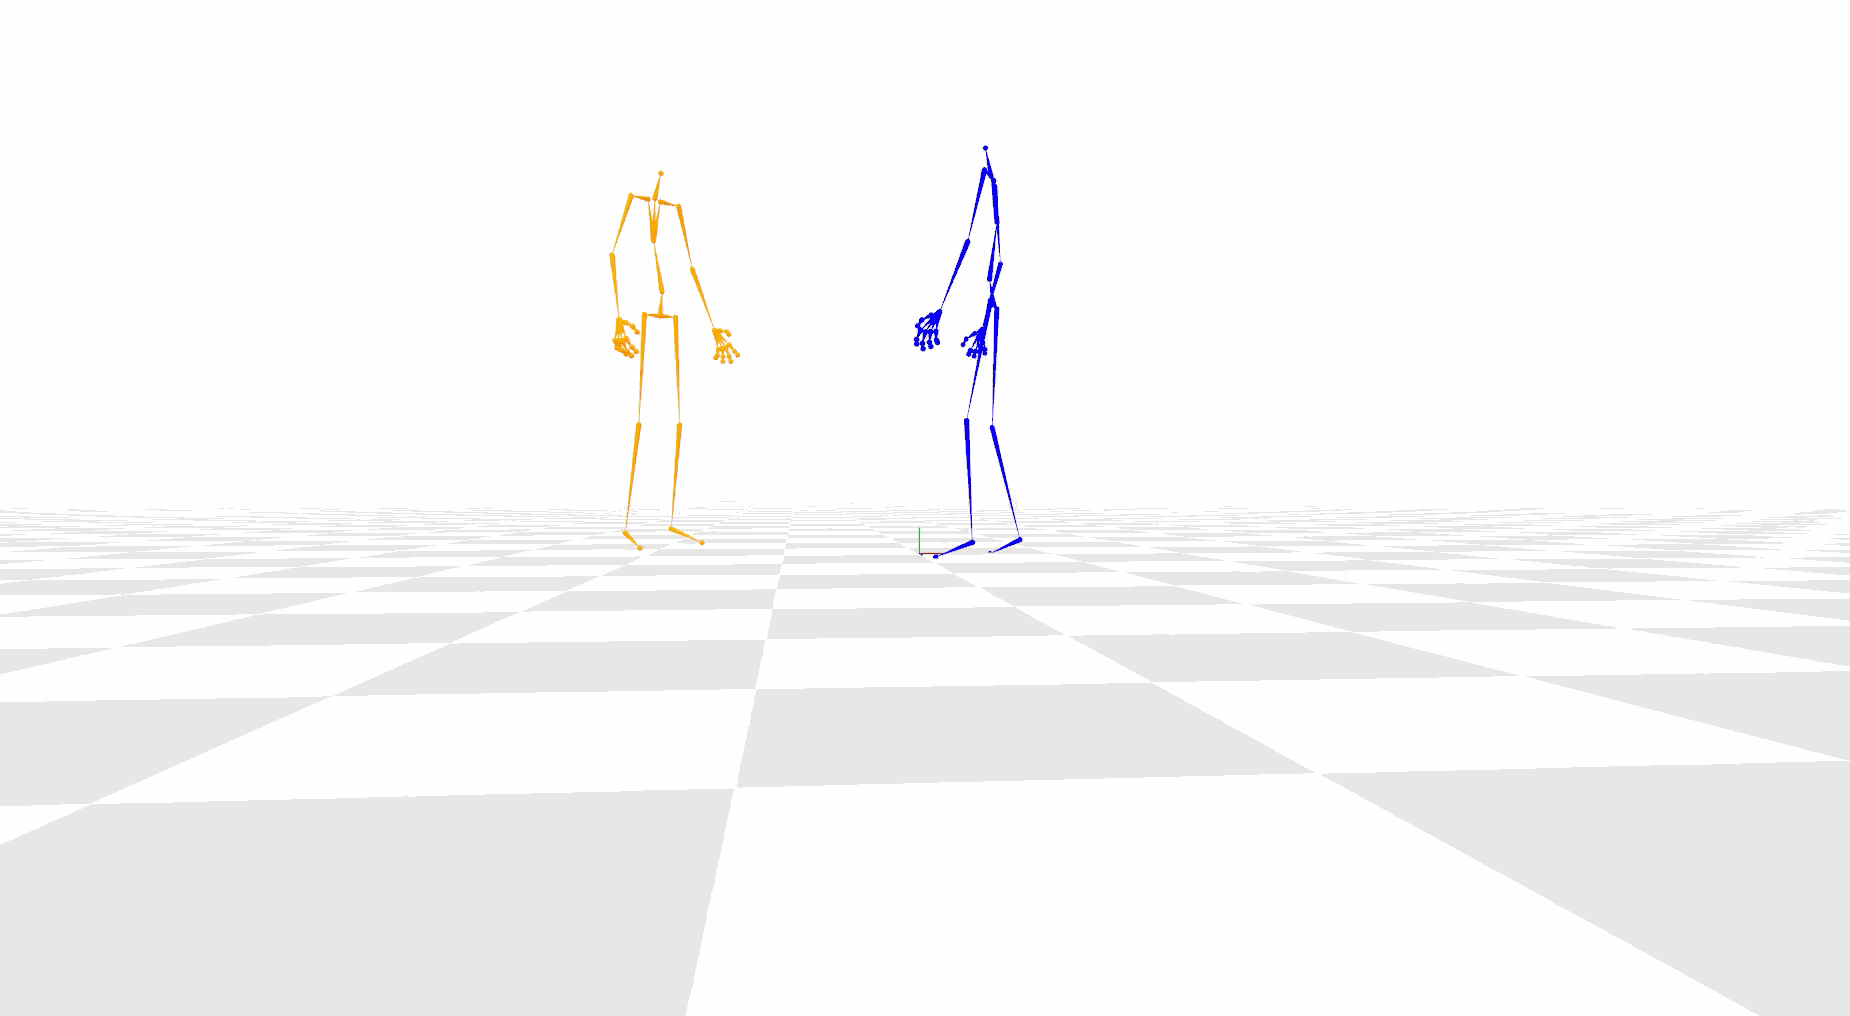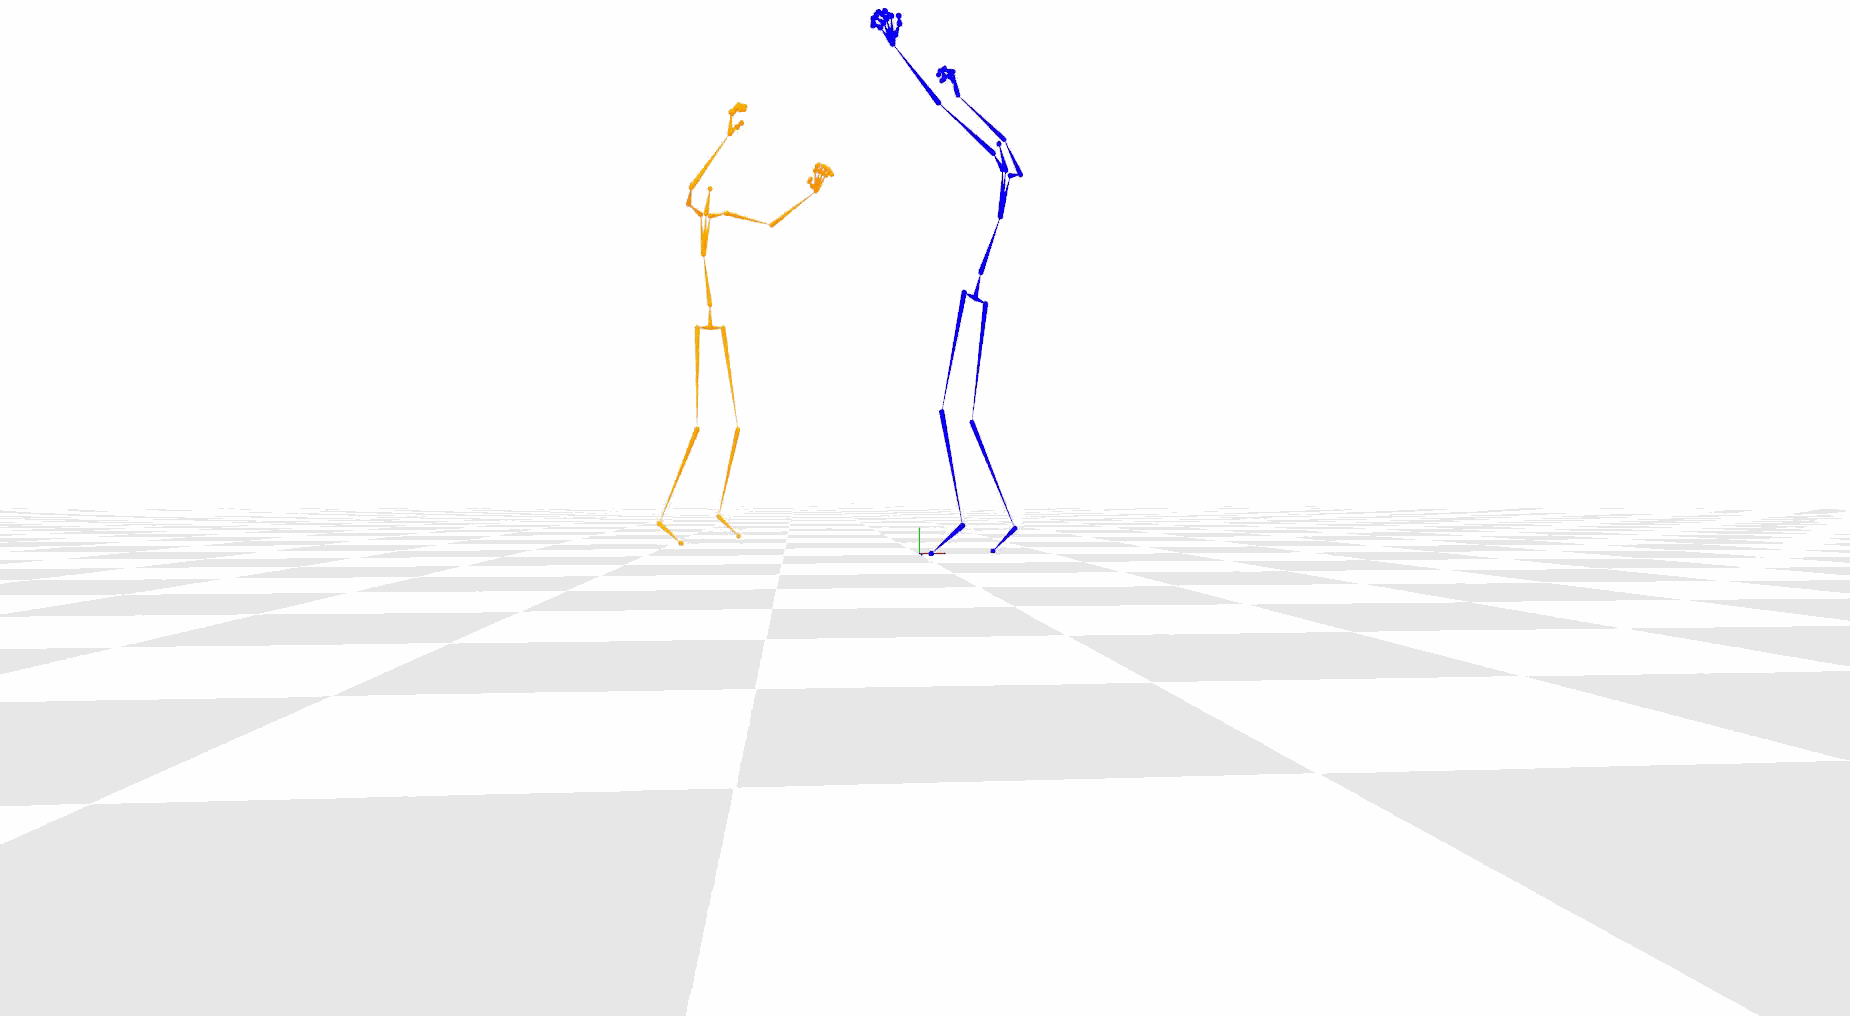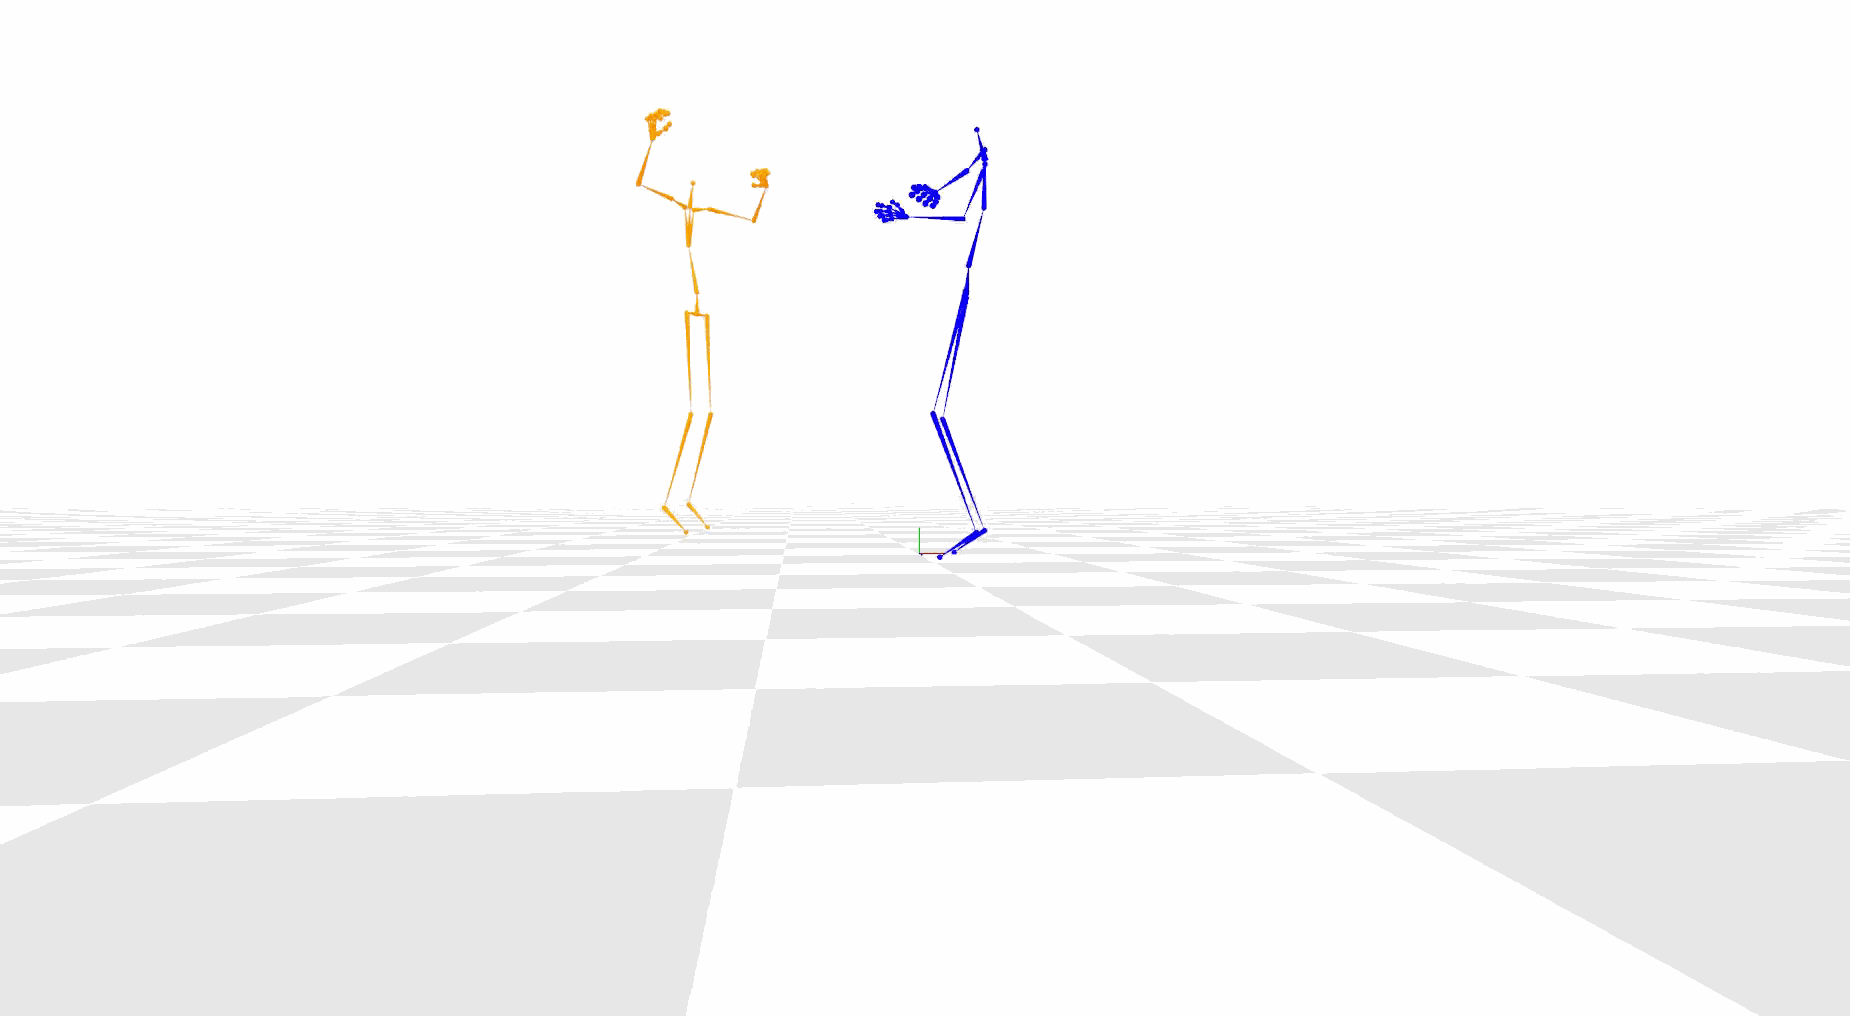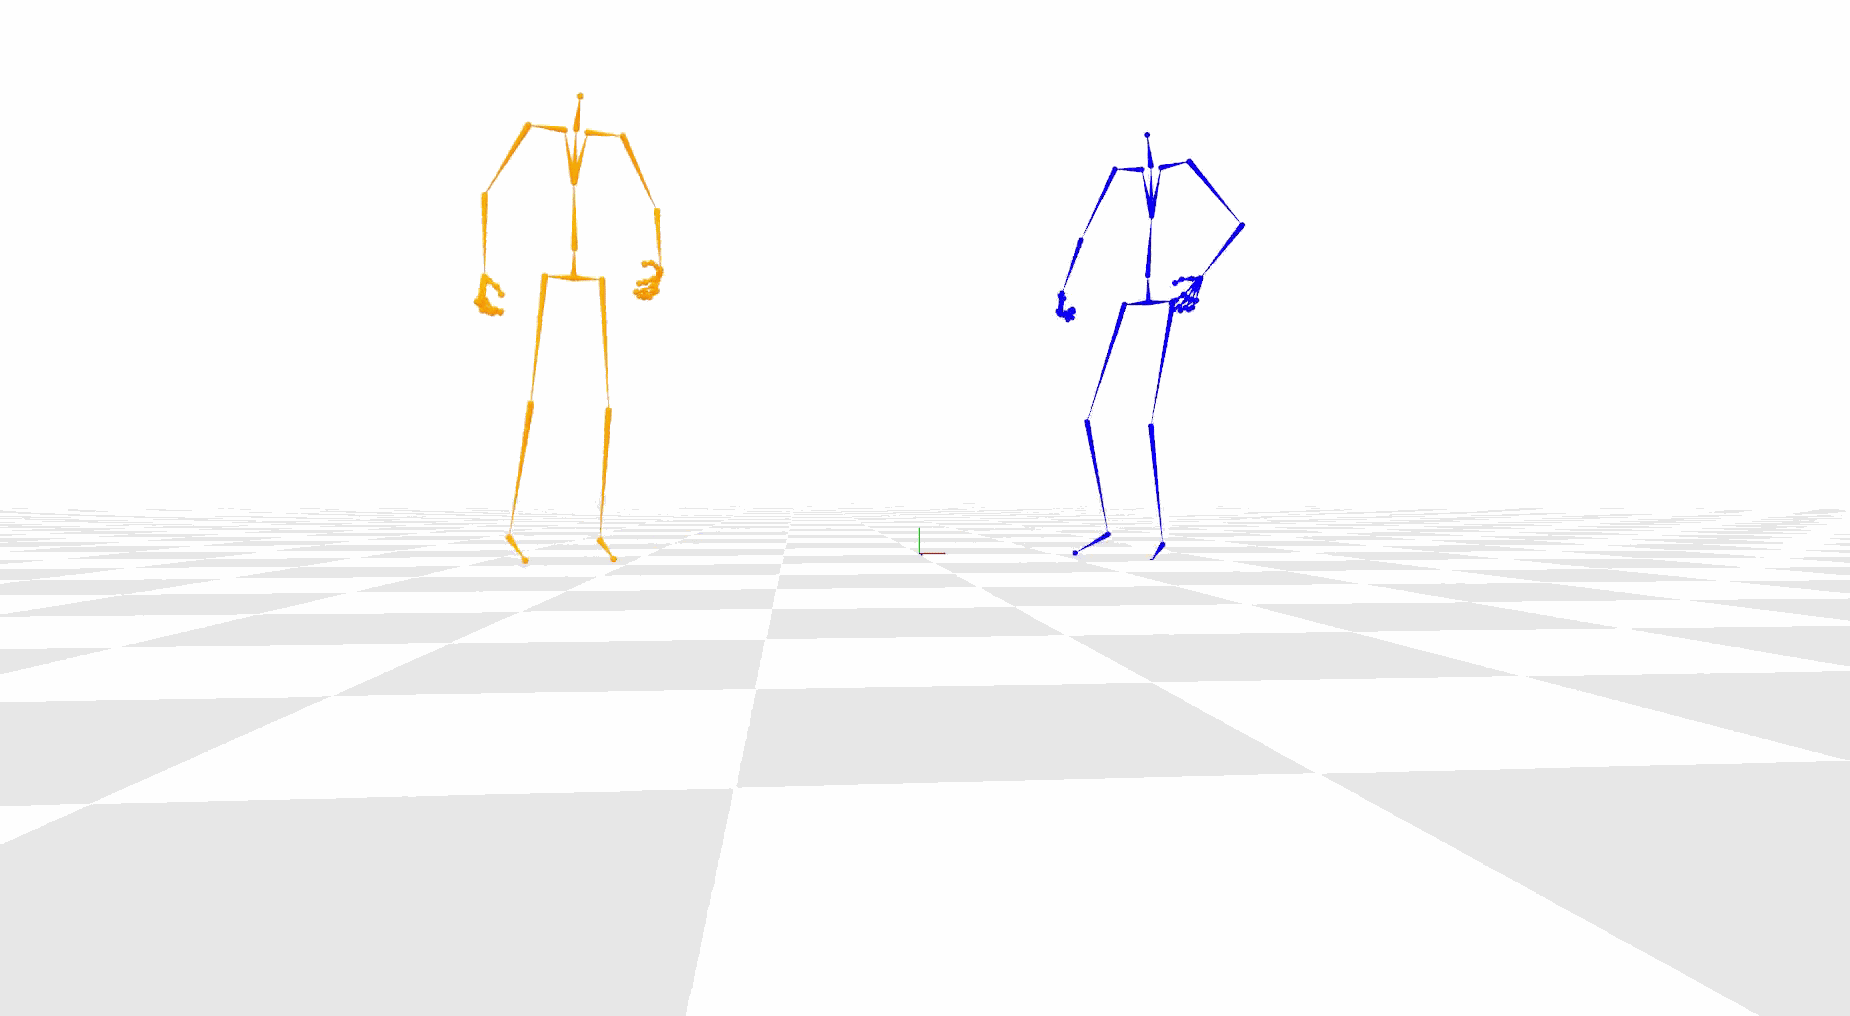
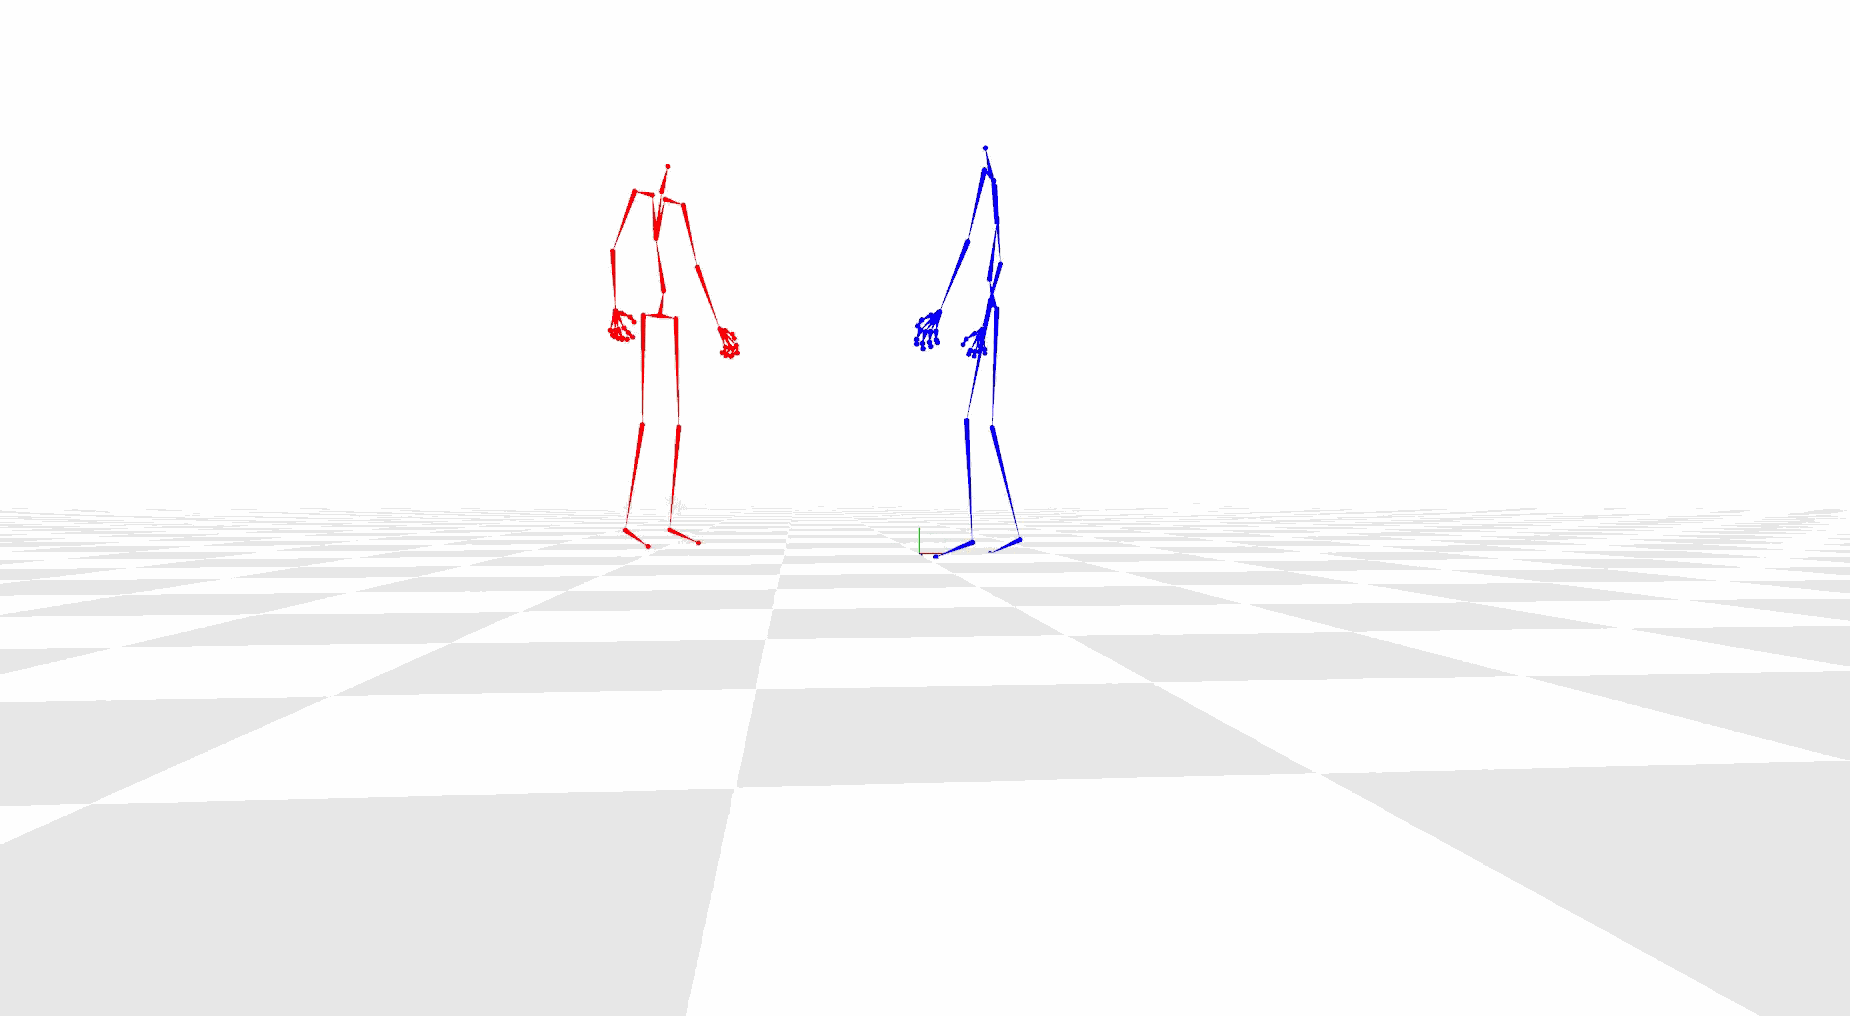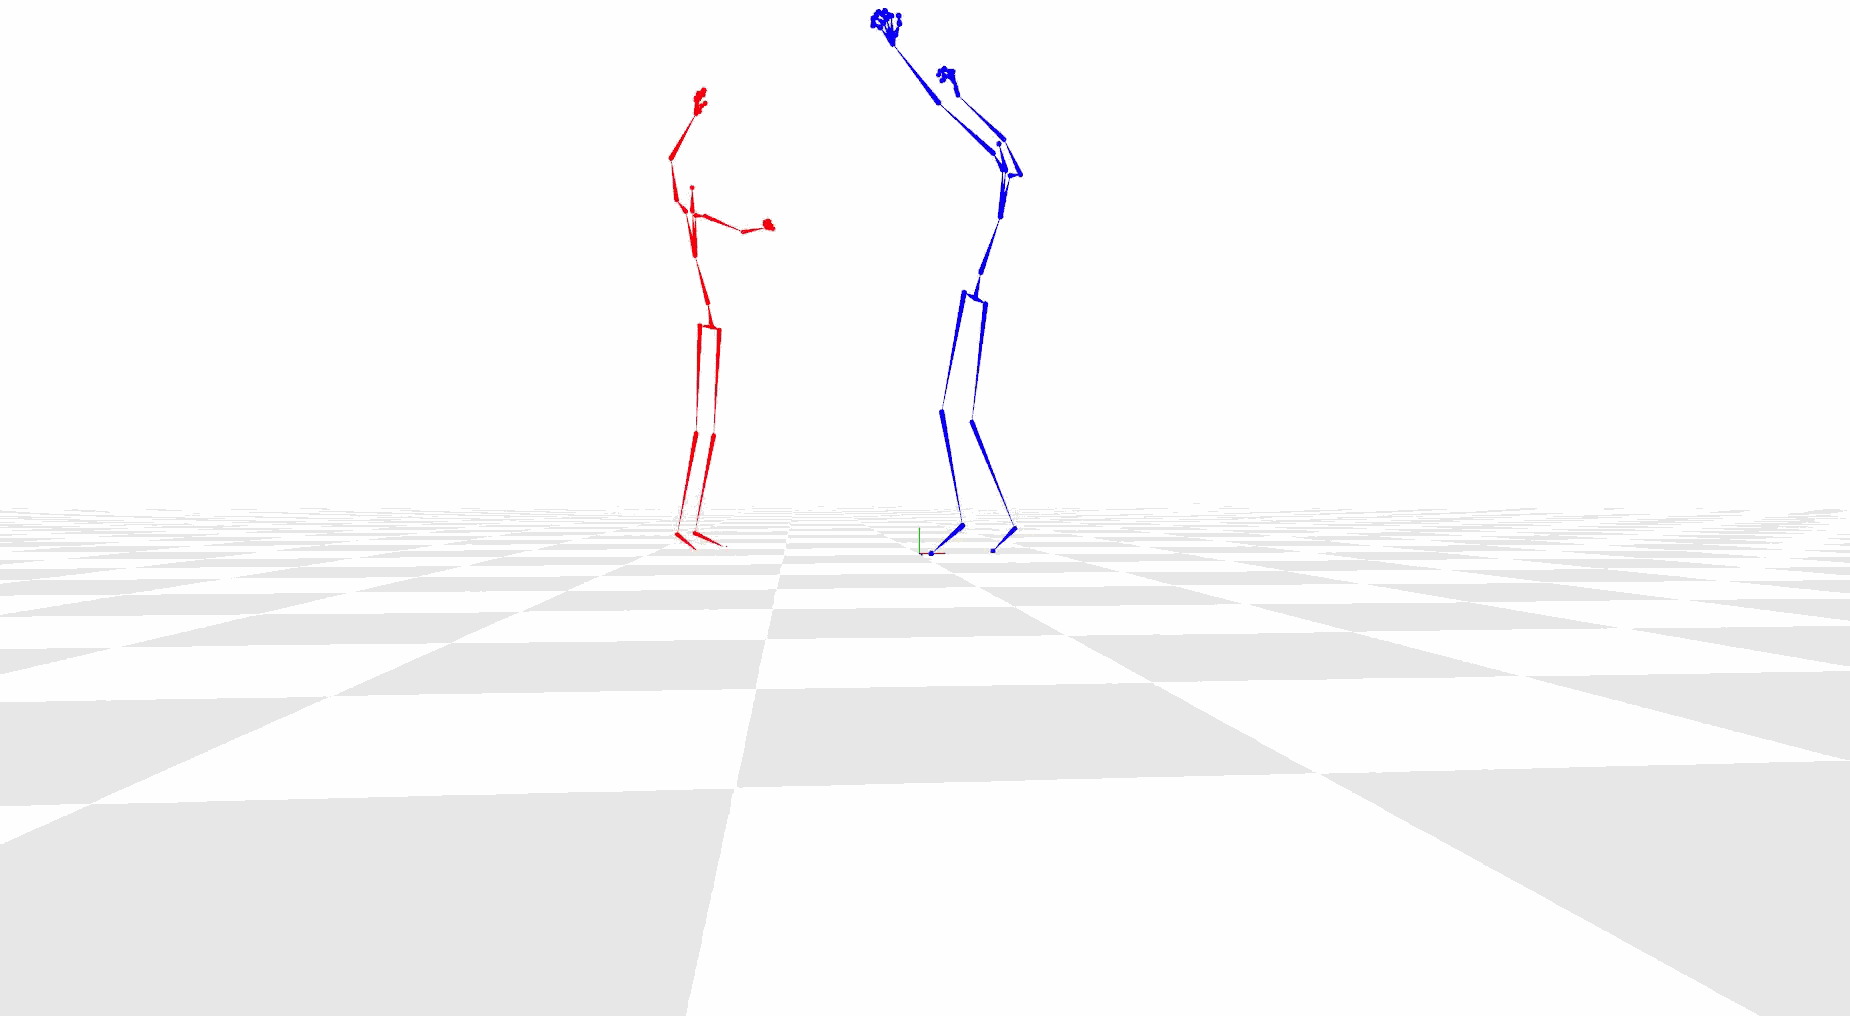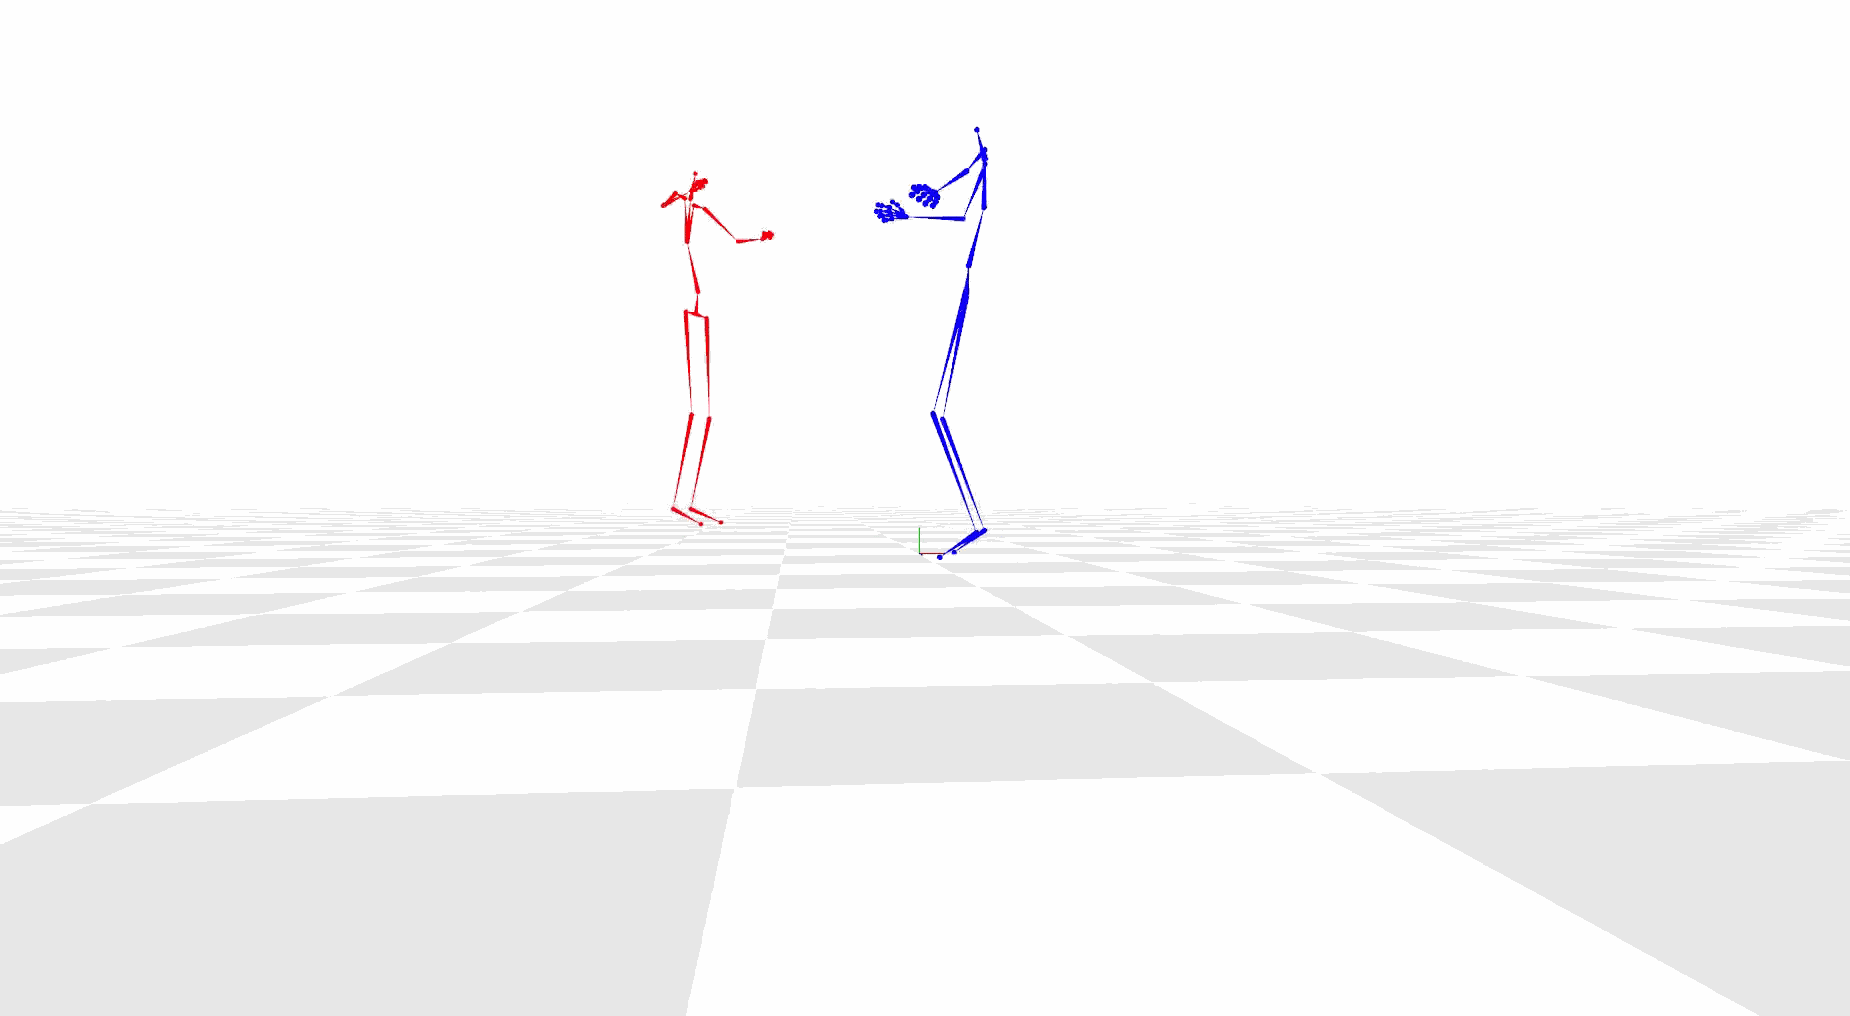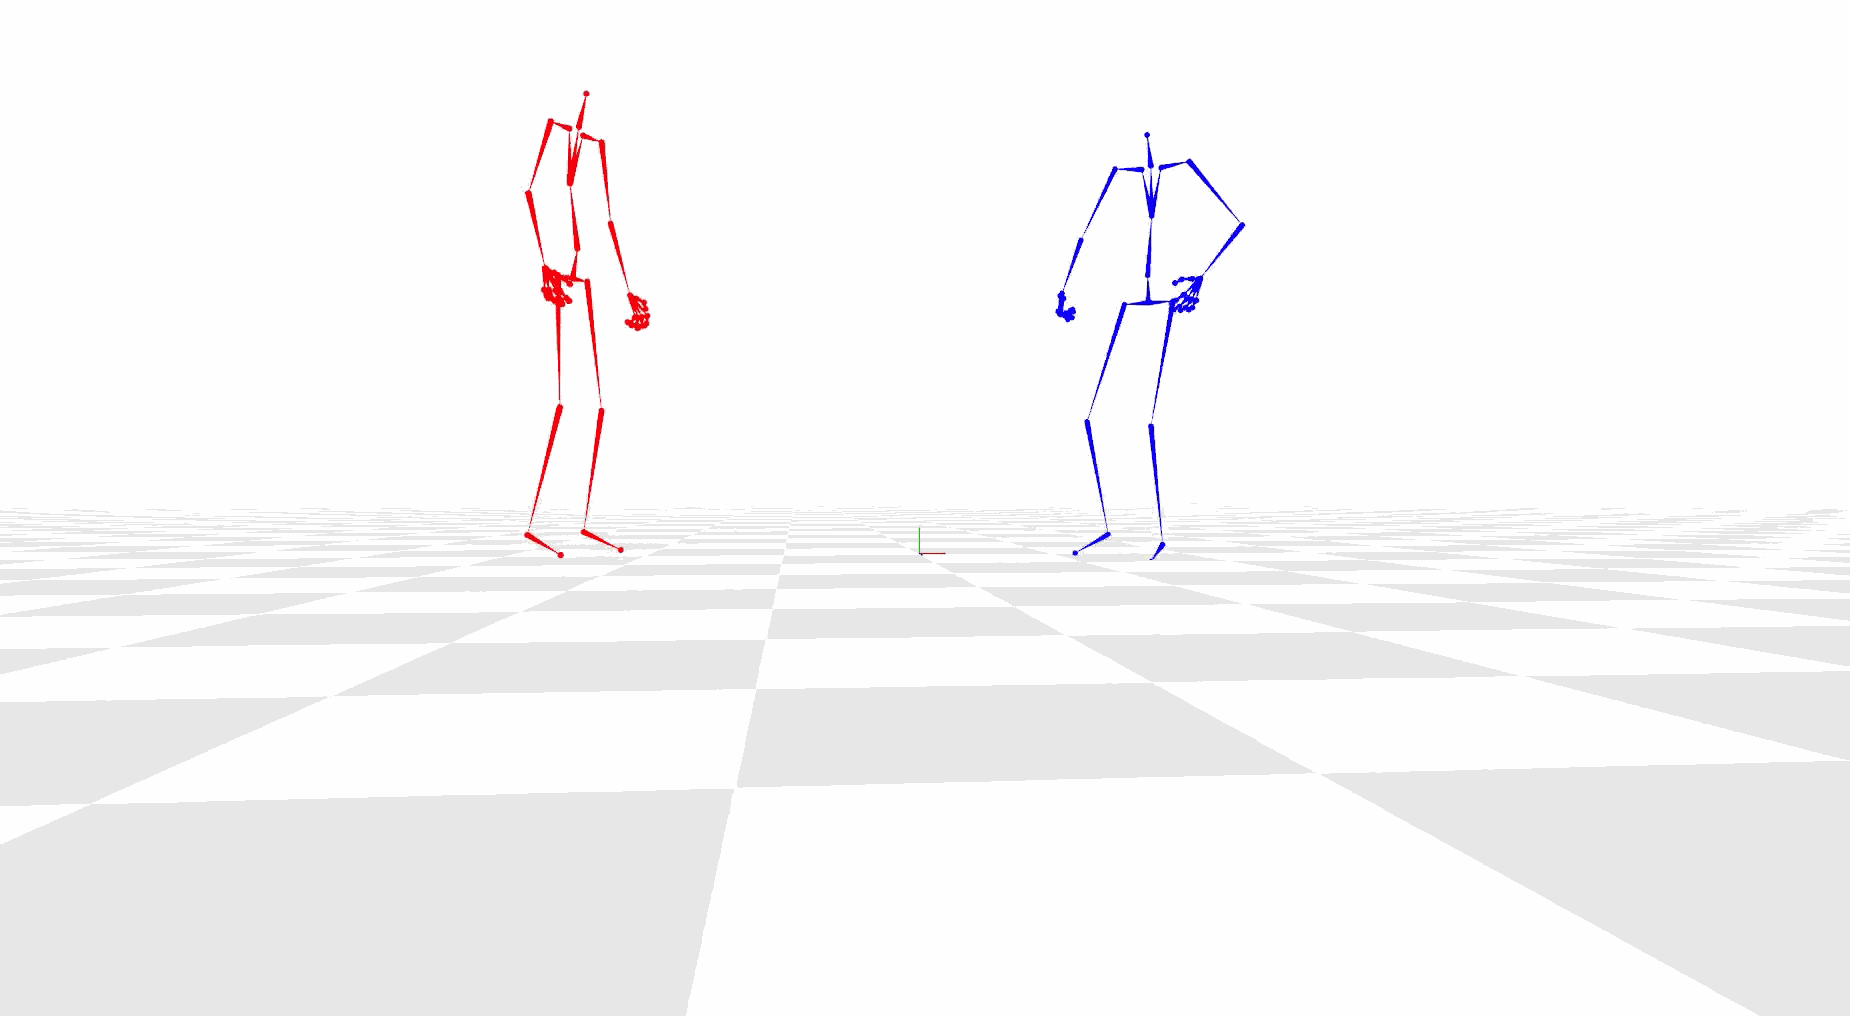
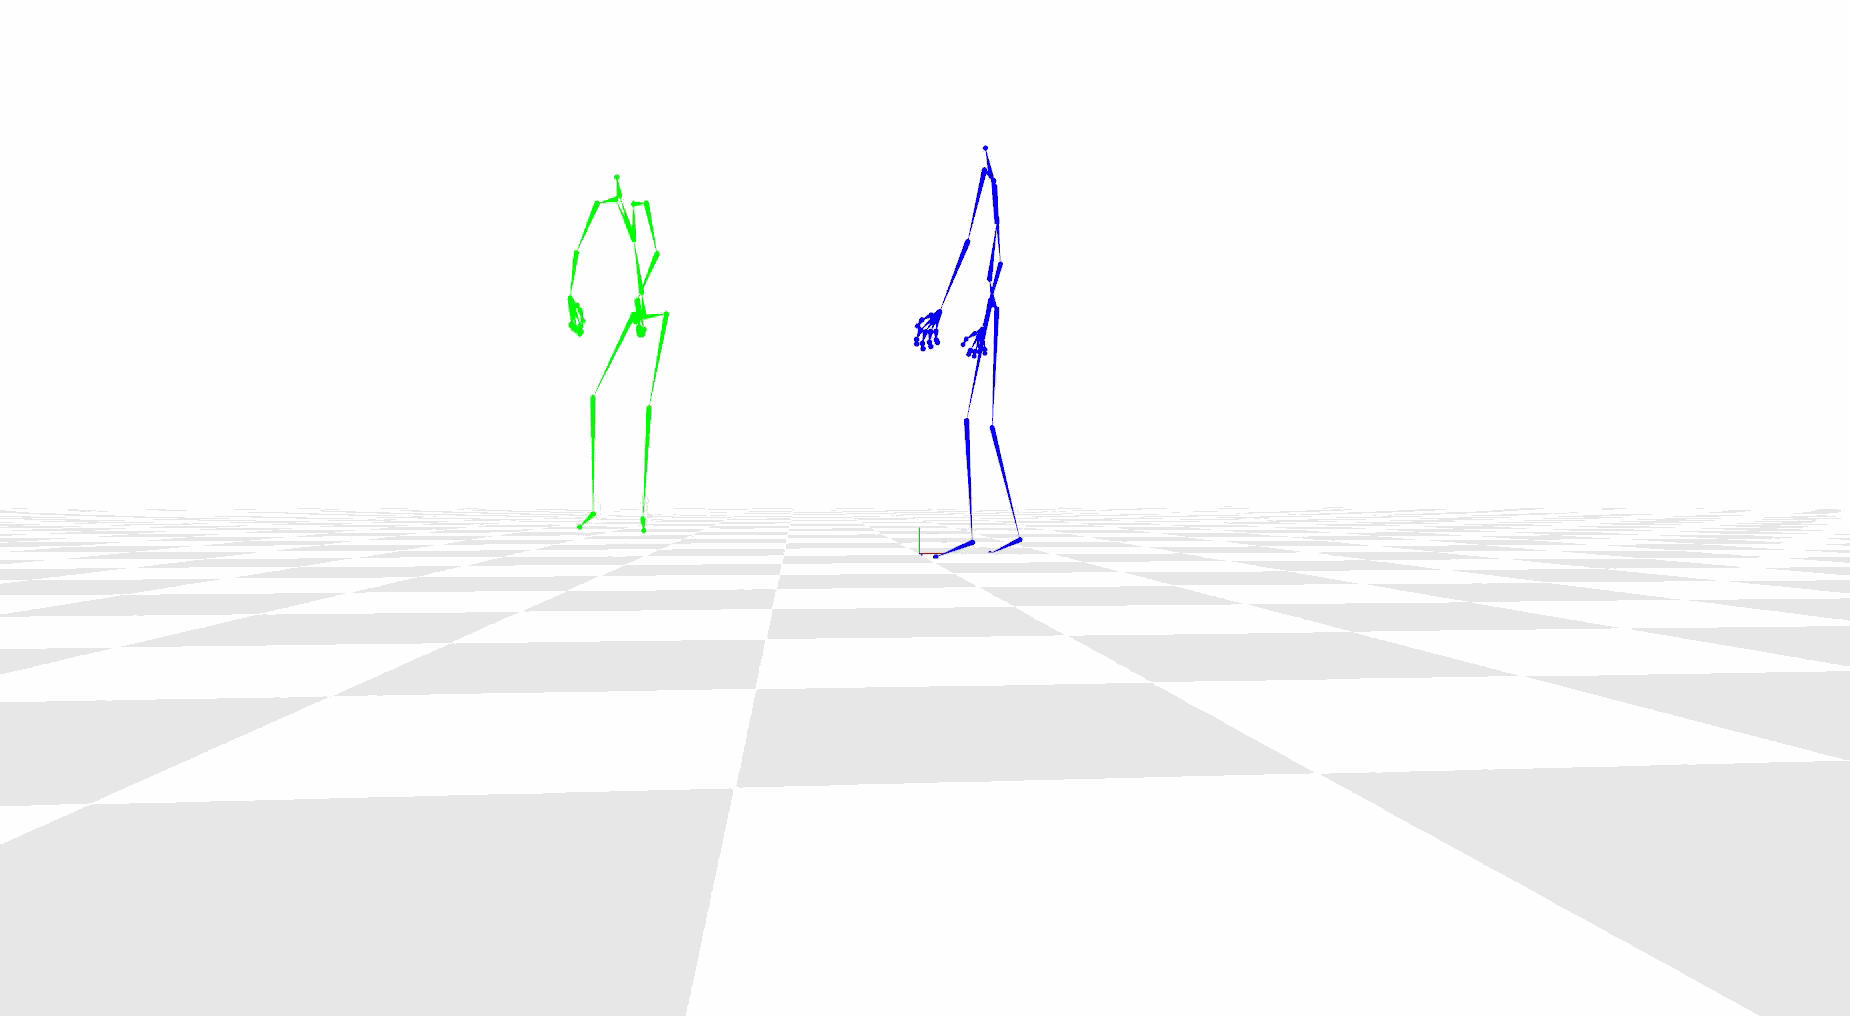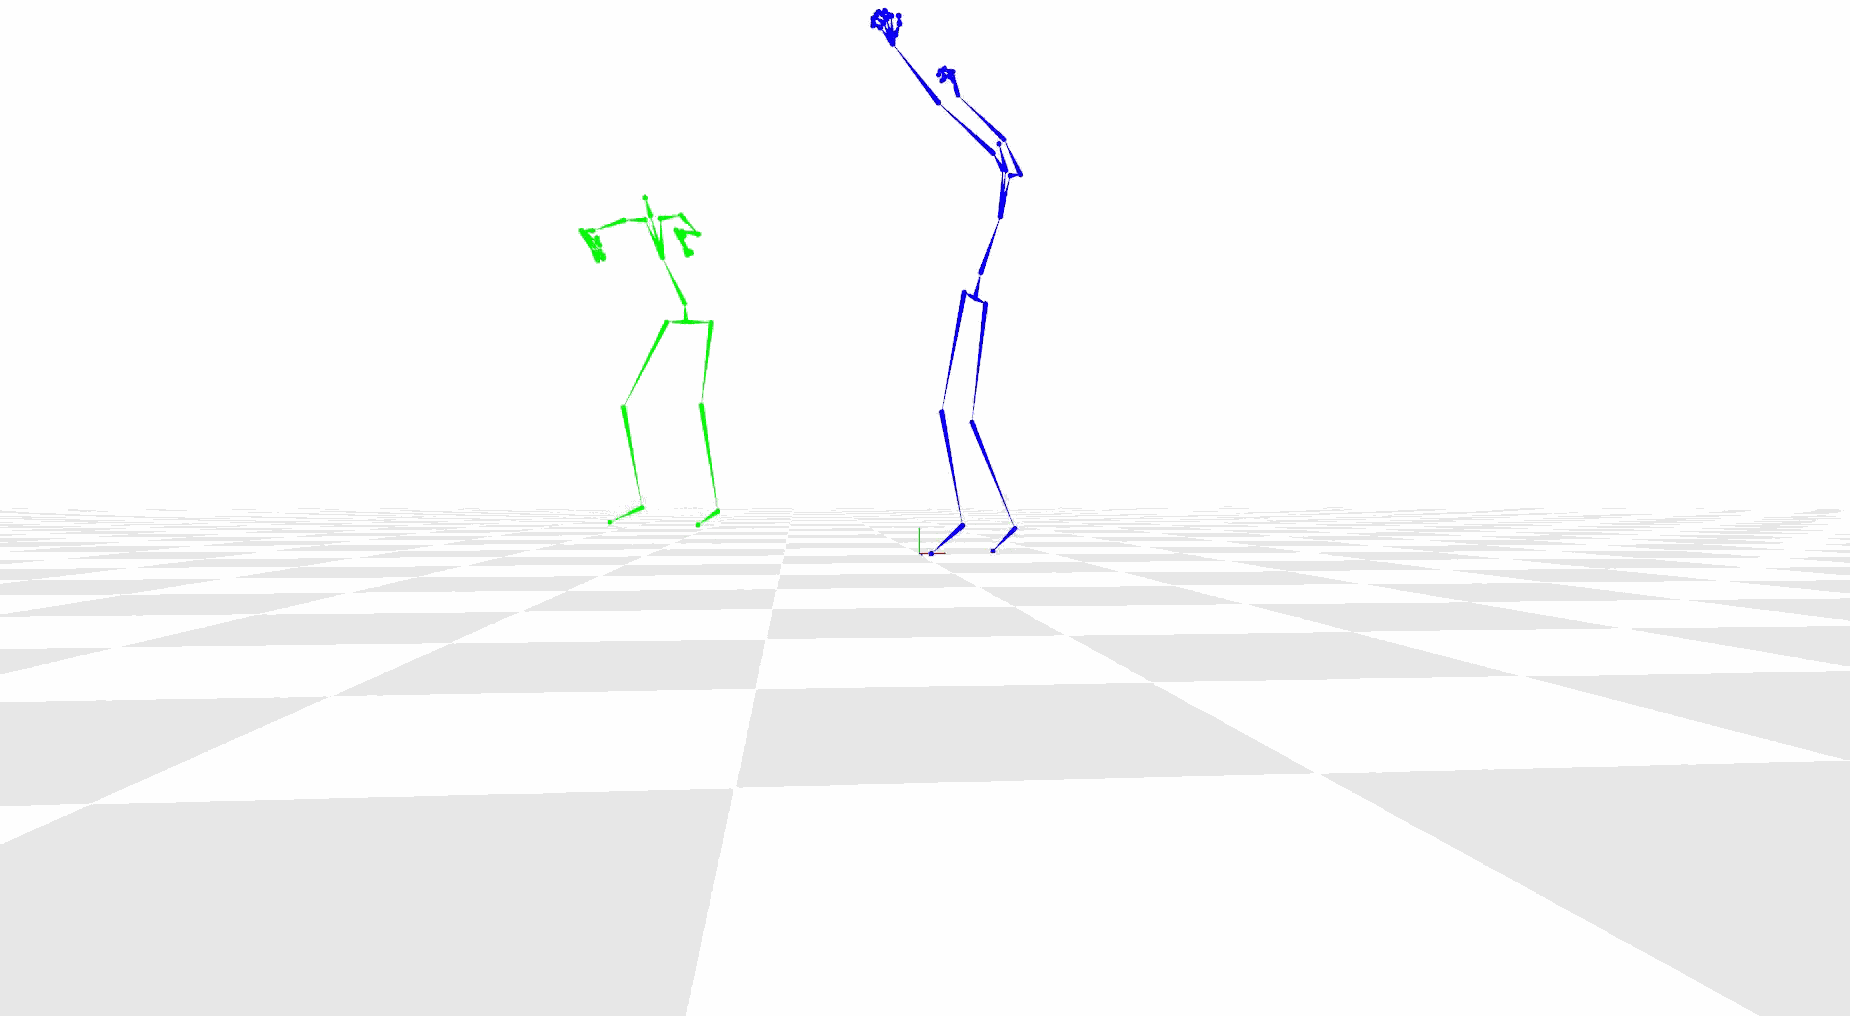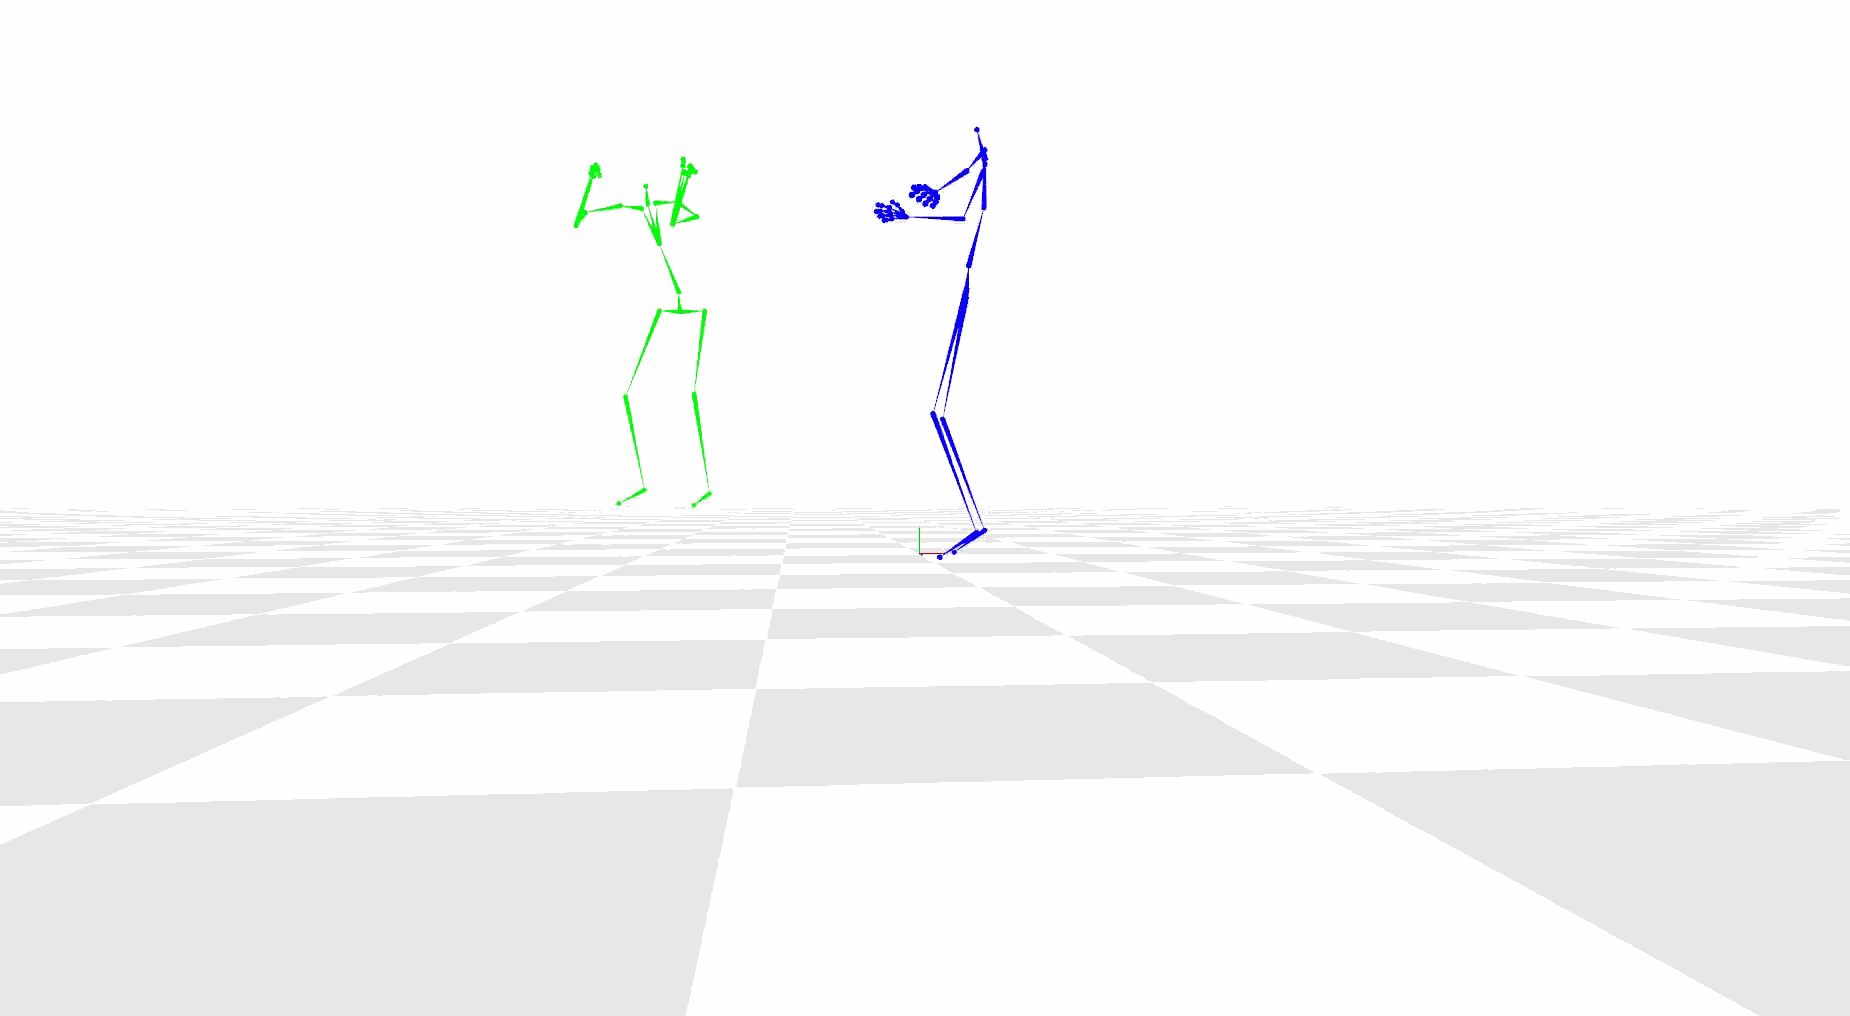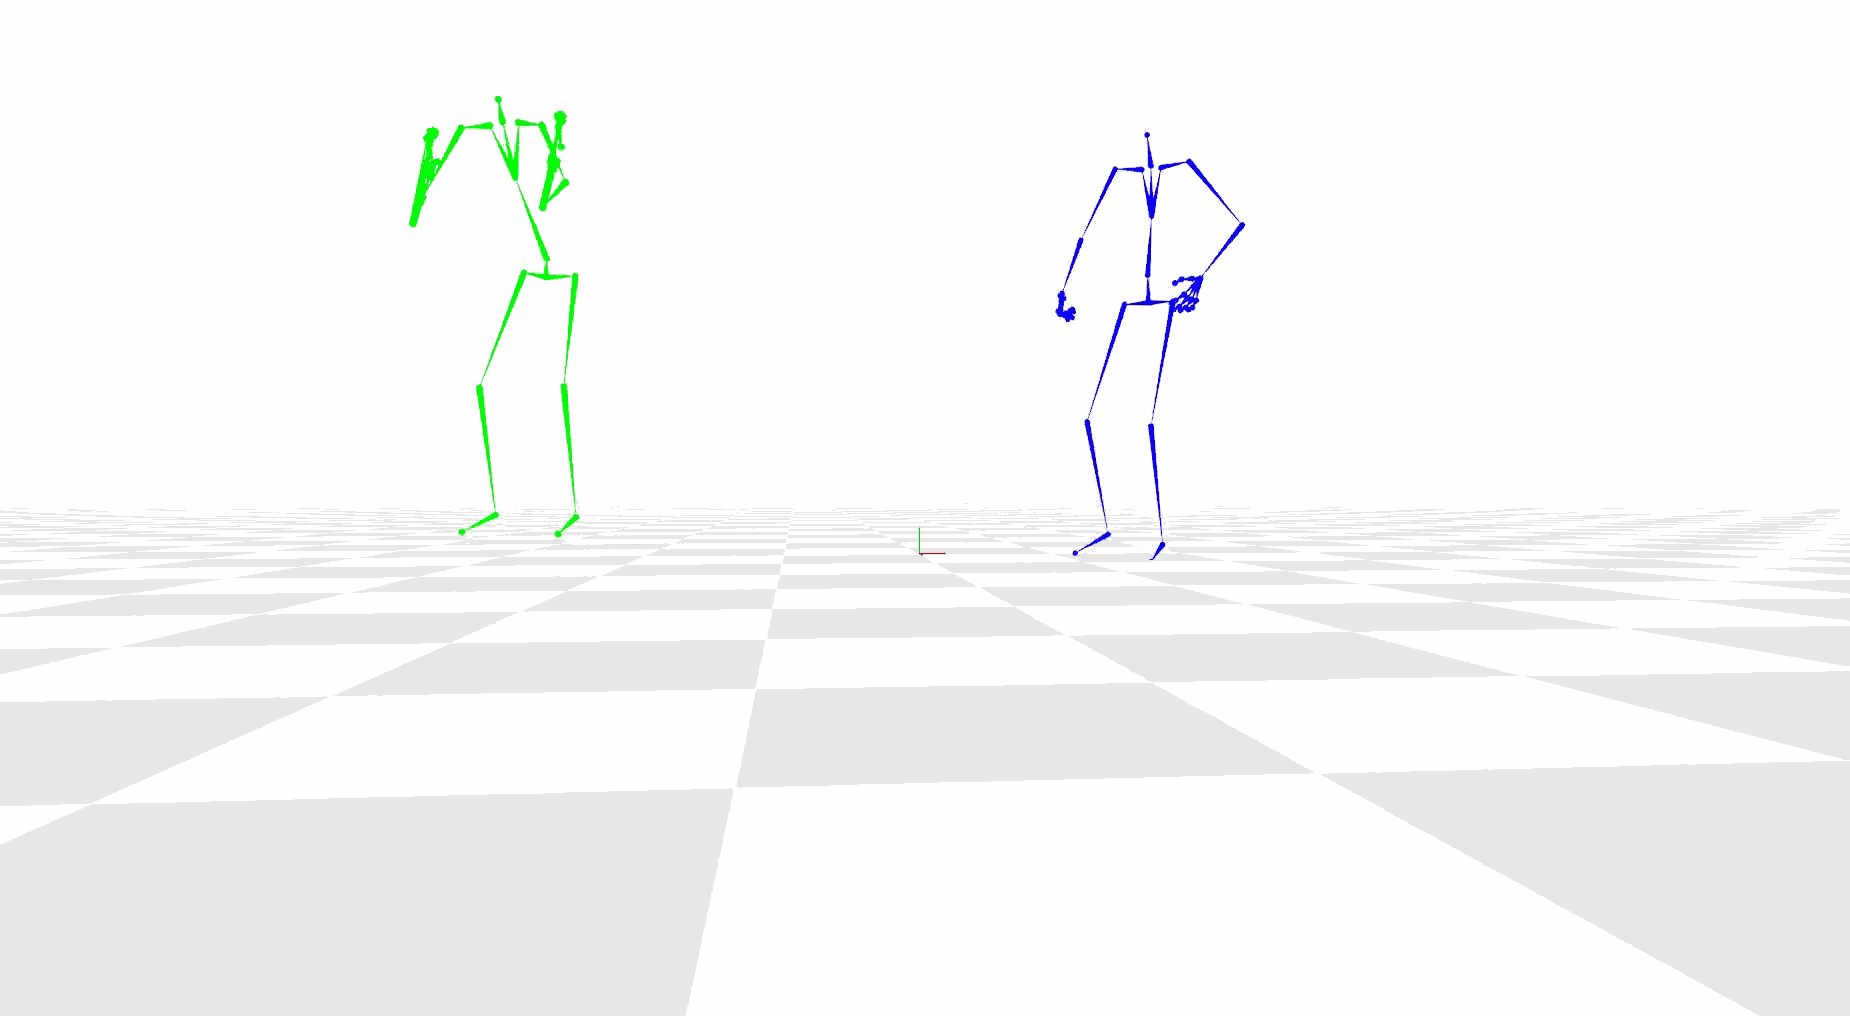
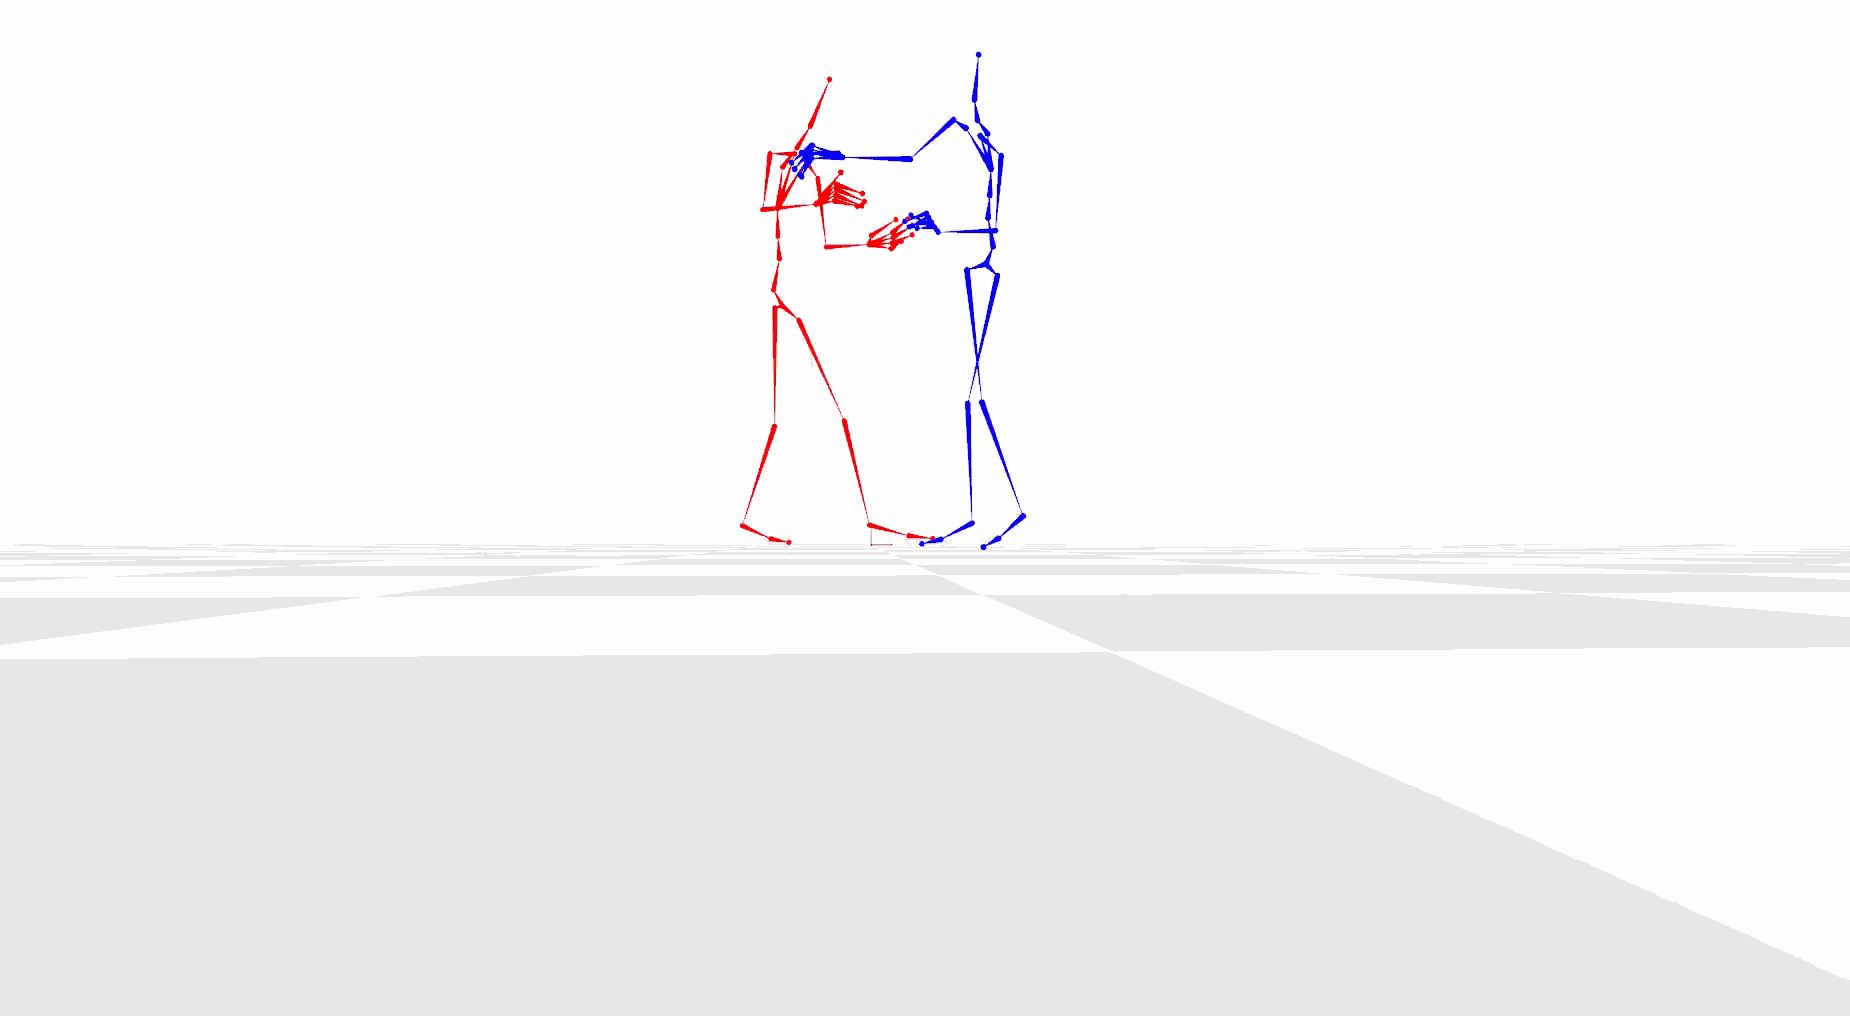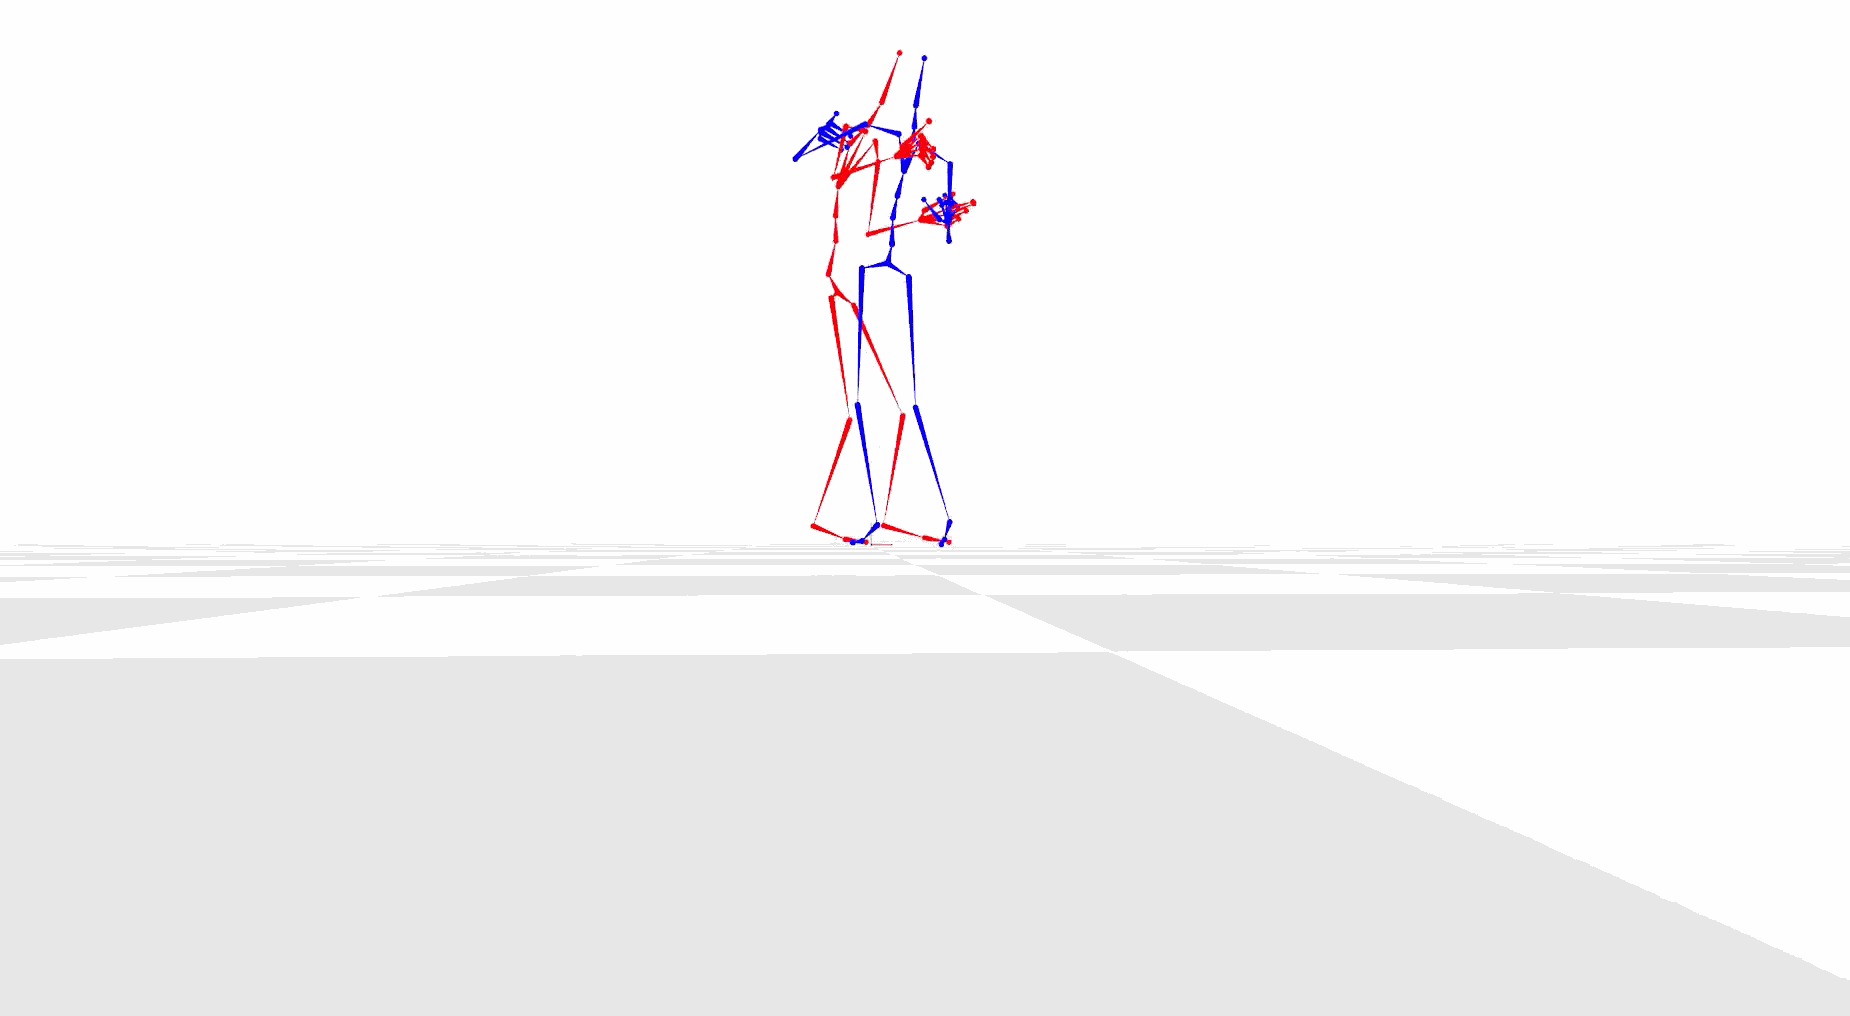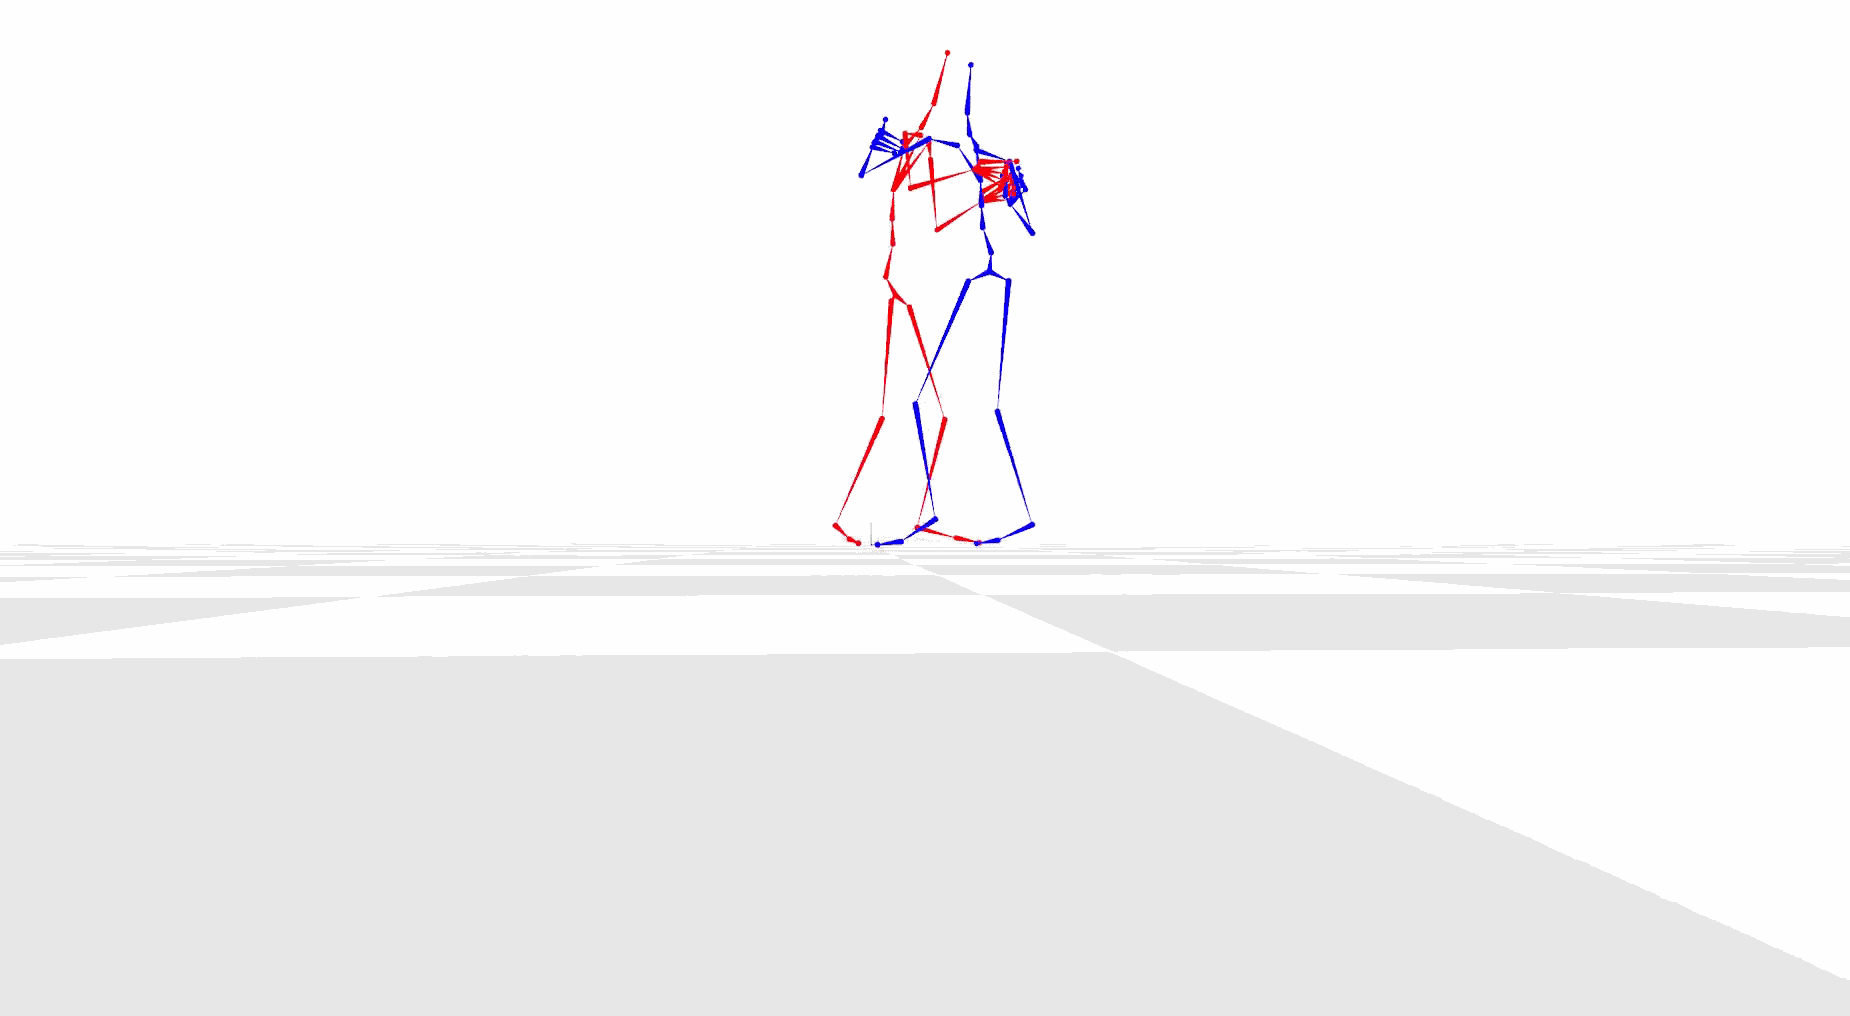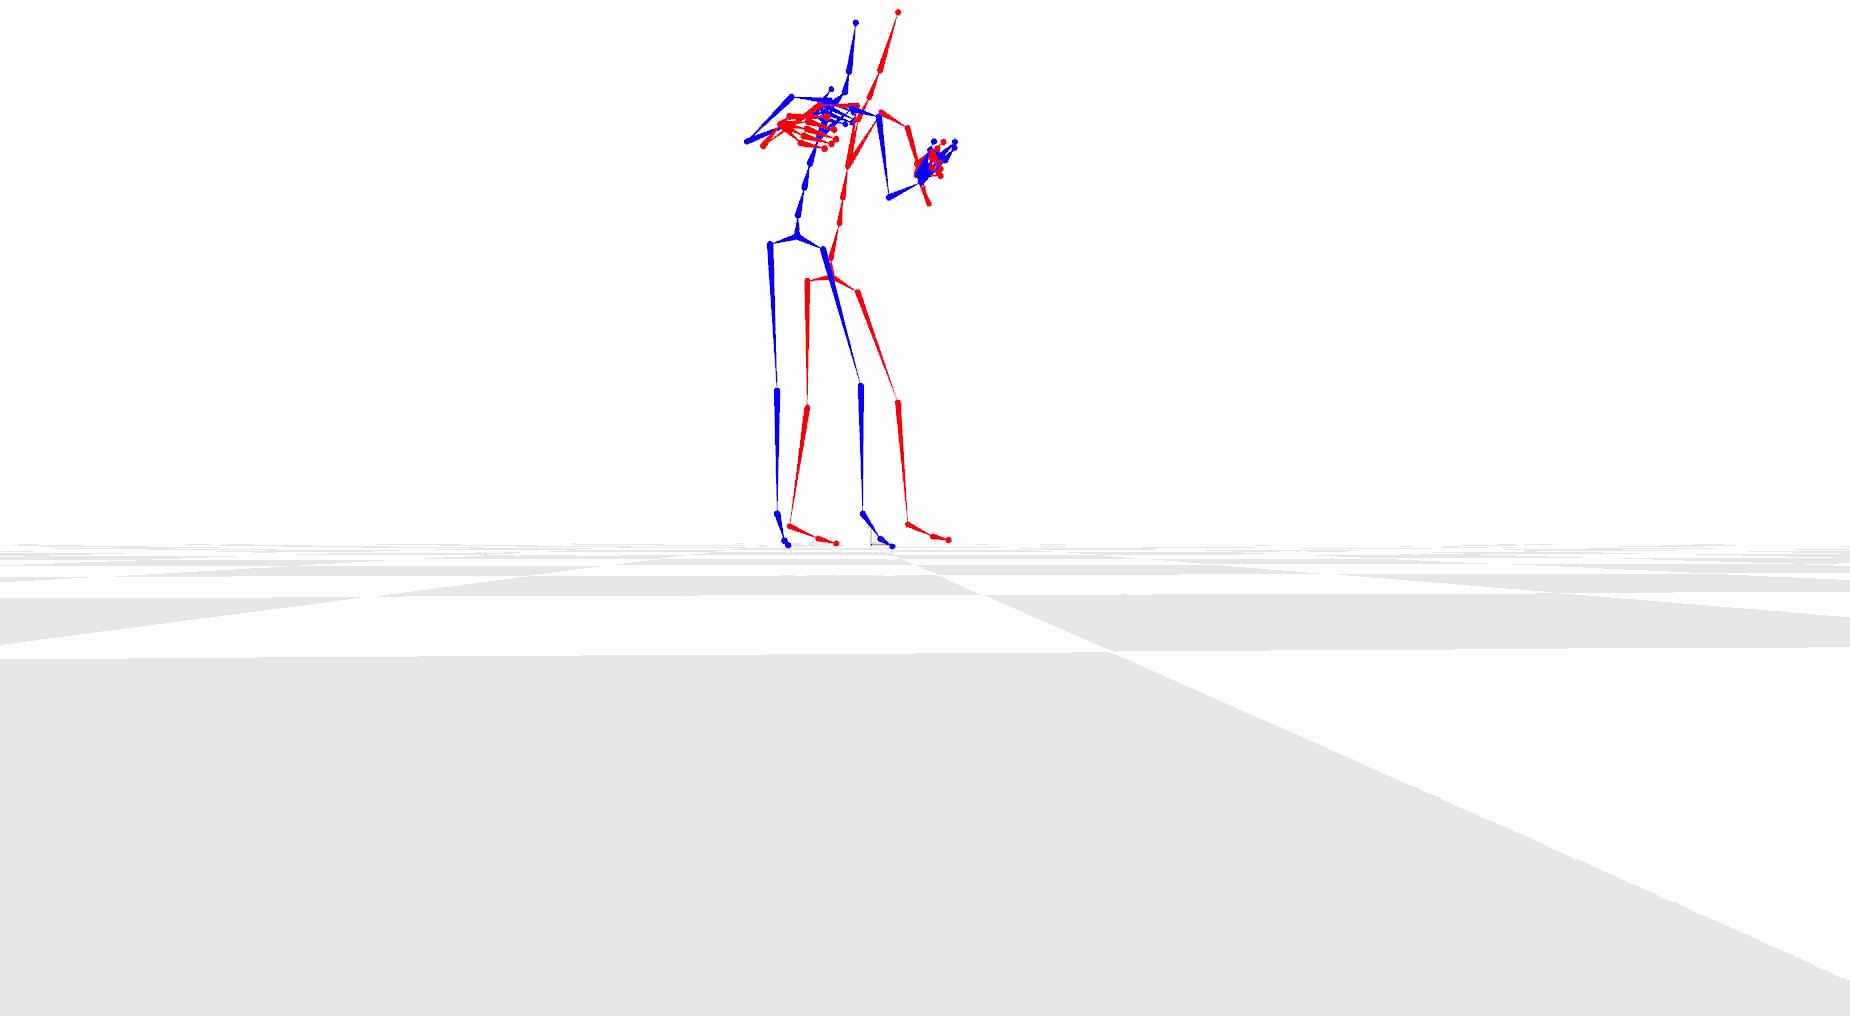
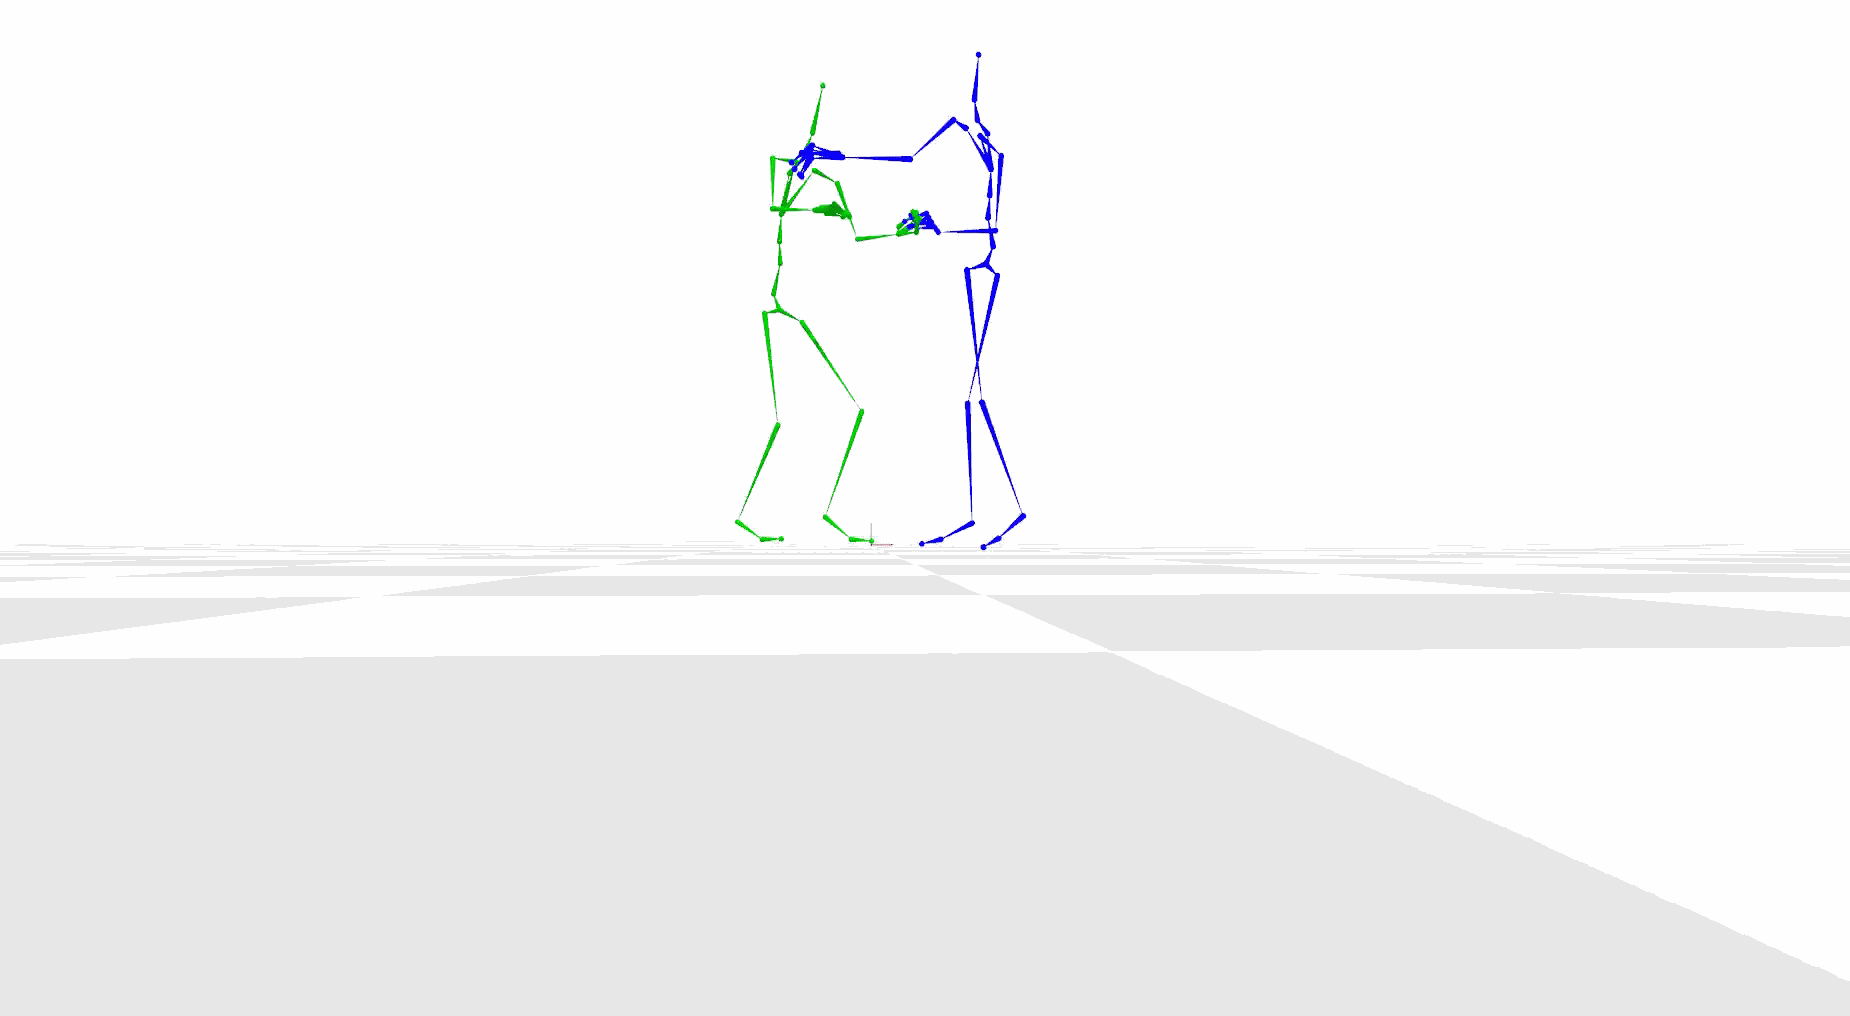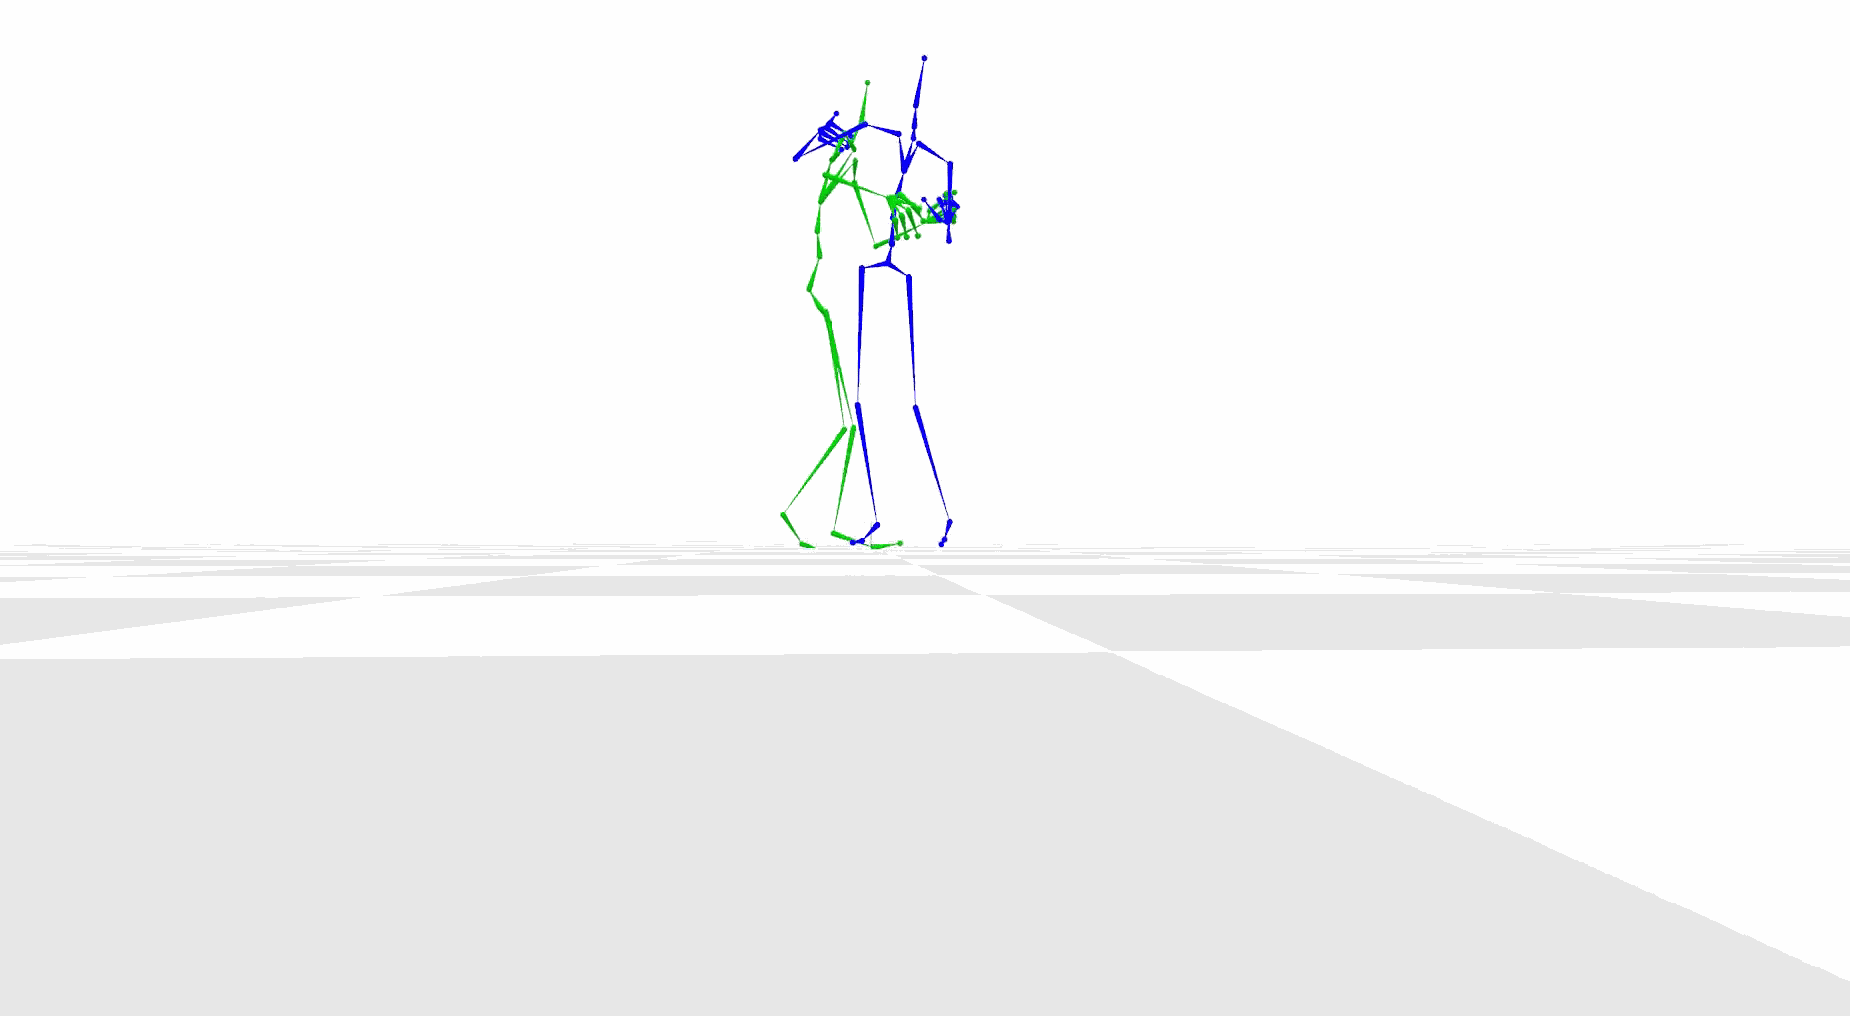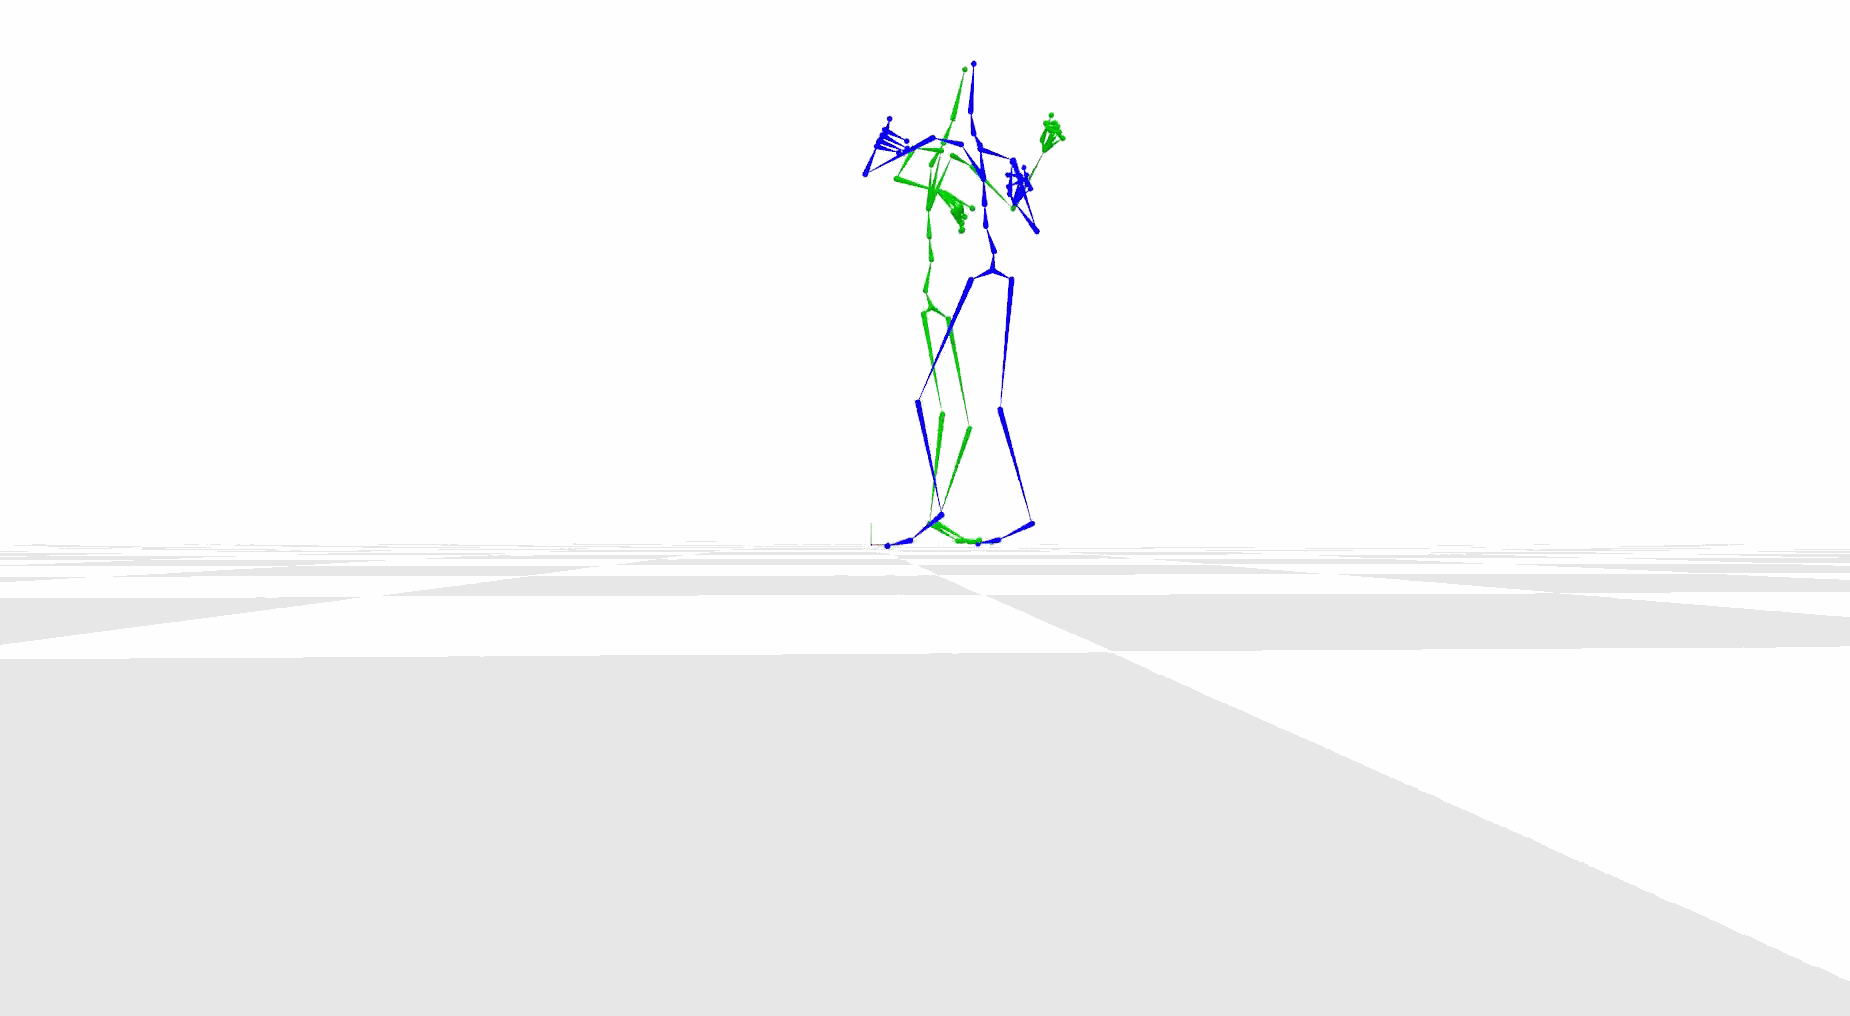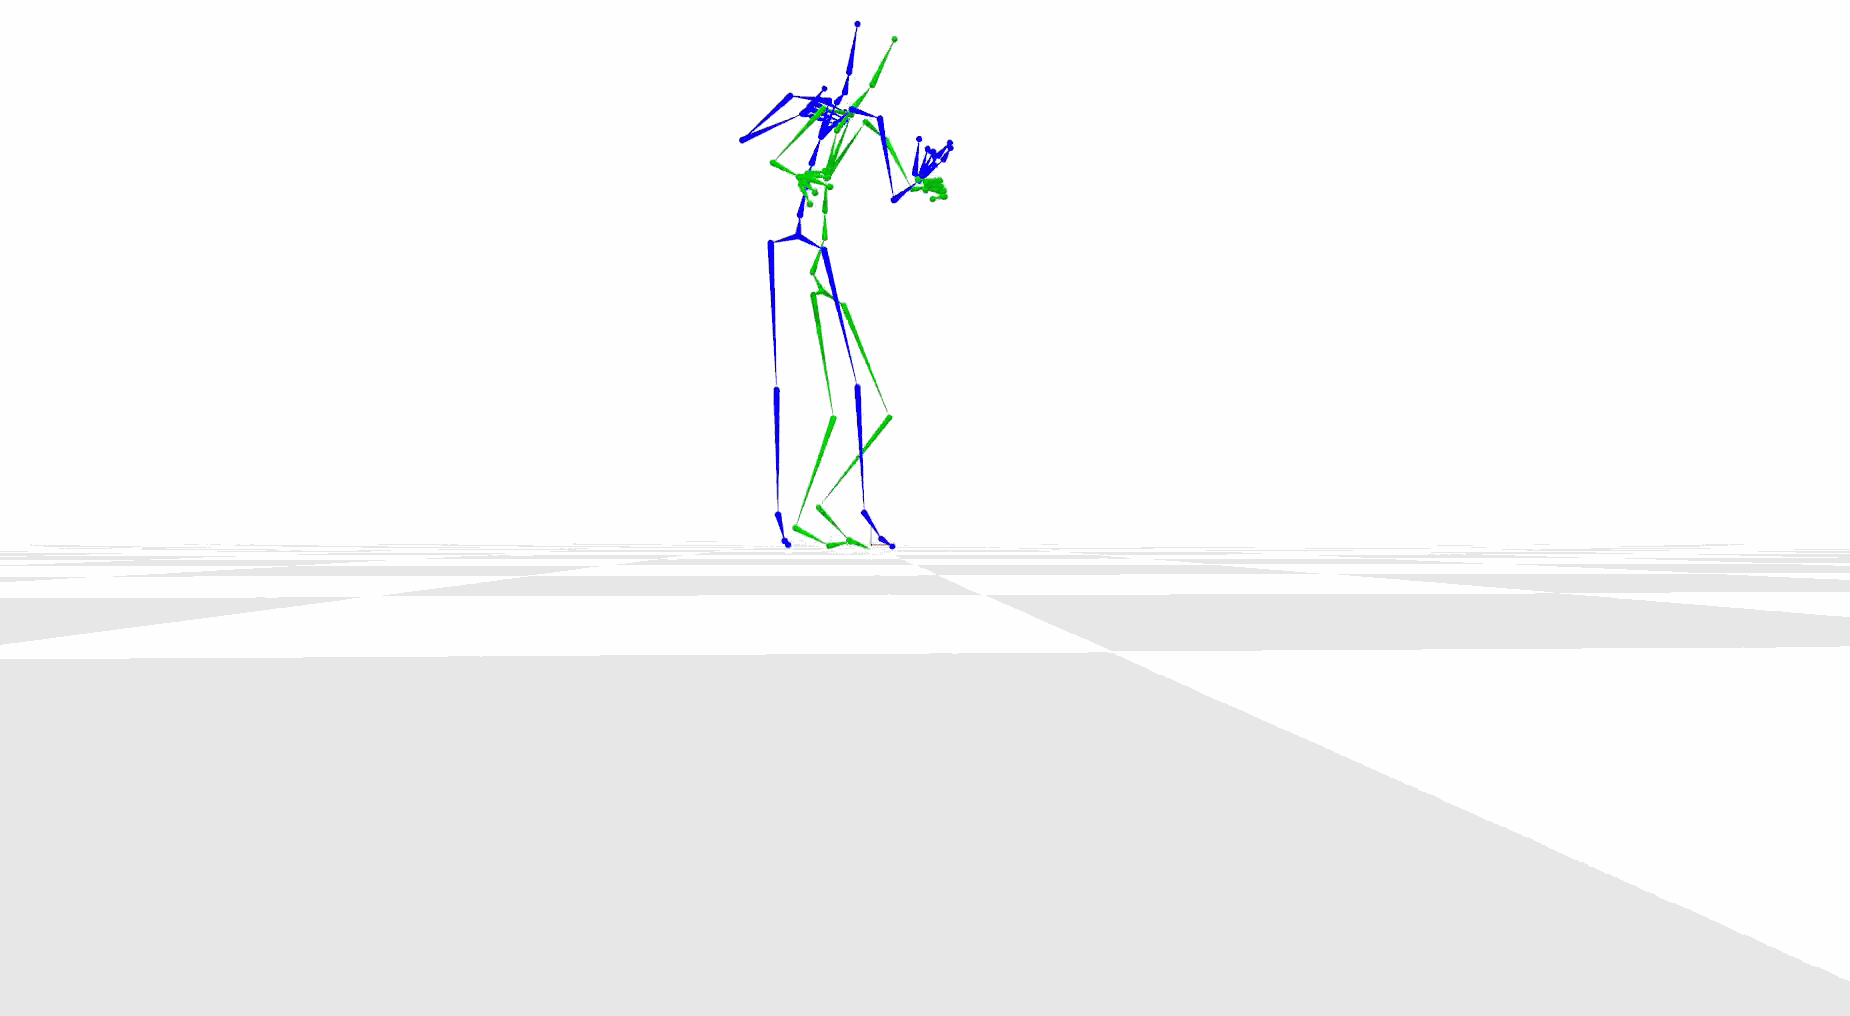
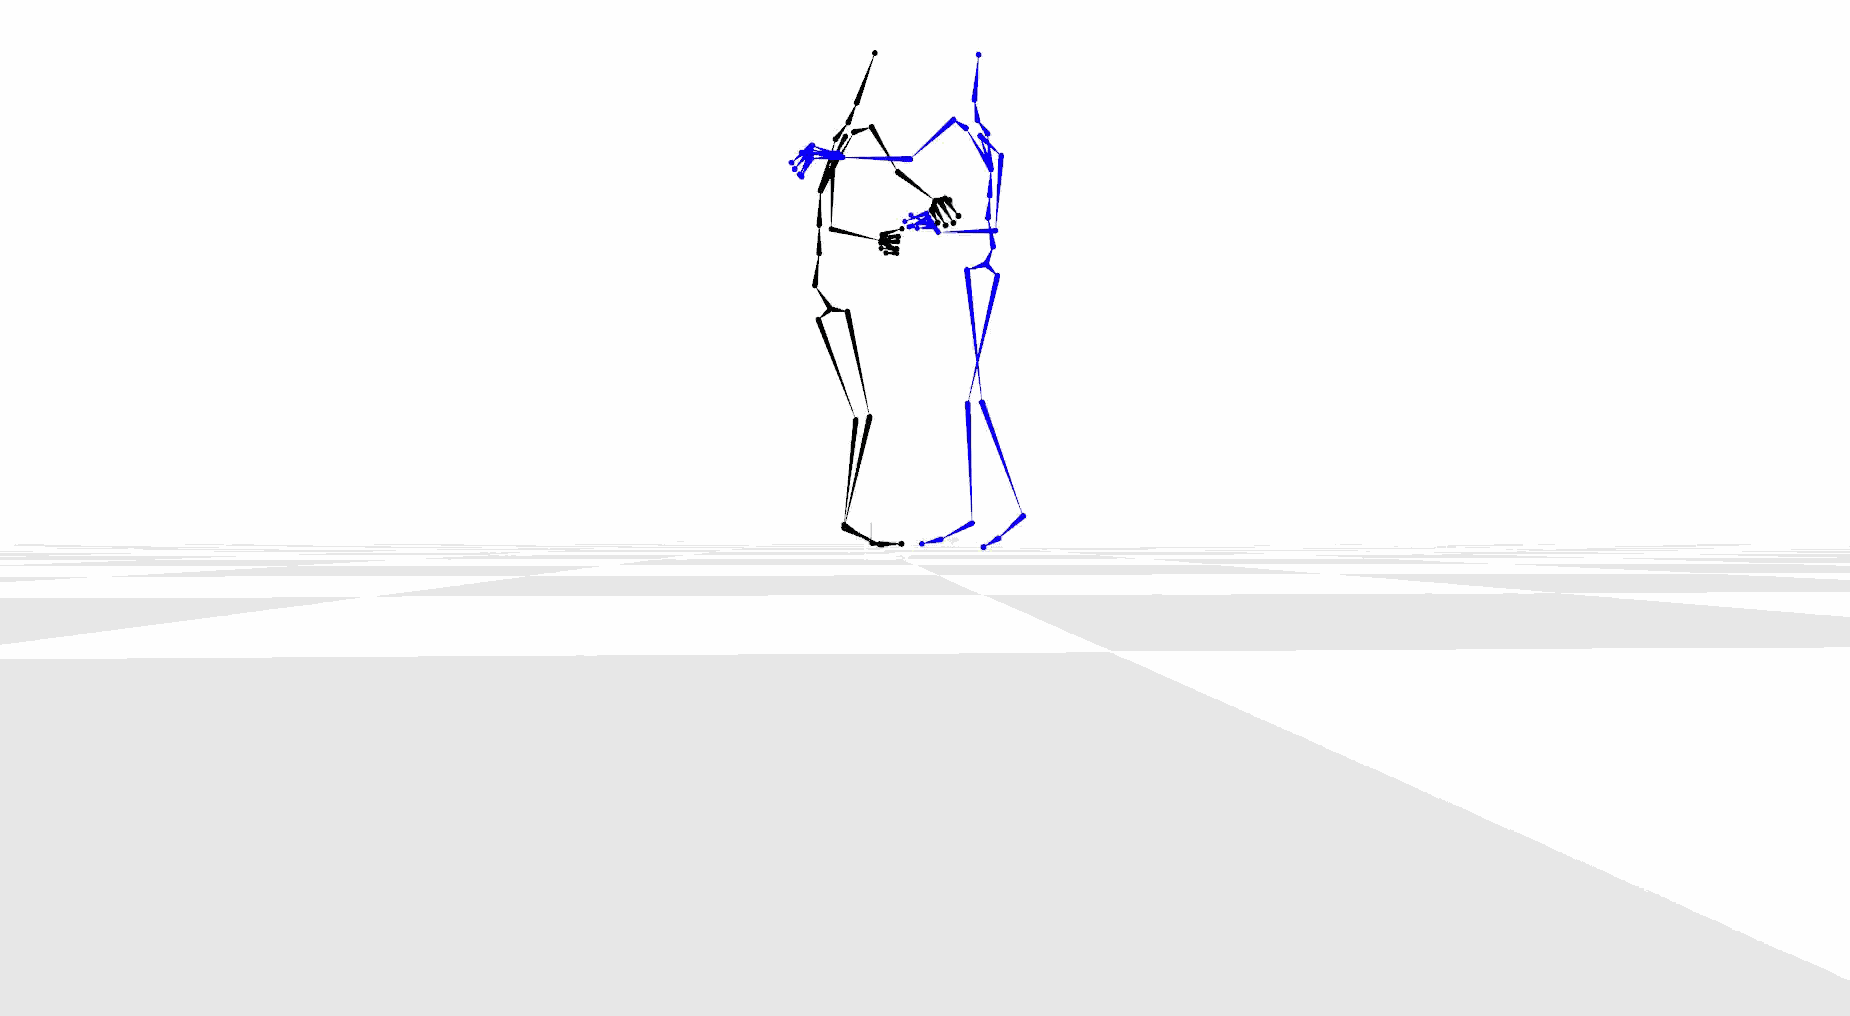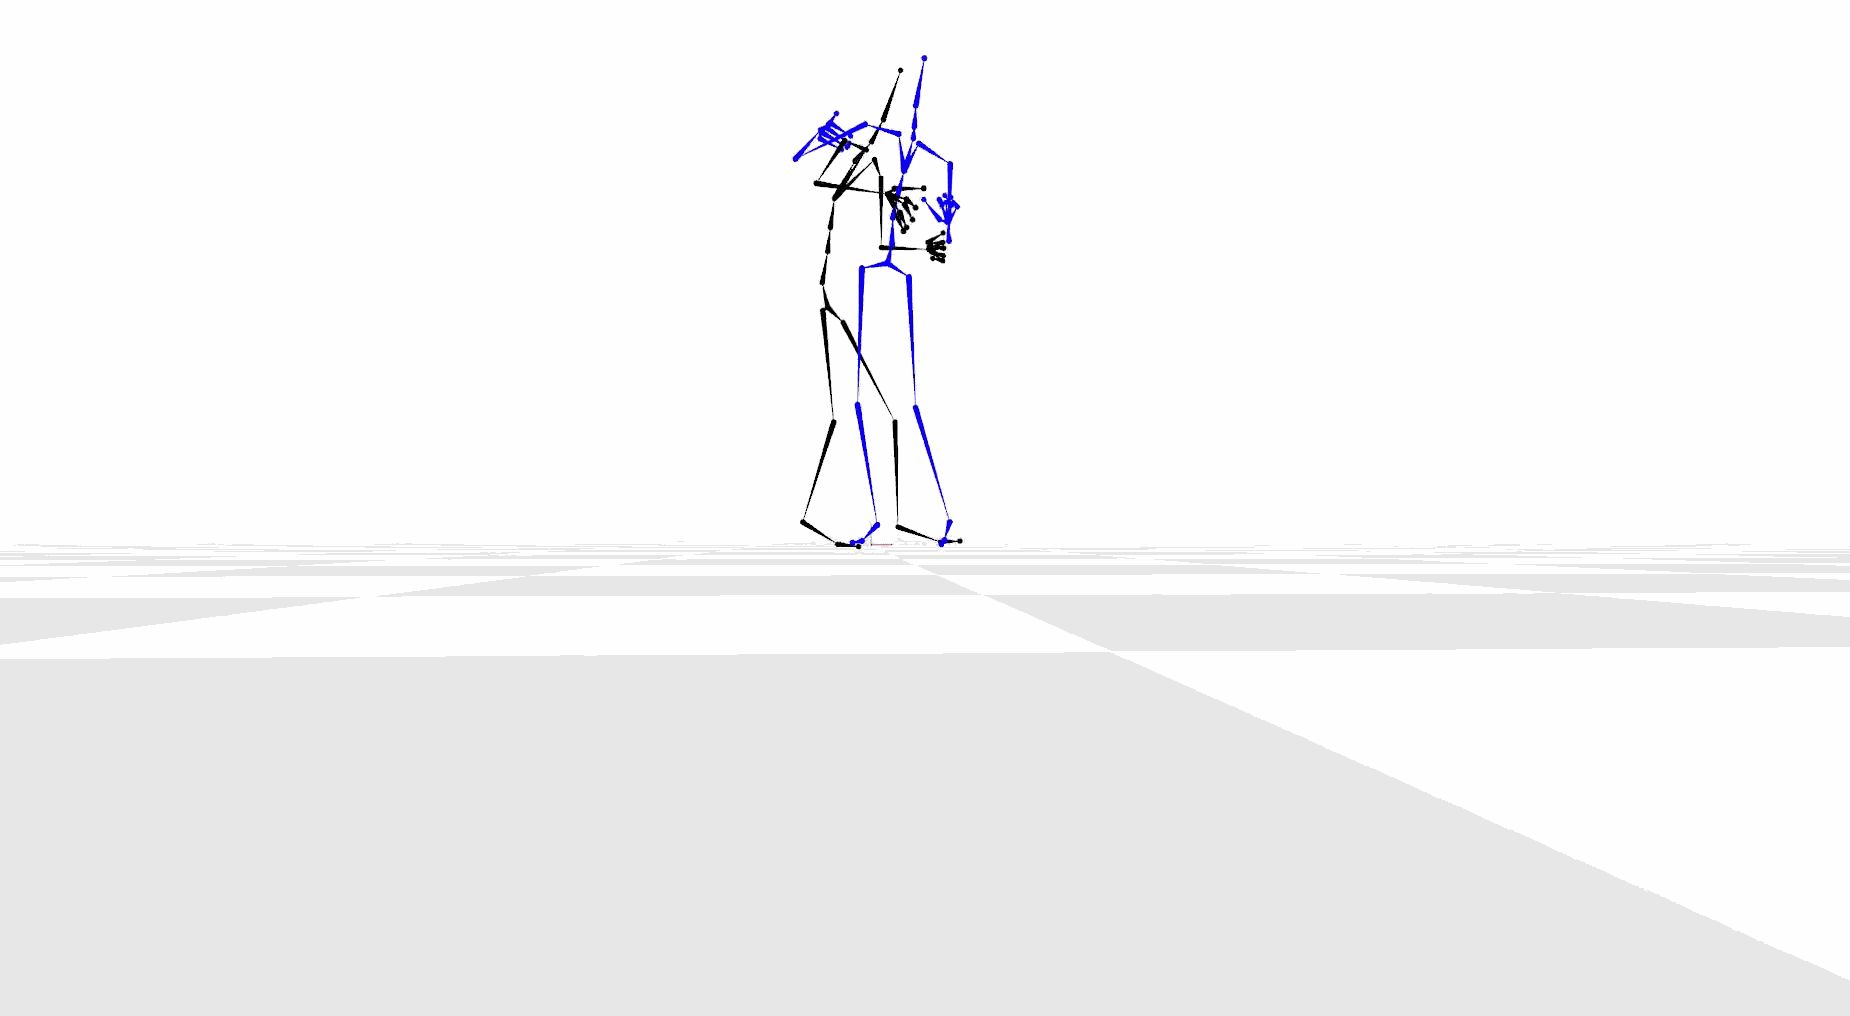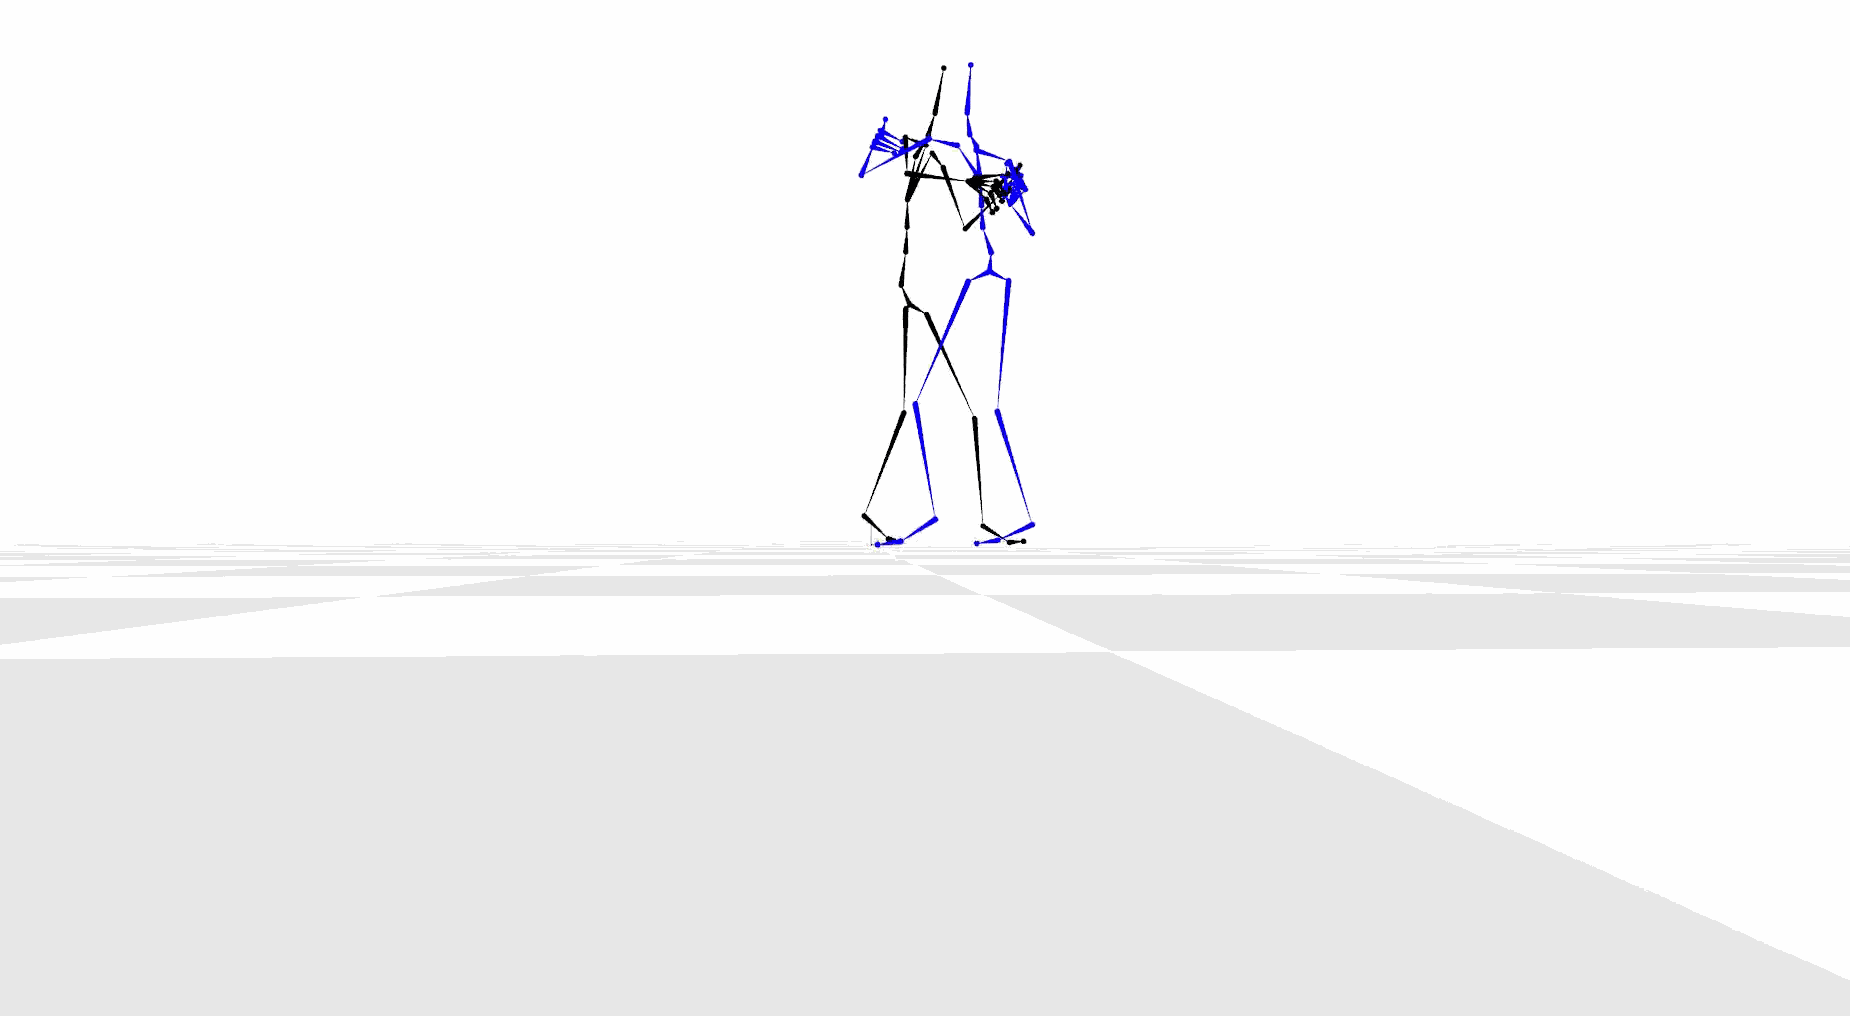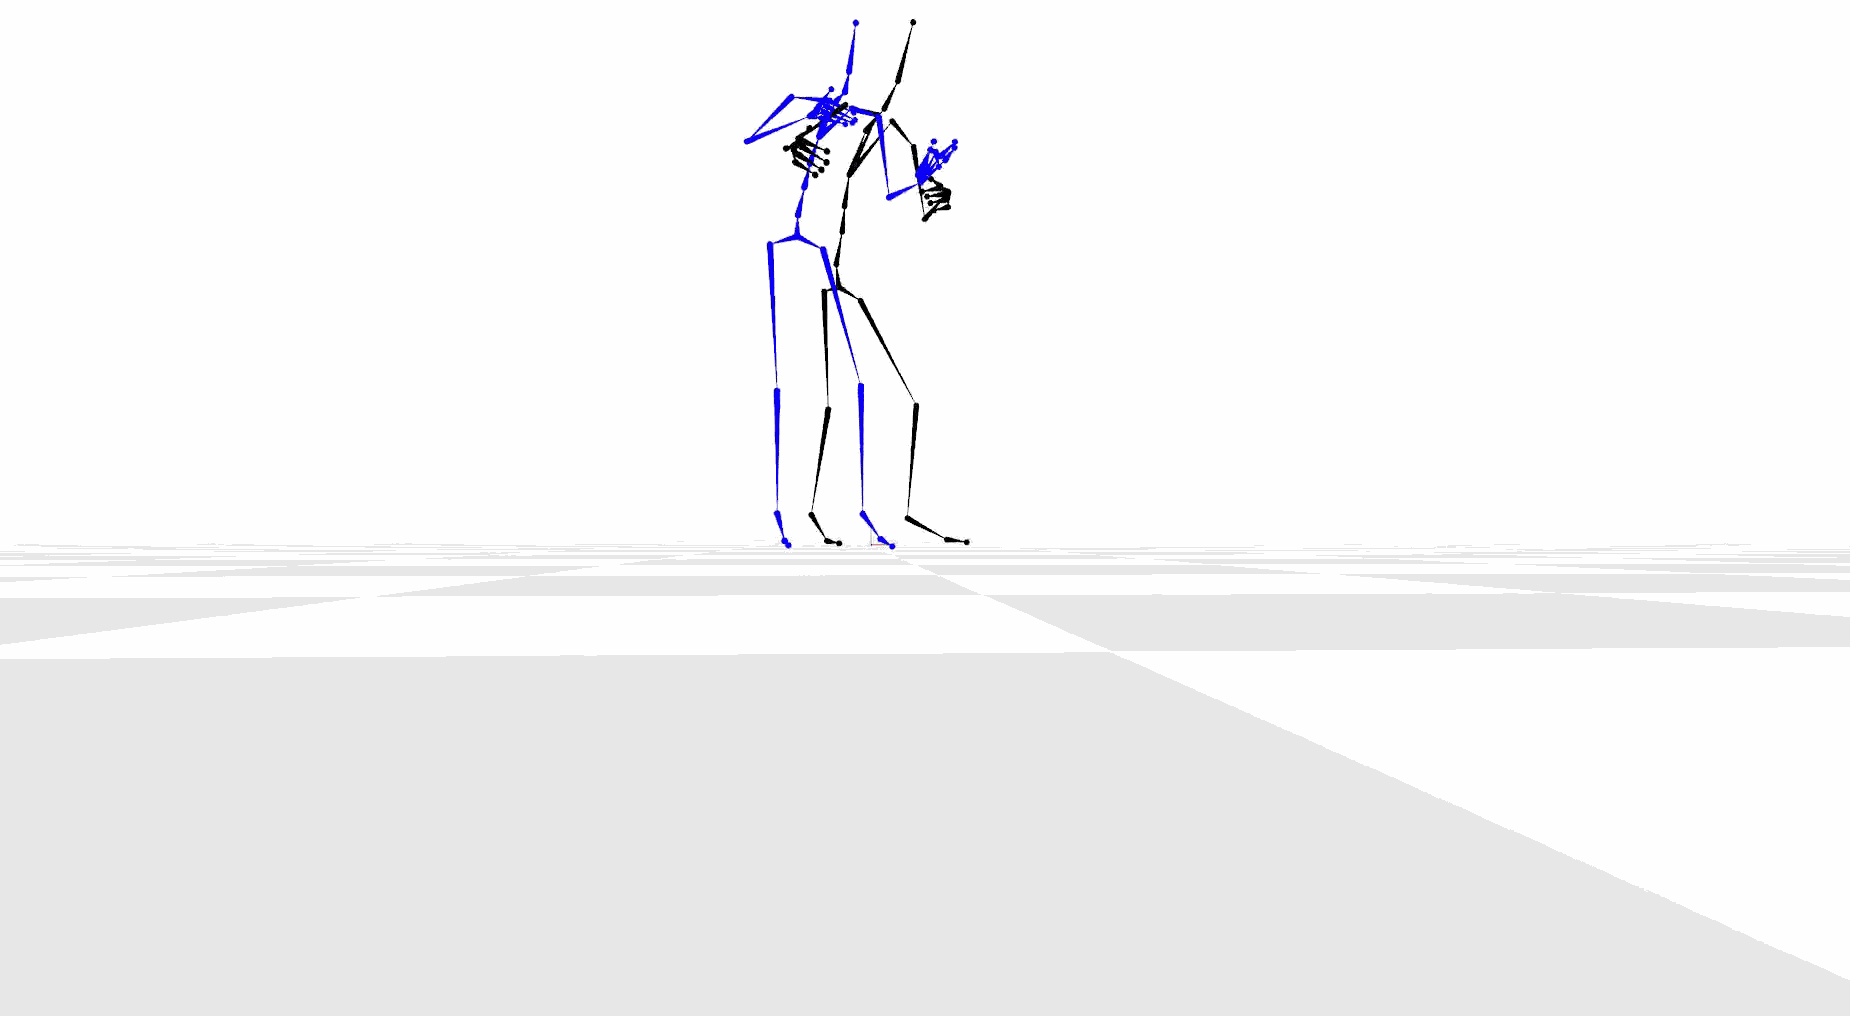
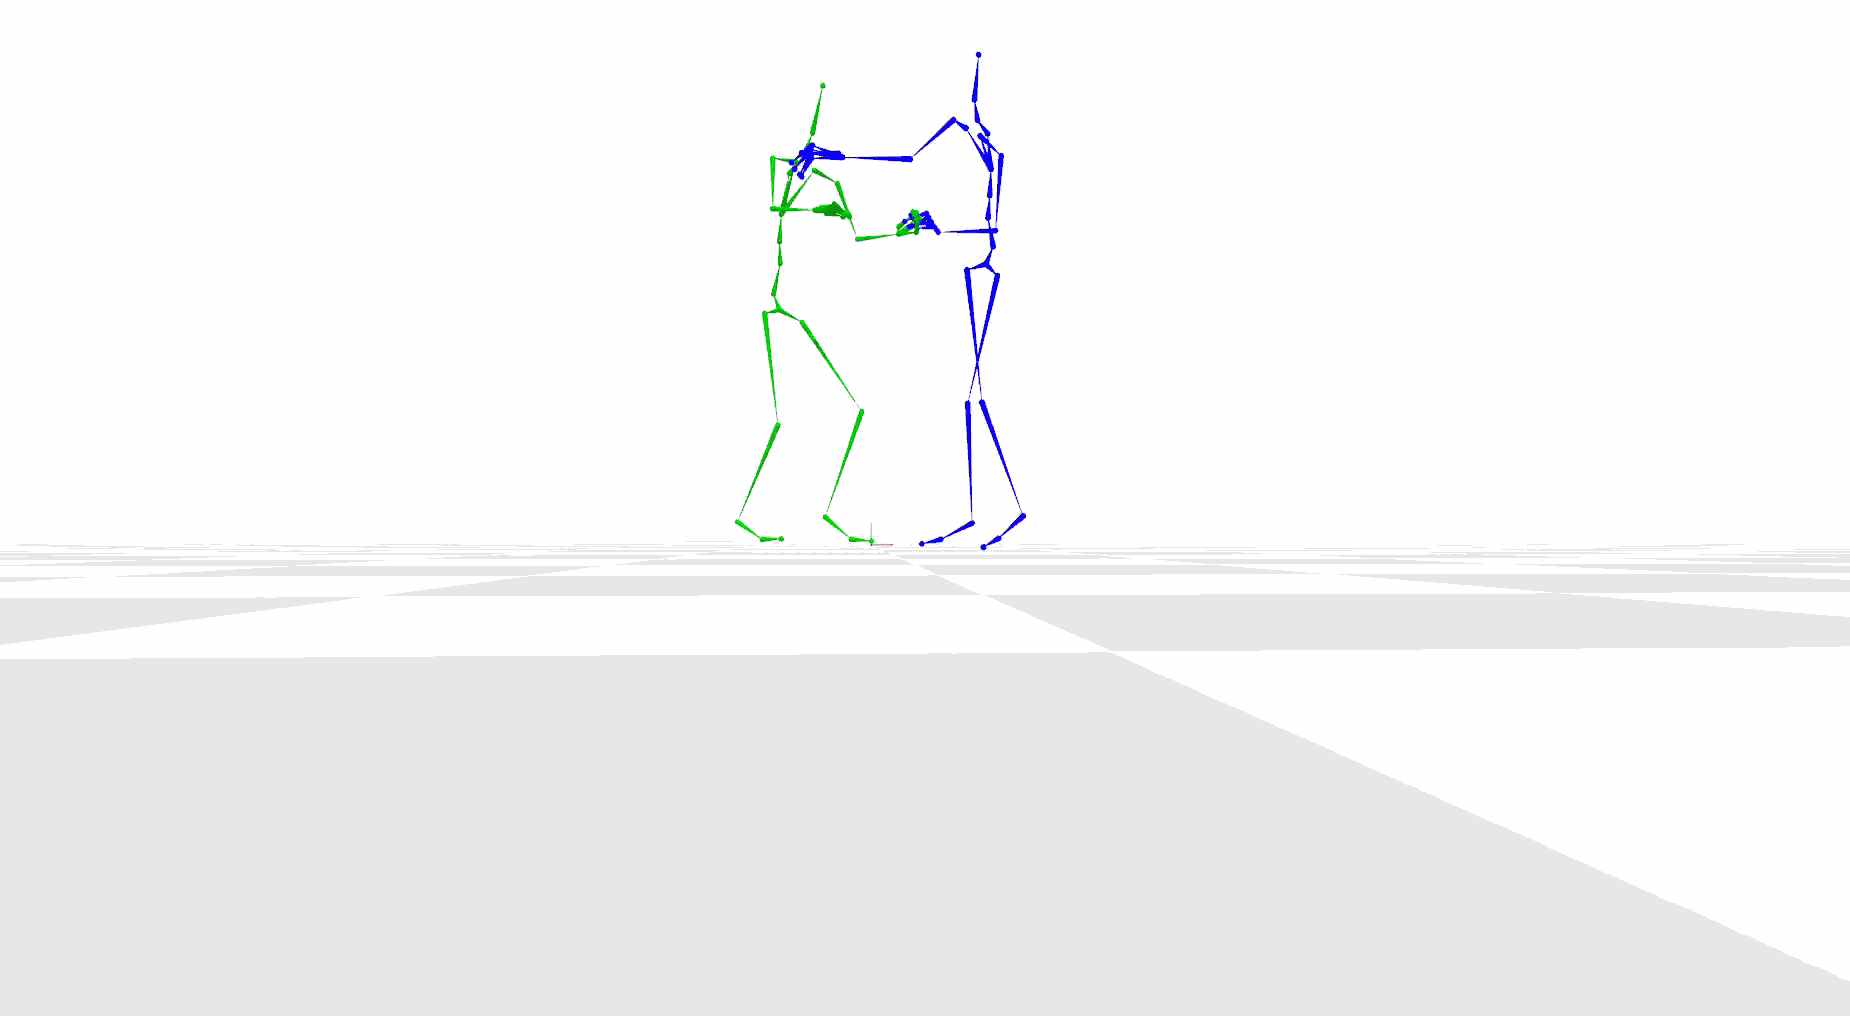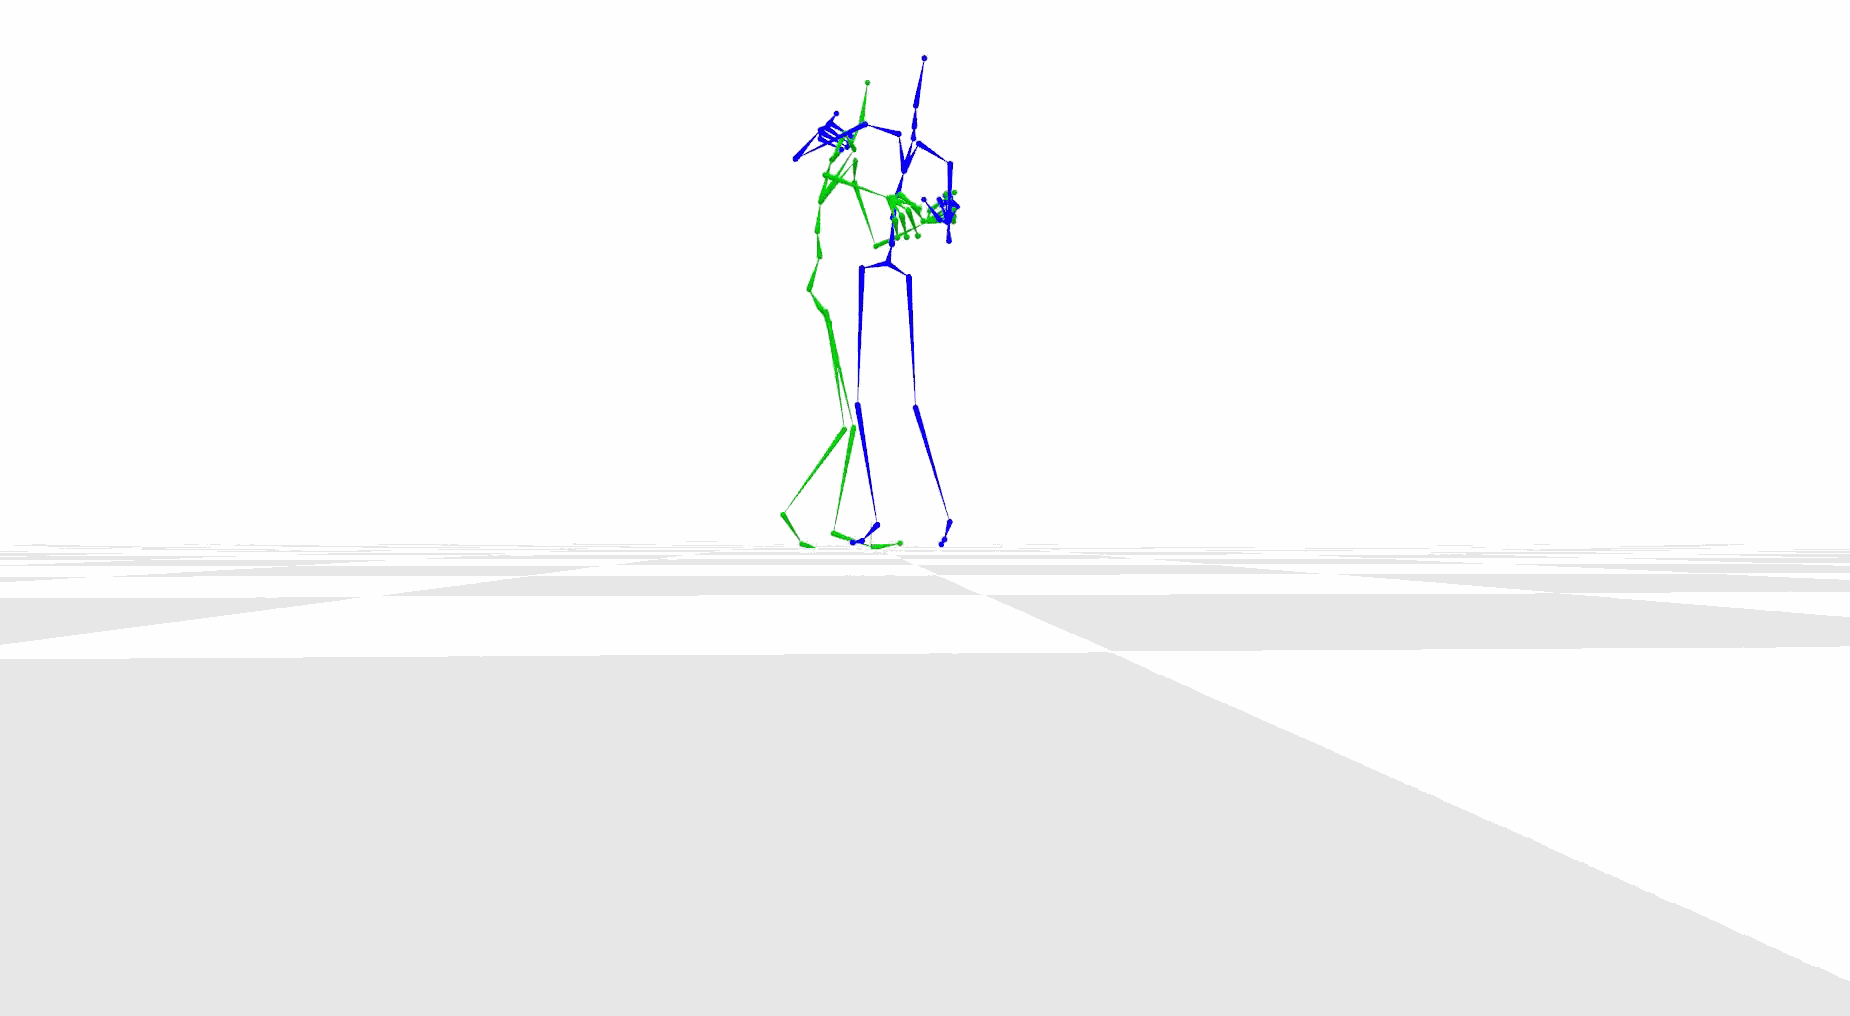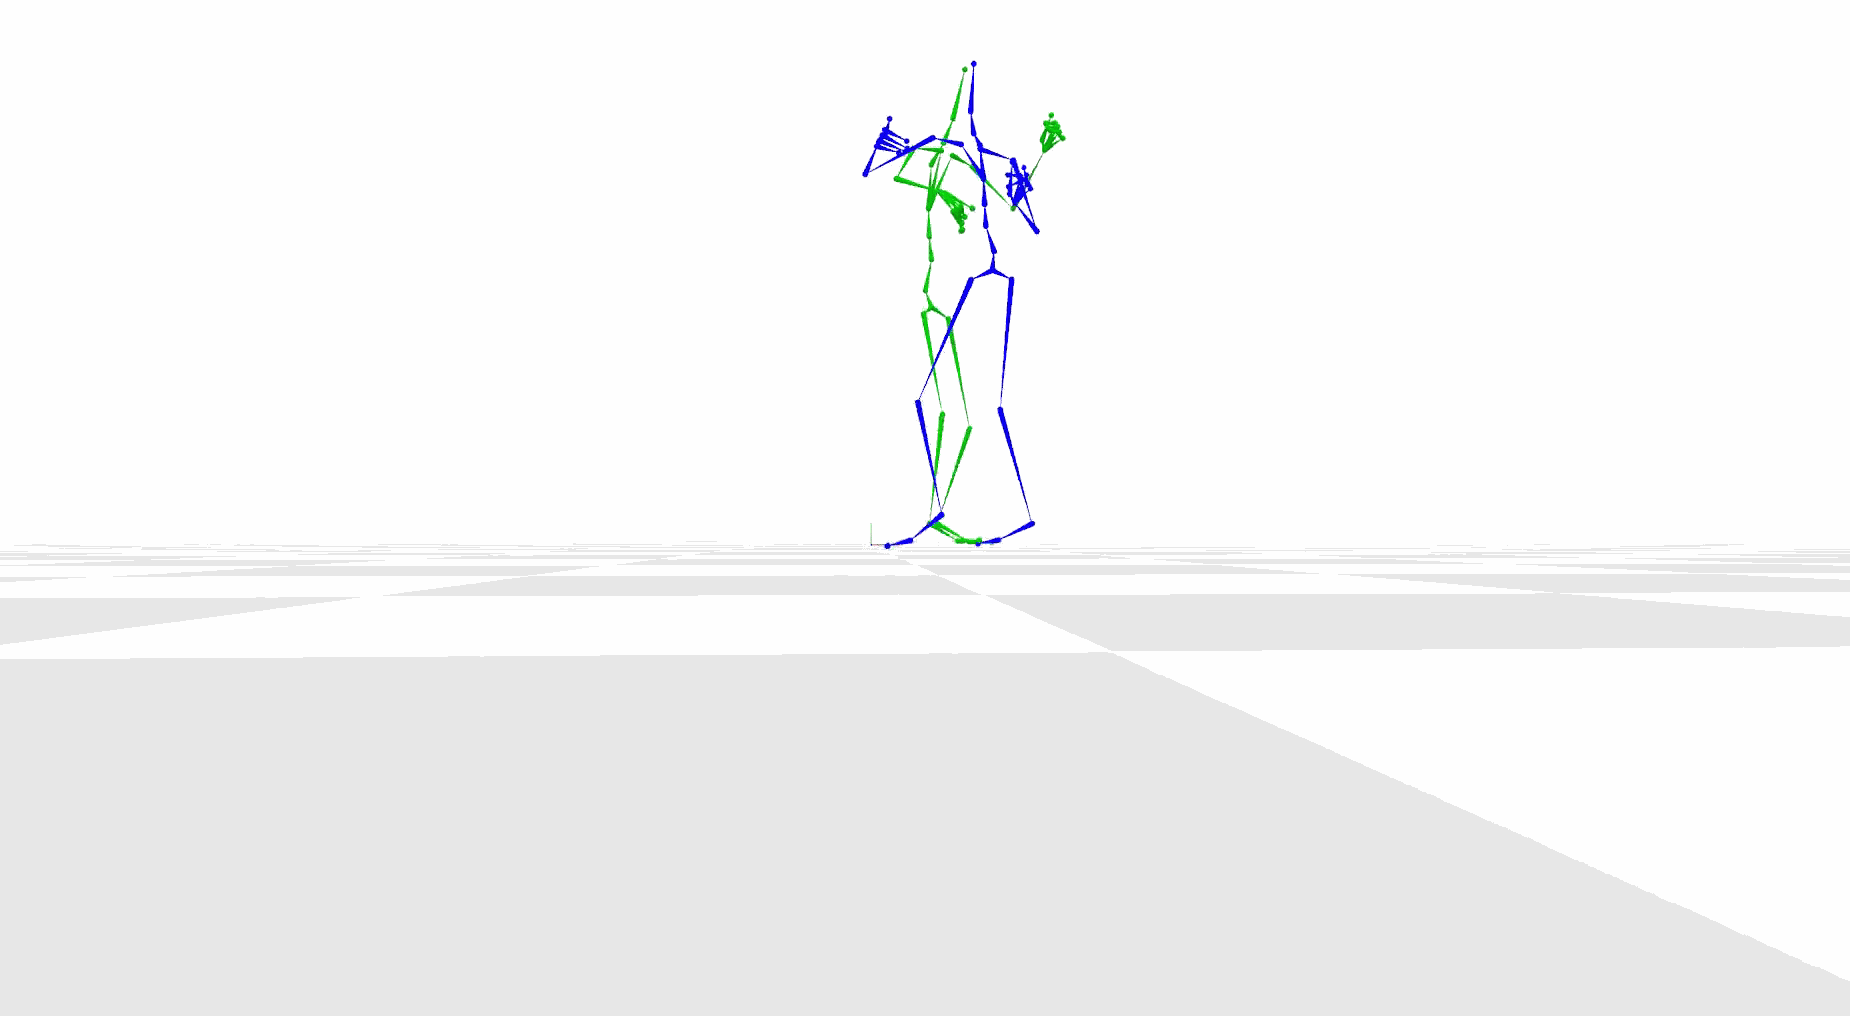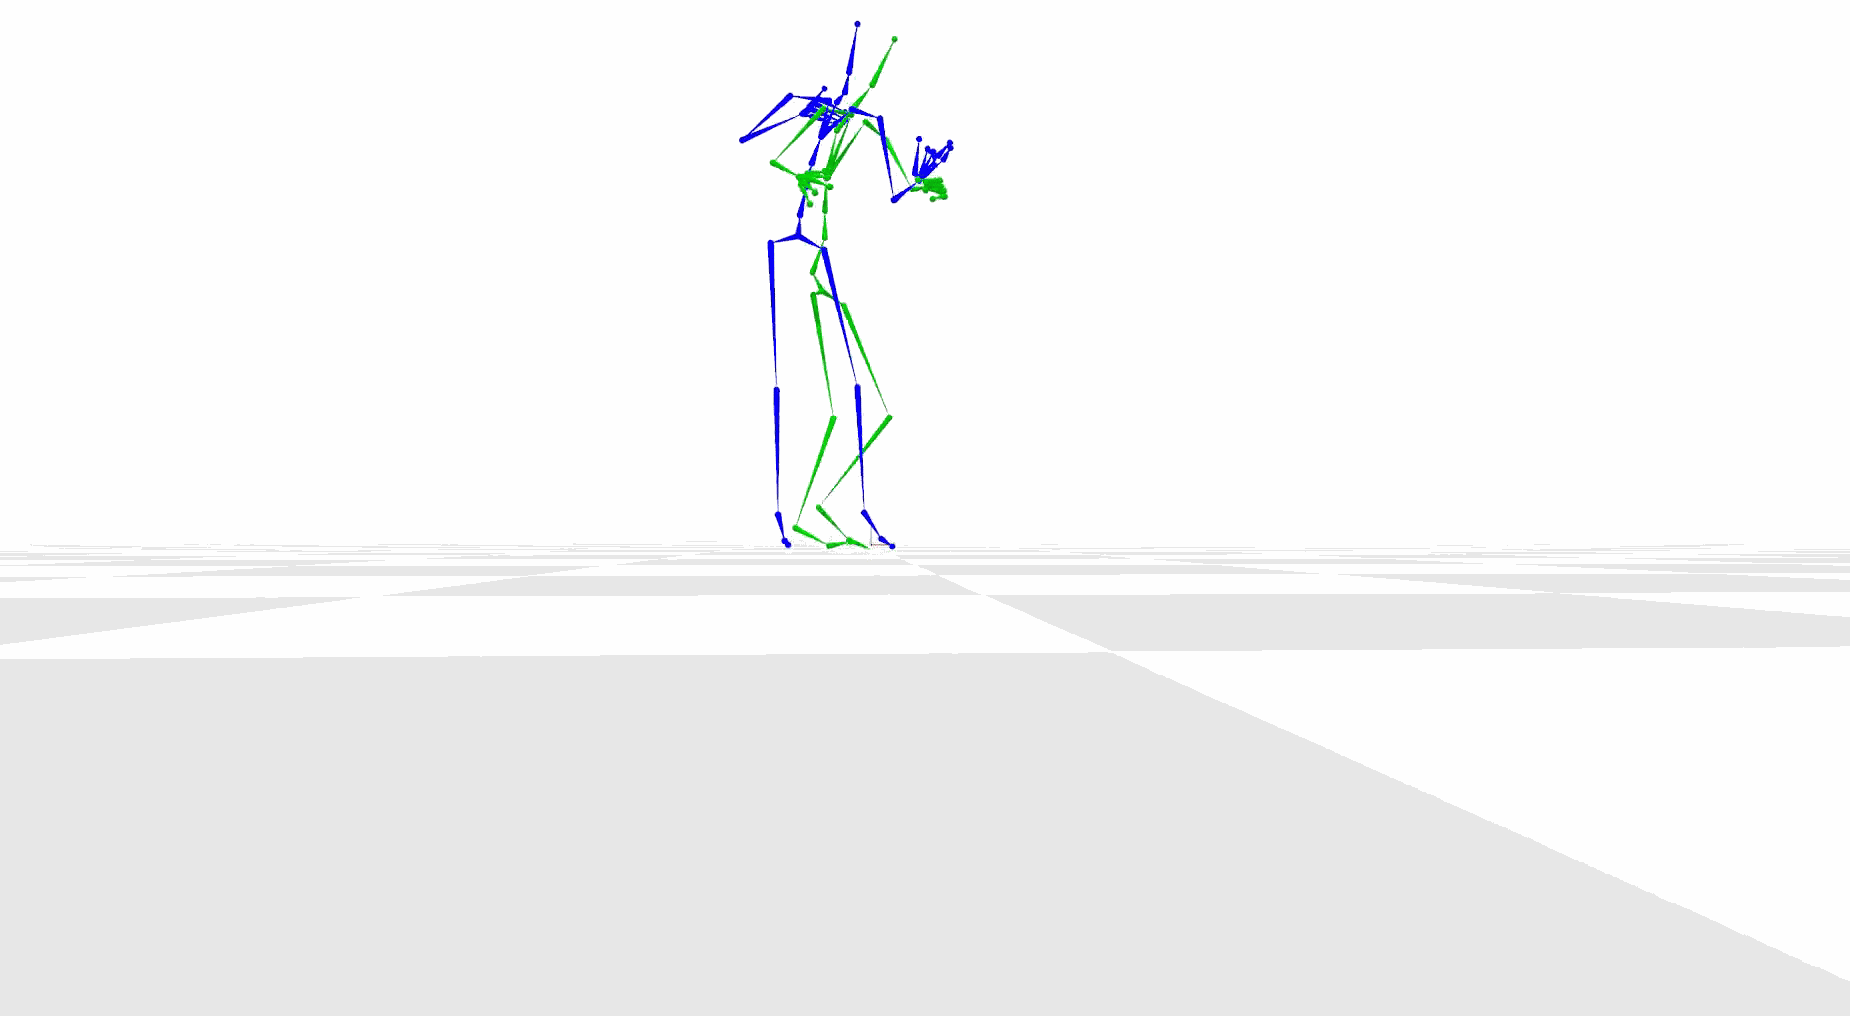
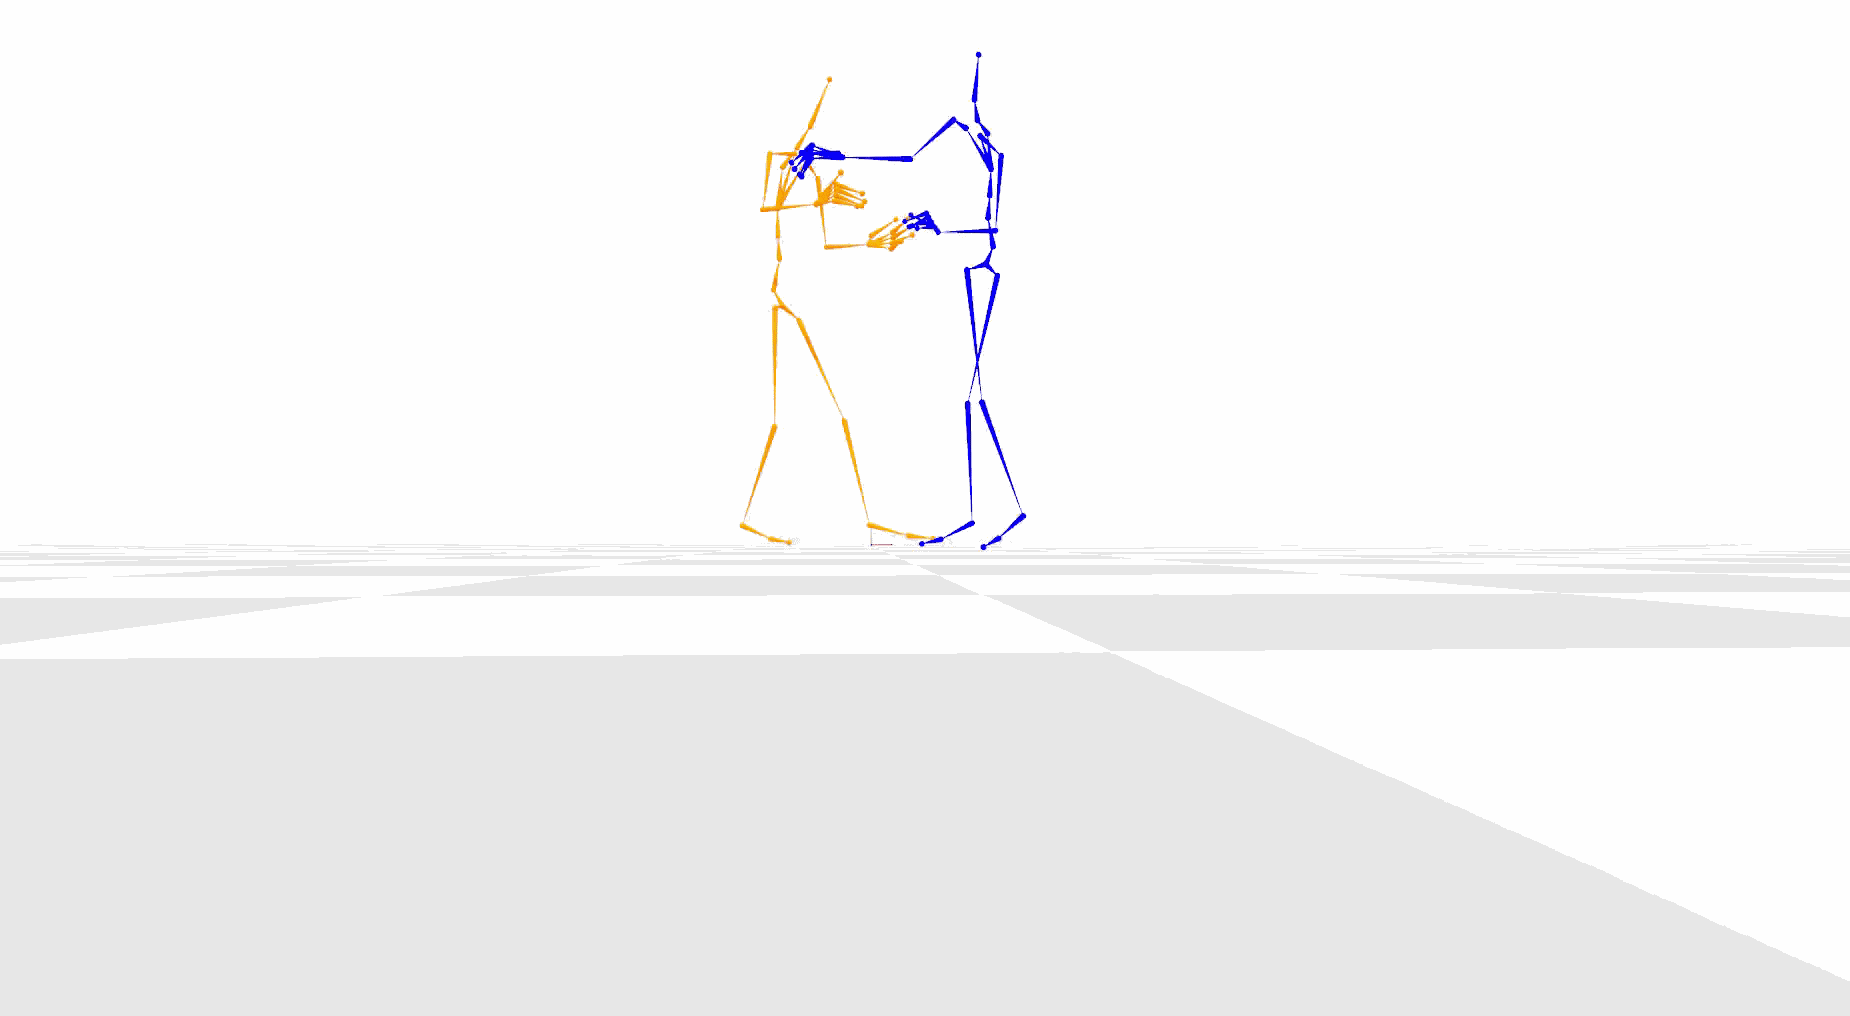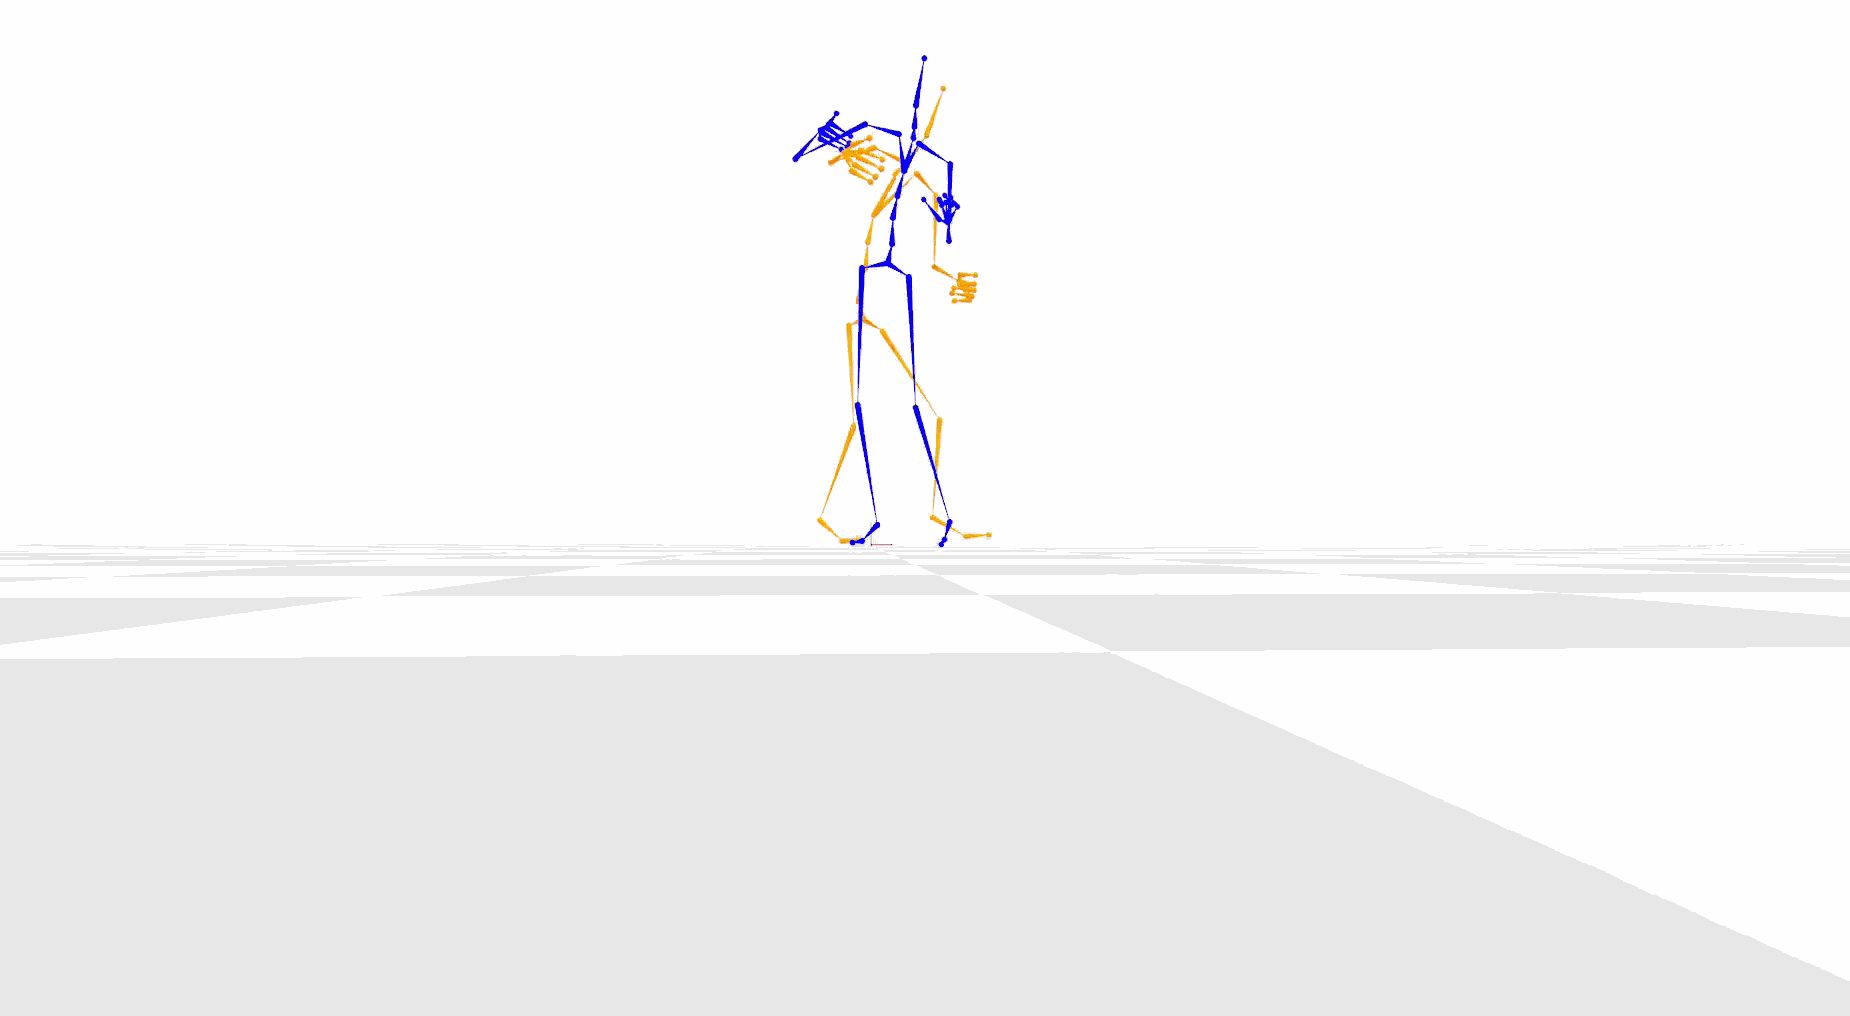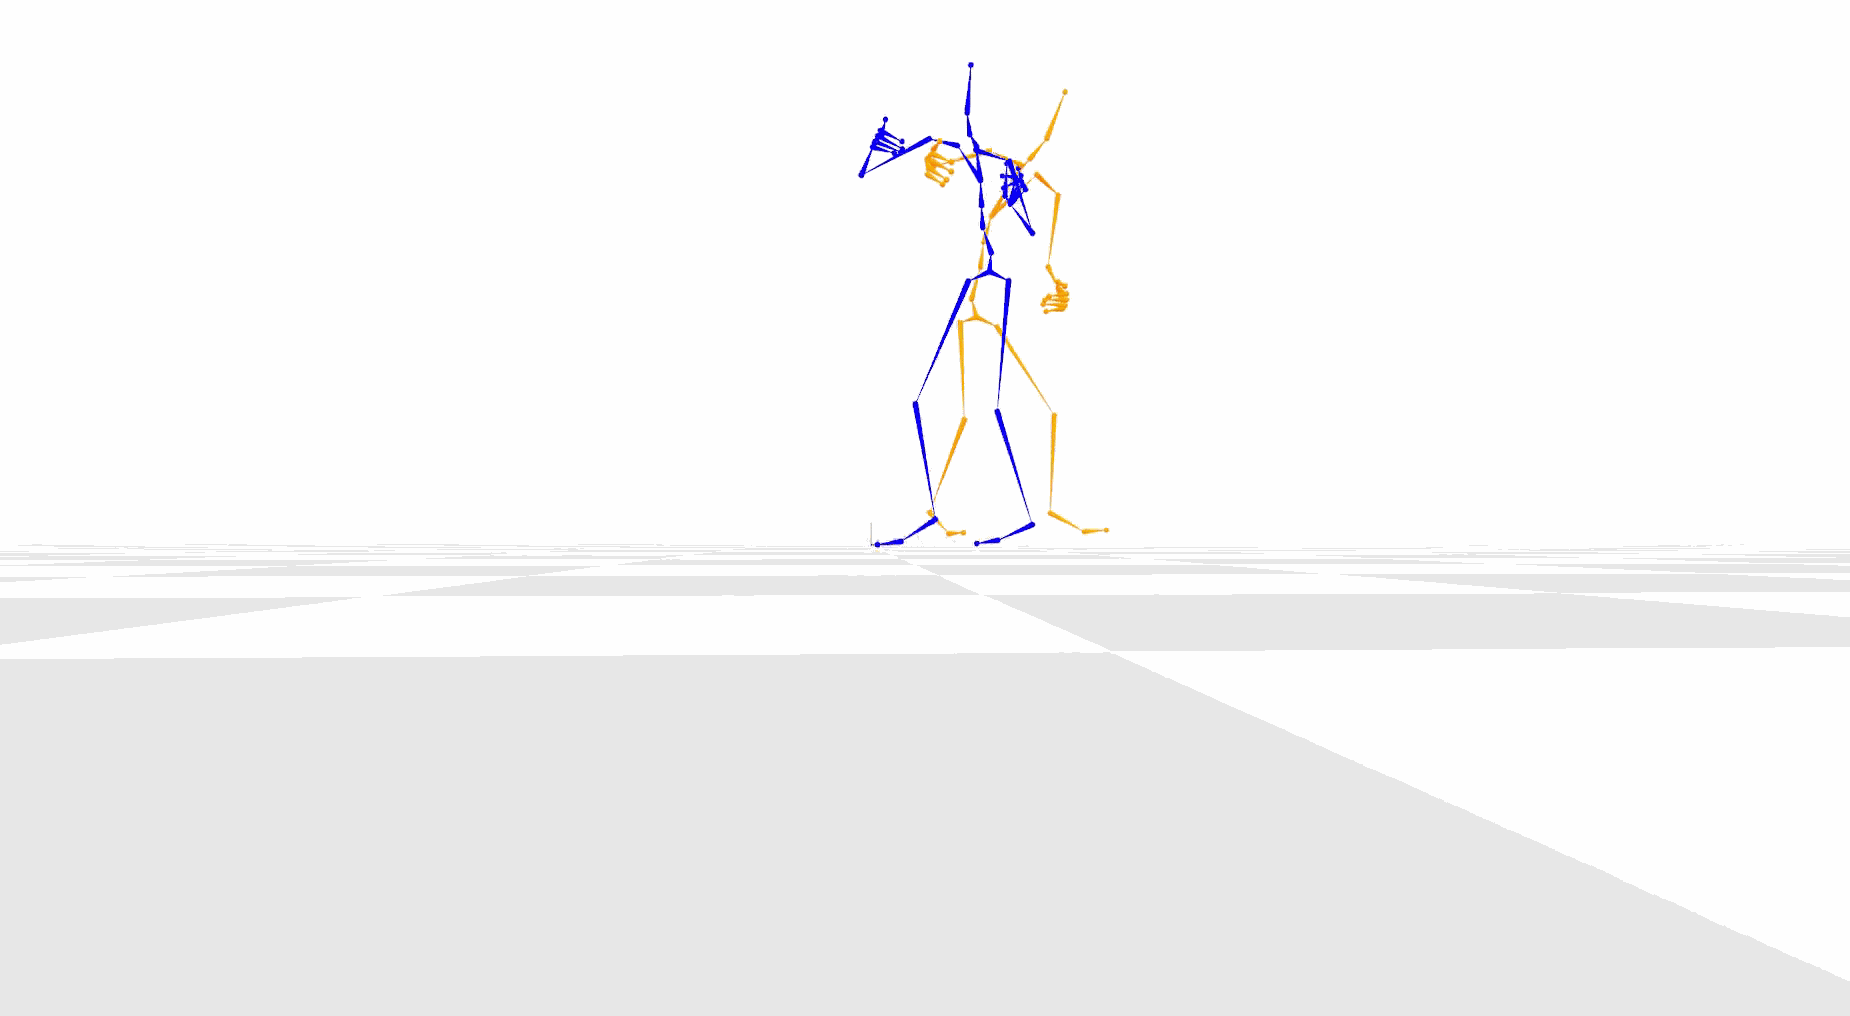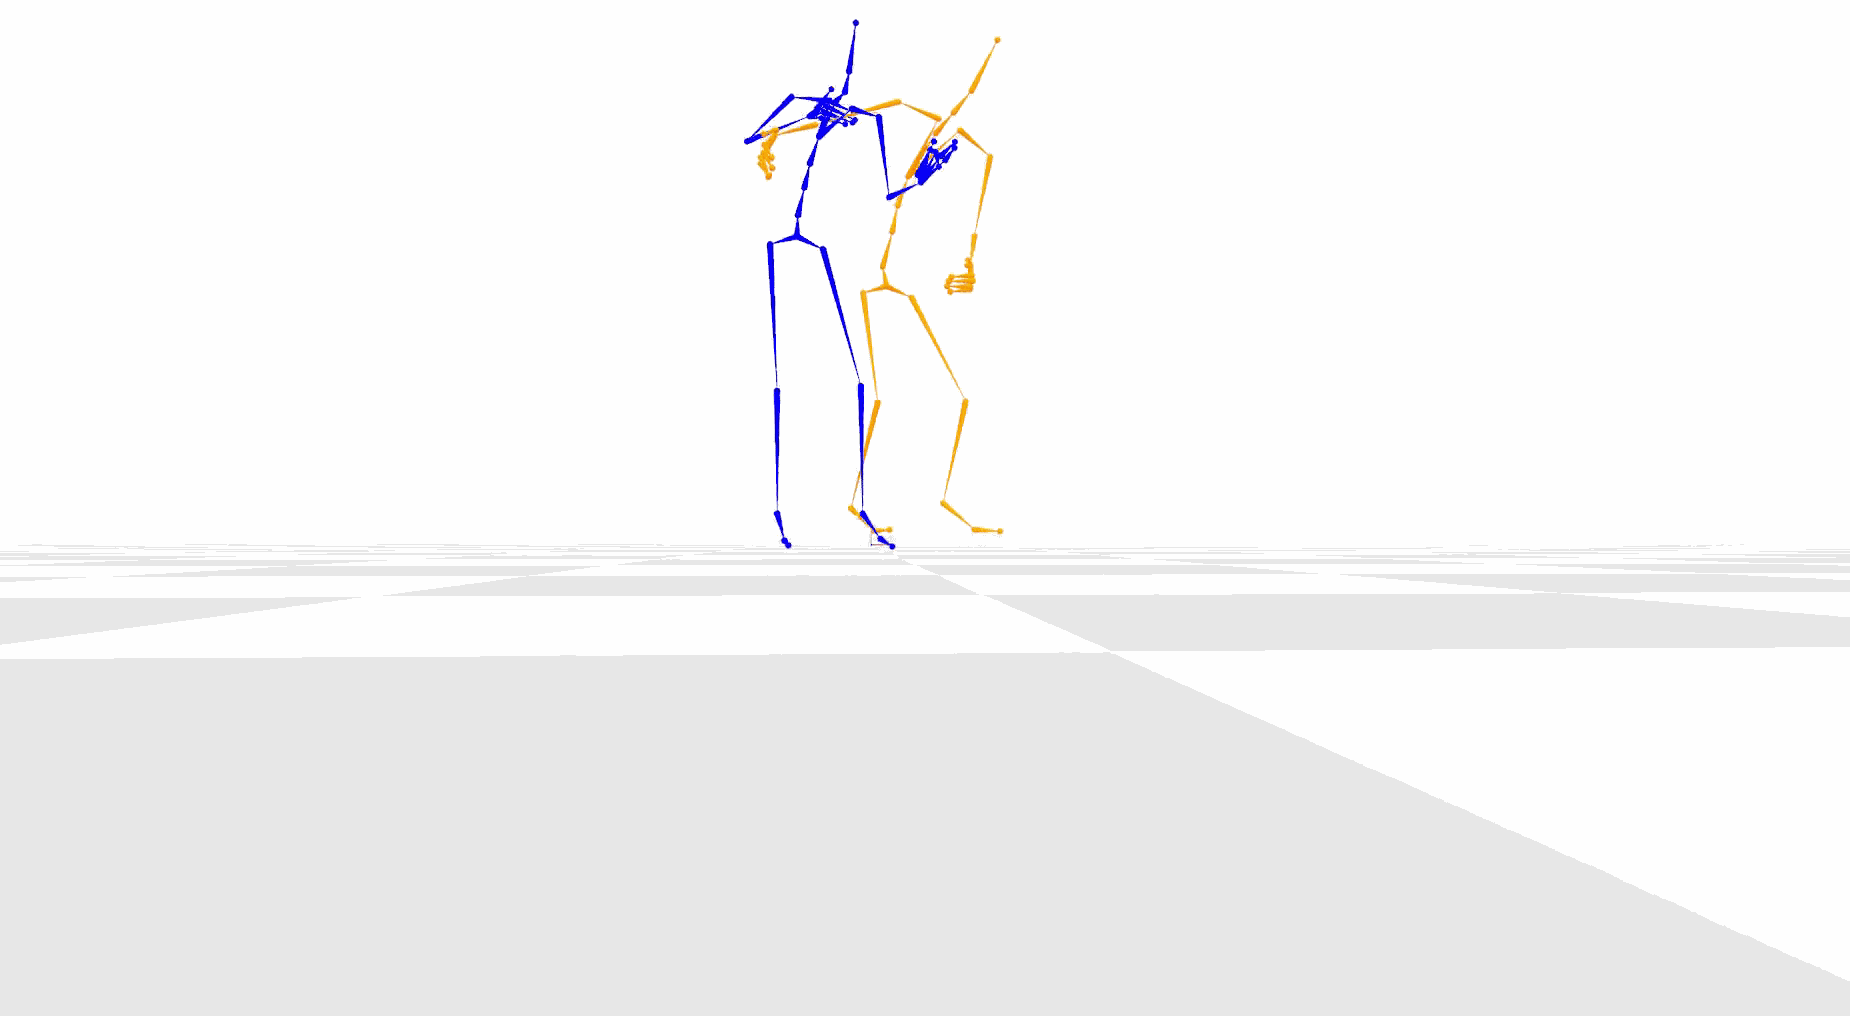
We present ReactionMamba, a framework for generating short and long 3D human reaction motions. ReactionMamba integrates a motion variational autoencoder with Mamba-based state-space models to decode temporally consistent reactions. The model generates reaction sequences conditioned on the observed actor motion and the initial pose of the reactor.
We evaluate ReactionMamba on NTU120-AS, Lindy Hop, and InterX, demonstrating competitive performance in realism, diversity, and long-sequence generation, while achieving substantial improvements in inference speed.